Reproducing pancreatic endocrinogenesis
Source:vignettes/reproduce-pancreatic-endocrinogenesis.Rmd
reproduce-pancreatic-endocrinogenesis.RmdThis article reproduces the main analytical logic of a pancreatic
endocrinogenesis study using the bundled pancreas_sub
object. The biological reference is the mouse embryonic pancreas
single-cell study by Bastidas-Ponce et al. (2019, Development,
DOI: 10.1242/dev.173849).
The website executes preprocessing, marker plots, Slingshot and Monocle3 trajectories, native C++ velocity, and dynamic-expression fitting on all bundled cells. The regulatory-network and database-enrichment extensions below are explicitly marked as code-only recipes: they require separately prepared Python environments and external resources, and are not results of this page’s render.
The goal is a compact, runnable reproduction rather than a one-to-one rebuild of every original figure. The workflow keeps the same evidence chain: identify ductal, endocrine progenitor, pre-endocrine, and endocrine states; order them along developmental trajectories; find dynamic genes; then connect downstream transcription factors, regulatory network structure, marker genes, and pathway terms.
Reproduction Scope
The default dataset is a small annotated subset, so it is suitable for local article rendering and interactive exploration. It can support the following questions:
- whether ductal, Ngn3-positive endocrine progenitor, pre-endocrine, alpha, beta, delta, and epsilon states form an ordered manifold;
- whether known endocrine-development genes vary along this manifold;
- whether dynamic genes and TF activity recover expected regulators
such as
Neurog3,Fev,Neurod1,Pdx1,Arx,Pax4,Mafb,Rfx6,Isl1, andInsm1; - whether differential genes and enriched terms agree with endocrine differentiation and hormone-producing cell states.
Load and Process the Dataset
Prepare Slingshot and Monocle3 before rendering, and use a current
thisutils build that exports fit_trends. Older
thisutils builds may carry the same version number but lack
that API; the read-only preflight below detects this.
Start from the package object and run the standard single-cell preprocessing workflow. This creates normalized expression, variable features, scaled data, PCA, neighbor graph, clustering, and UMAP coordinates.
library(scop)
stopifnot(
  all(unlist(thisutils::check_r("slingshot", install = FALSE, verbose = FALSE))),
  all(unlist(thisutils::check_r("cole-trapnell-lab/monocle3", install = FALSE, verbose = FALSE))),
  "fit_trends" %in% getNamespaceExports("thisutils")
)
set.seed(11)

data(pancreas_sub)
input_cells <- colnames(pancreas_sub)

pancreas_sub <- RunStandardWorkflow(
  pancreas_sub,
  assay = "RNA",
  nHVF = 2000,
  linear_reduction_dims = 50,
  cluster_resolution = 0.6,
  seed = 11, cores = 1,
  verbose = FALSE
)

pancreas_sub <- RunCellQC(pancreas_sub,
  assay = "RNA",
  qc_metrics = c("umi", "gene", "mito"), return_filtered = FALSE, verbose = FALSE
)
stopifnot(identical(colnames(pancreas_sub), input_cells))

data.frame(
  genes = nrow(pancreas_sub),
  cells = ncol(pancreas_sub),
  cell_states = length(unique(pancreas_sub$SubCellType))
)
#>   genes cells cell_states
#> 1 15998  1000           8

head(sort(table(pancreas_sub$SubCellType), decreasing = TRUE), 8)
#>
#>        Ductal          Beta  Ngn3-high-EP Pre-endocrine         Alpha
#>           253           174           169           156           121
#>   Ngn3-low-EP       Epsilon         Delta
#>            67            40            20
Check Cell States and Markers
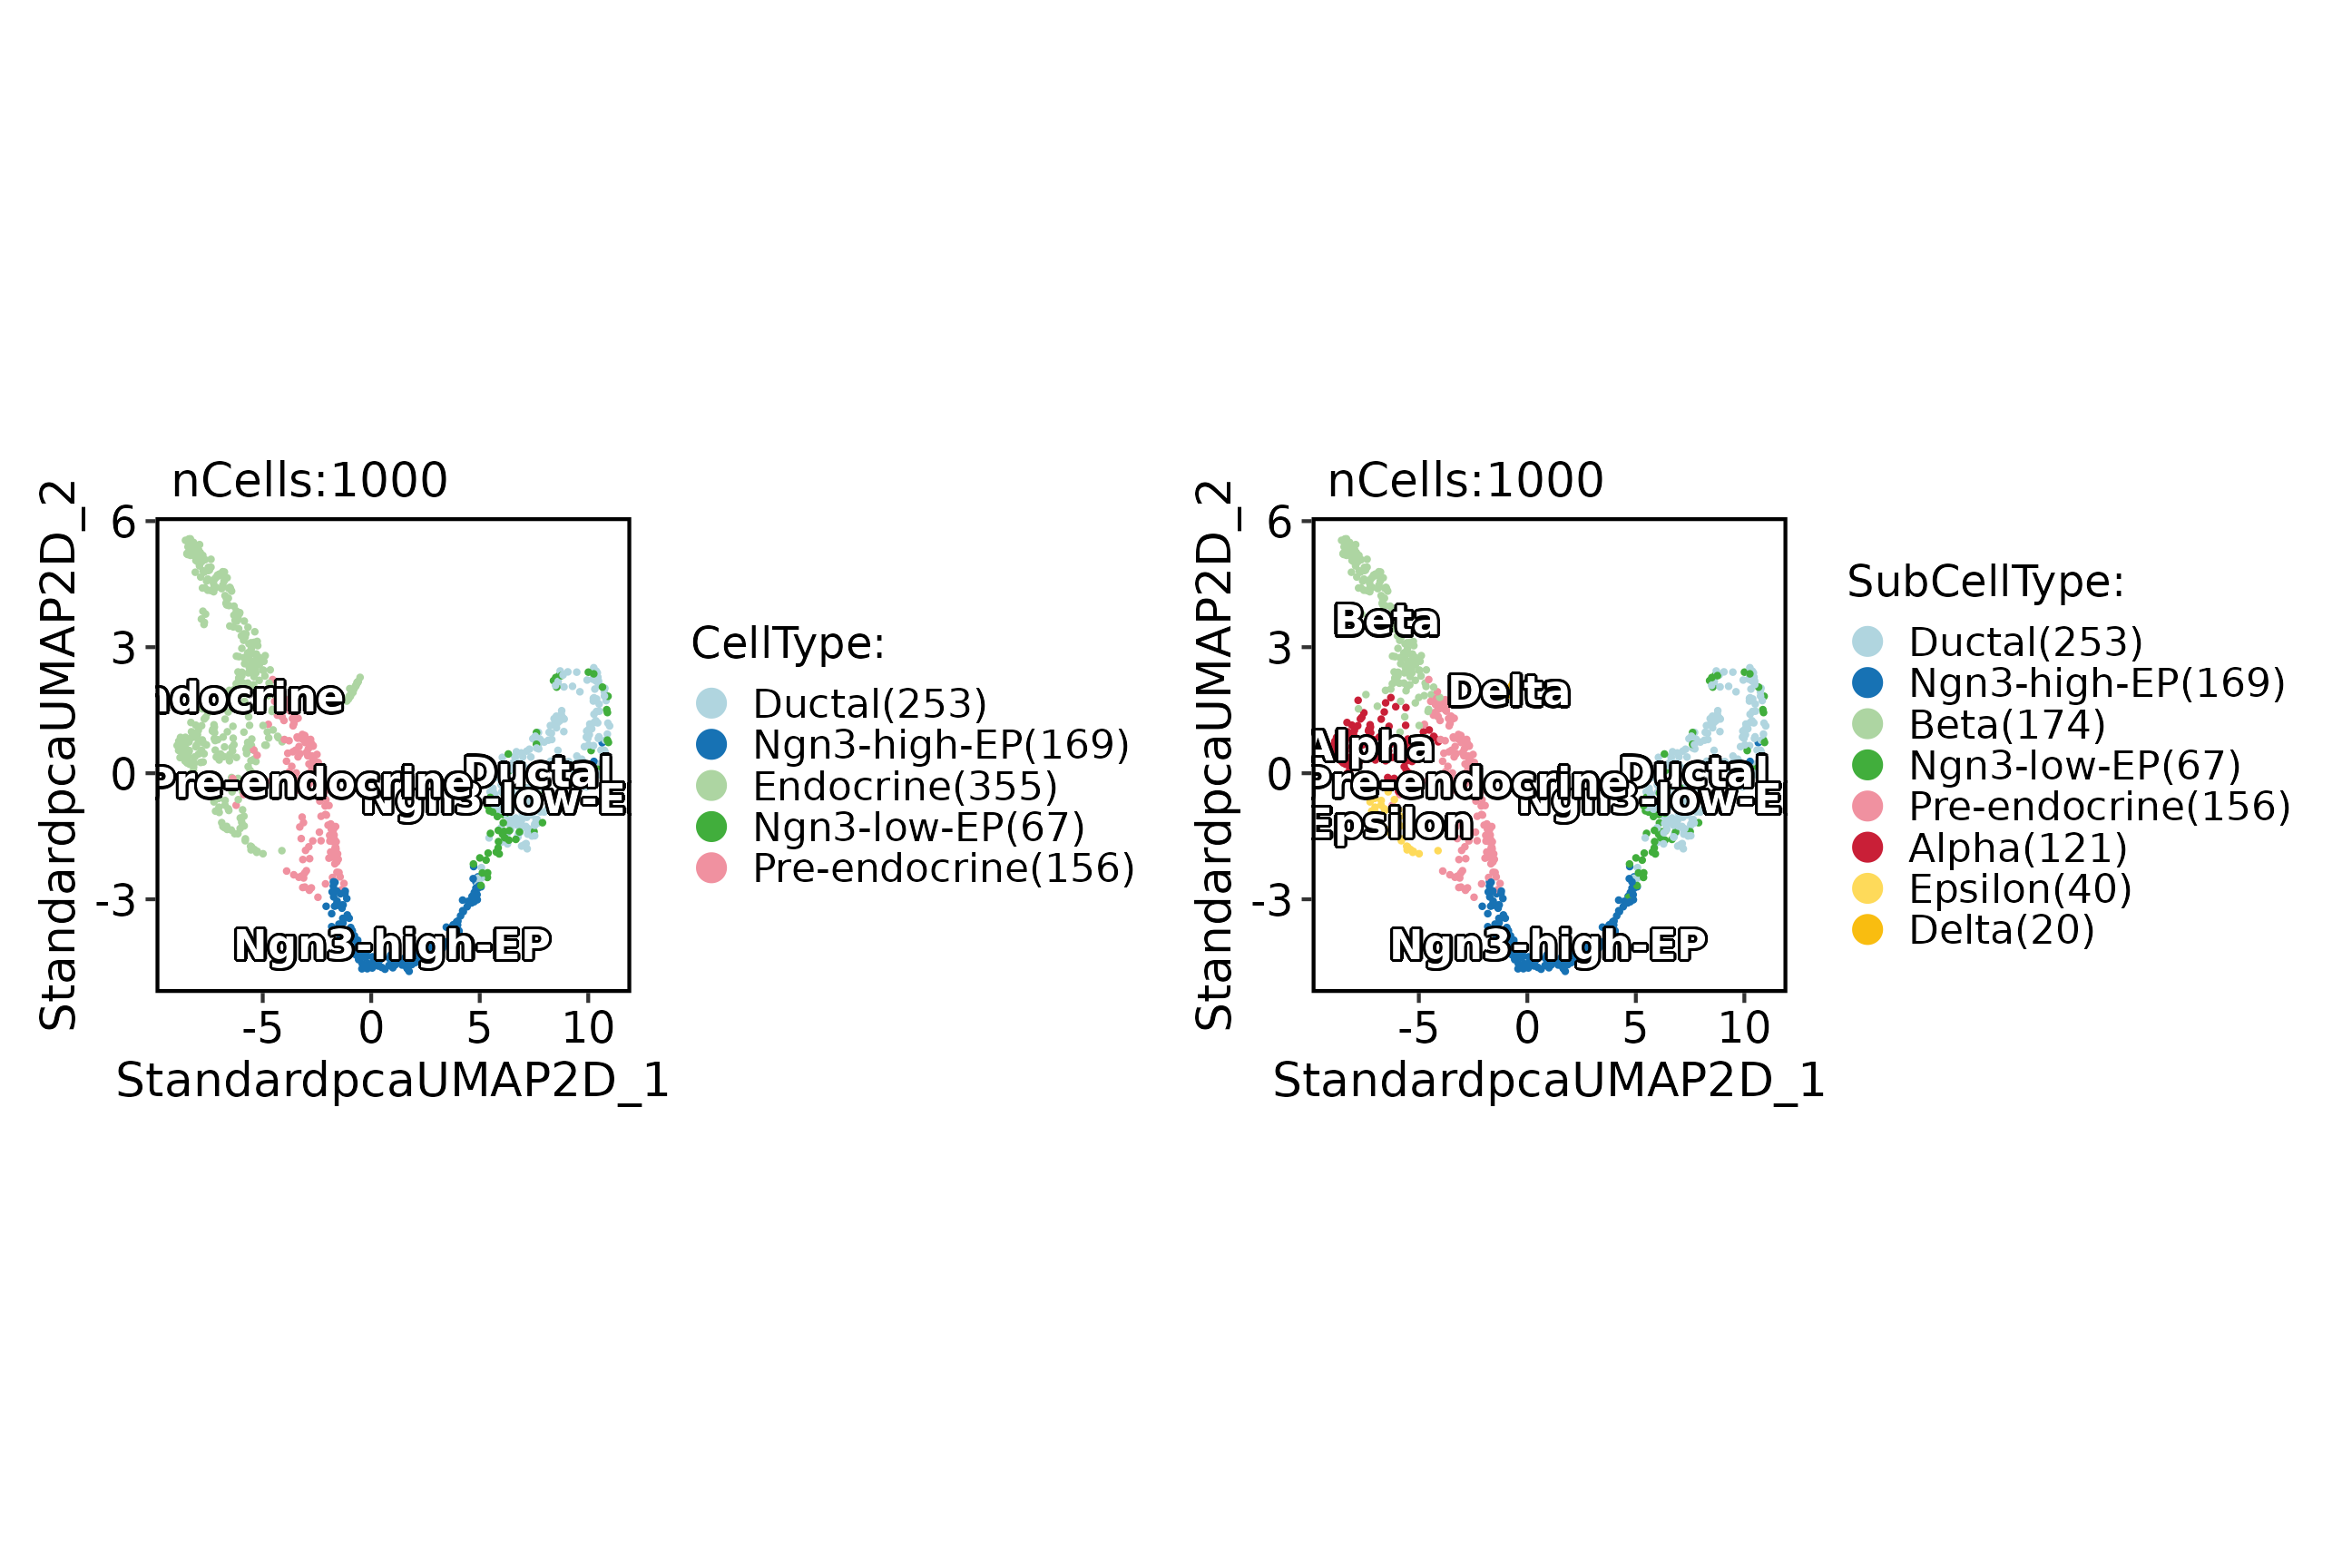
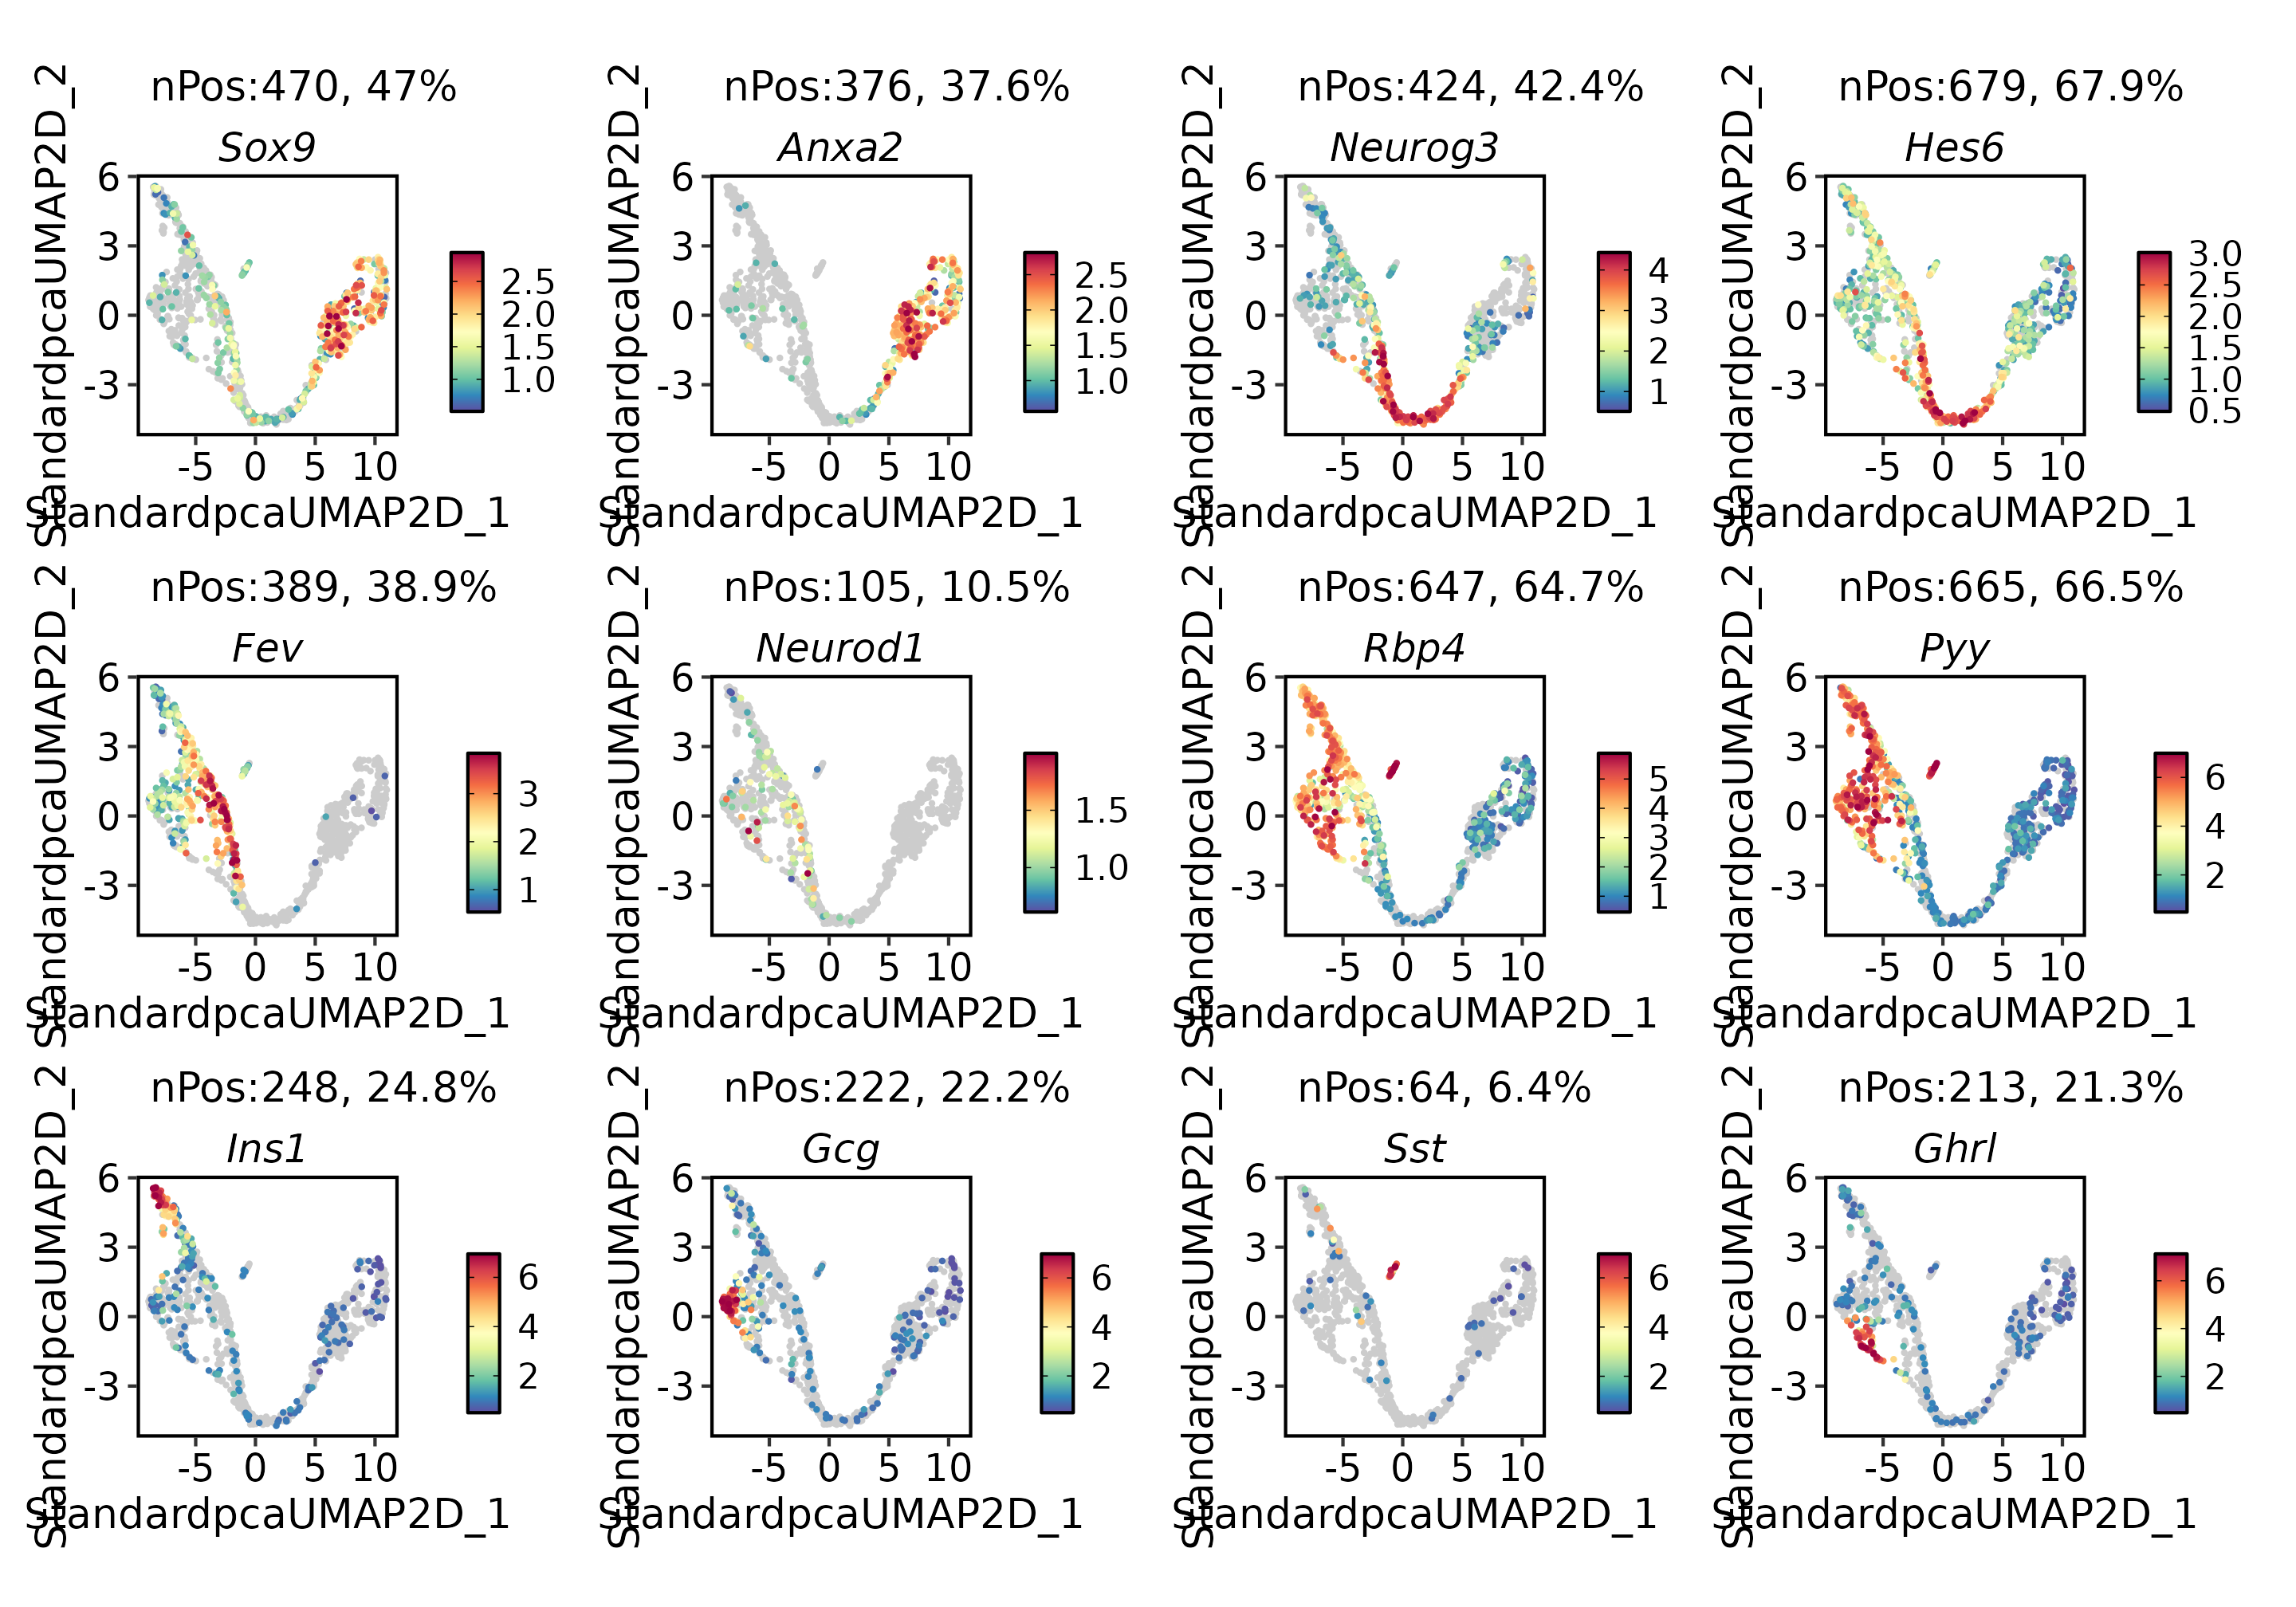
The first reproduction step is to confirm that the annotated cell
states and canonical marker genes match the expected developmental
progression. Ductal markers support the root state; Neurog3
marks endocrine progenitors; Fev and Neurod1
mark pre-endocrine cells; hormone genes separate terminal endocrine
states.
CellDimPlot(
  pancreas_sub,
  group.by = c("CellType", "SubCellType"),
  reduction = "UMAP",
  label = TRUE
)
pancreas_markers <- c(
  "Sox9", "Anxa2",
  "Neurog3", "Hes6",
  "Fev", "Neurod1",
  "Rbp4", "Pyy",
  "Ins1", "Gcg", "Sst", "Ghrl"
)

FeatureDimPlot(
  pancreas_sub,
  features = pancreas_markers,
  reduction = "UMAP",
  ncol = 4
)
ht_markers <- GroupHeatmap(
  pancreas_sub,
  features = pancreas_markers,
  group.by = c("CellType", "SubCellType"),
  heatmap_palette = "Spectral",
  show_row_names = TRUE,
  add_dot = TRUE,
  add_reticle = TRUE
)
print(ht_markers$plot)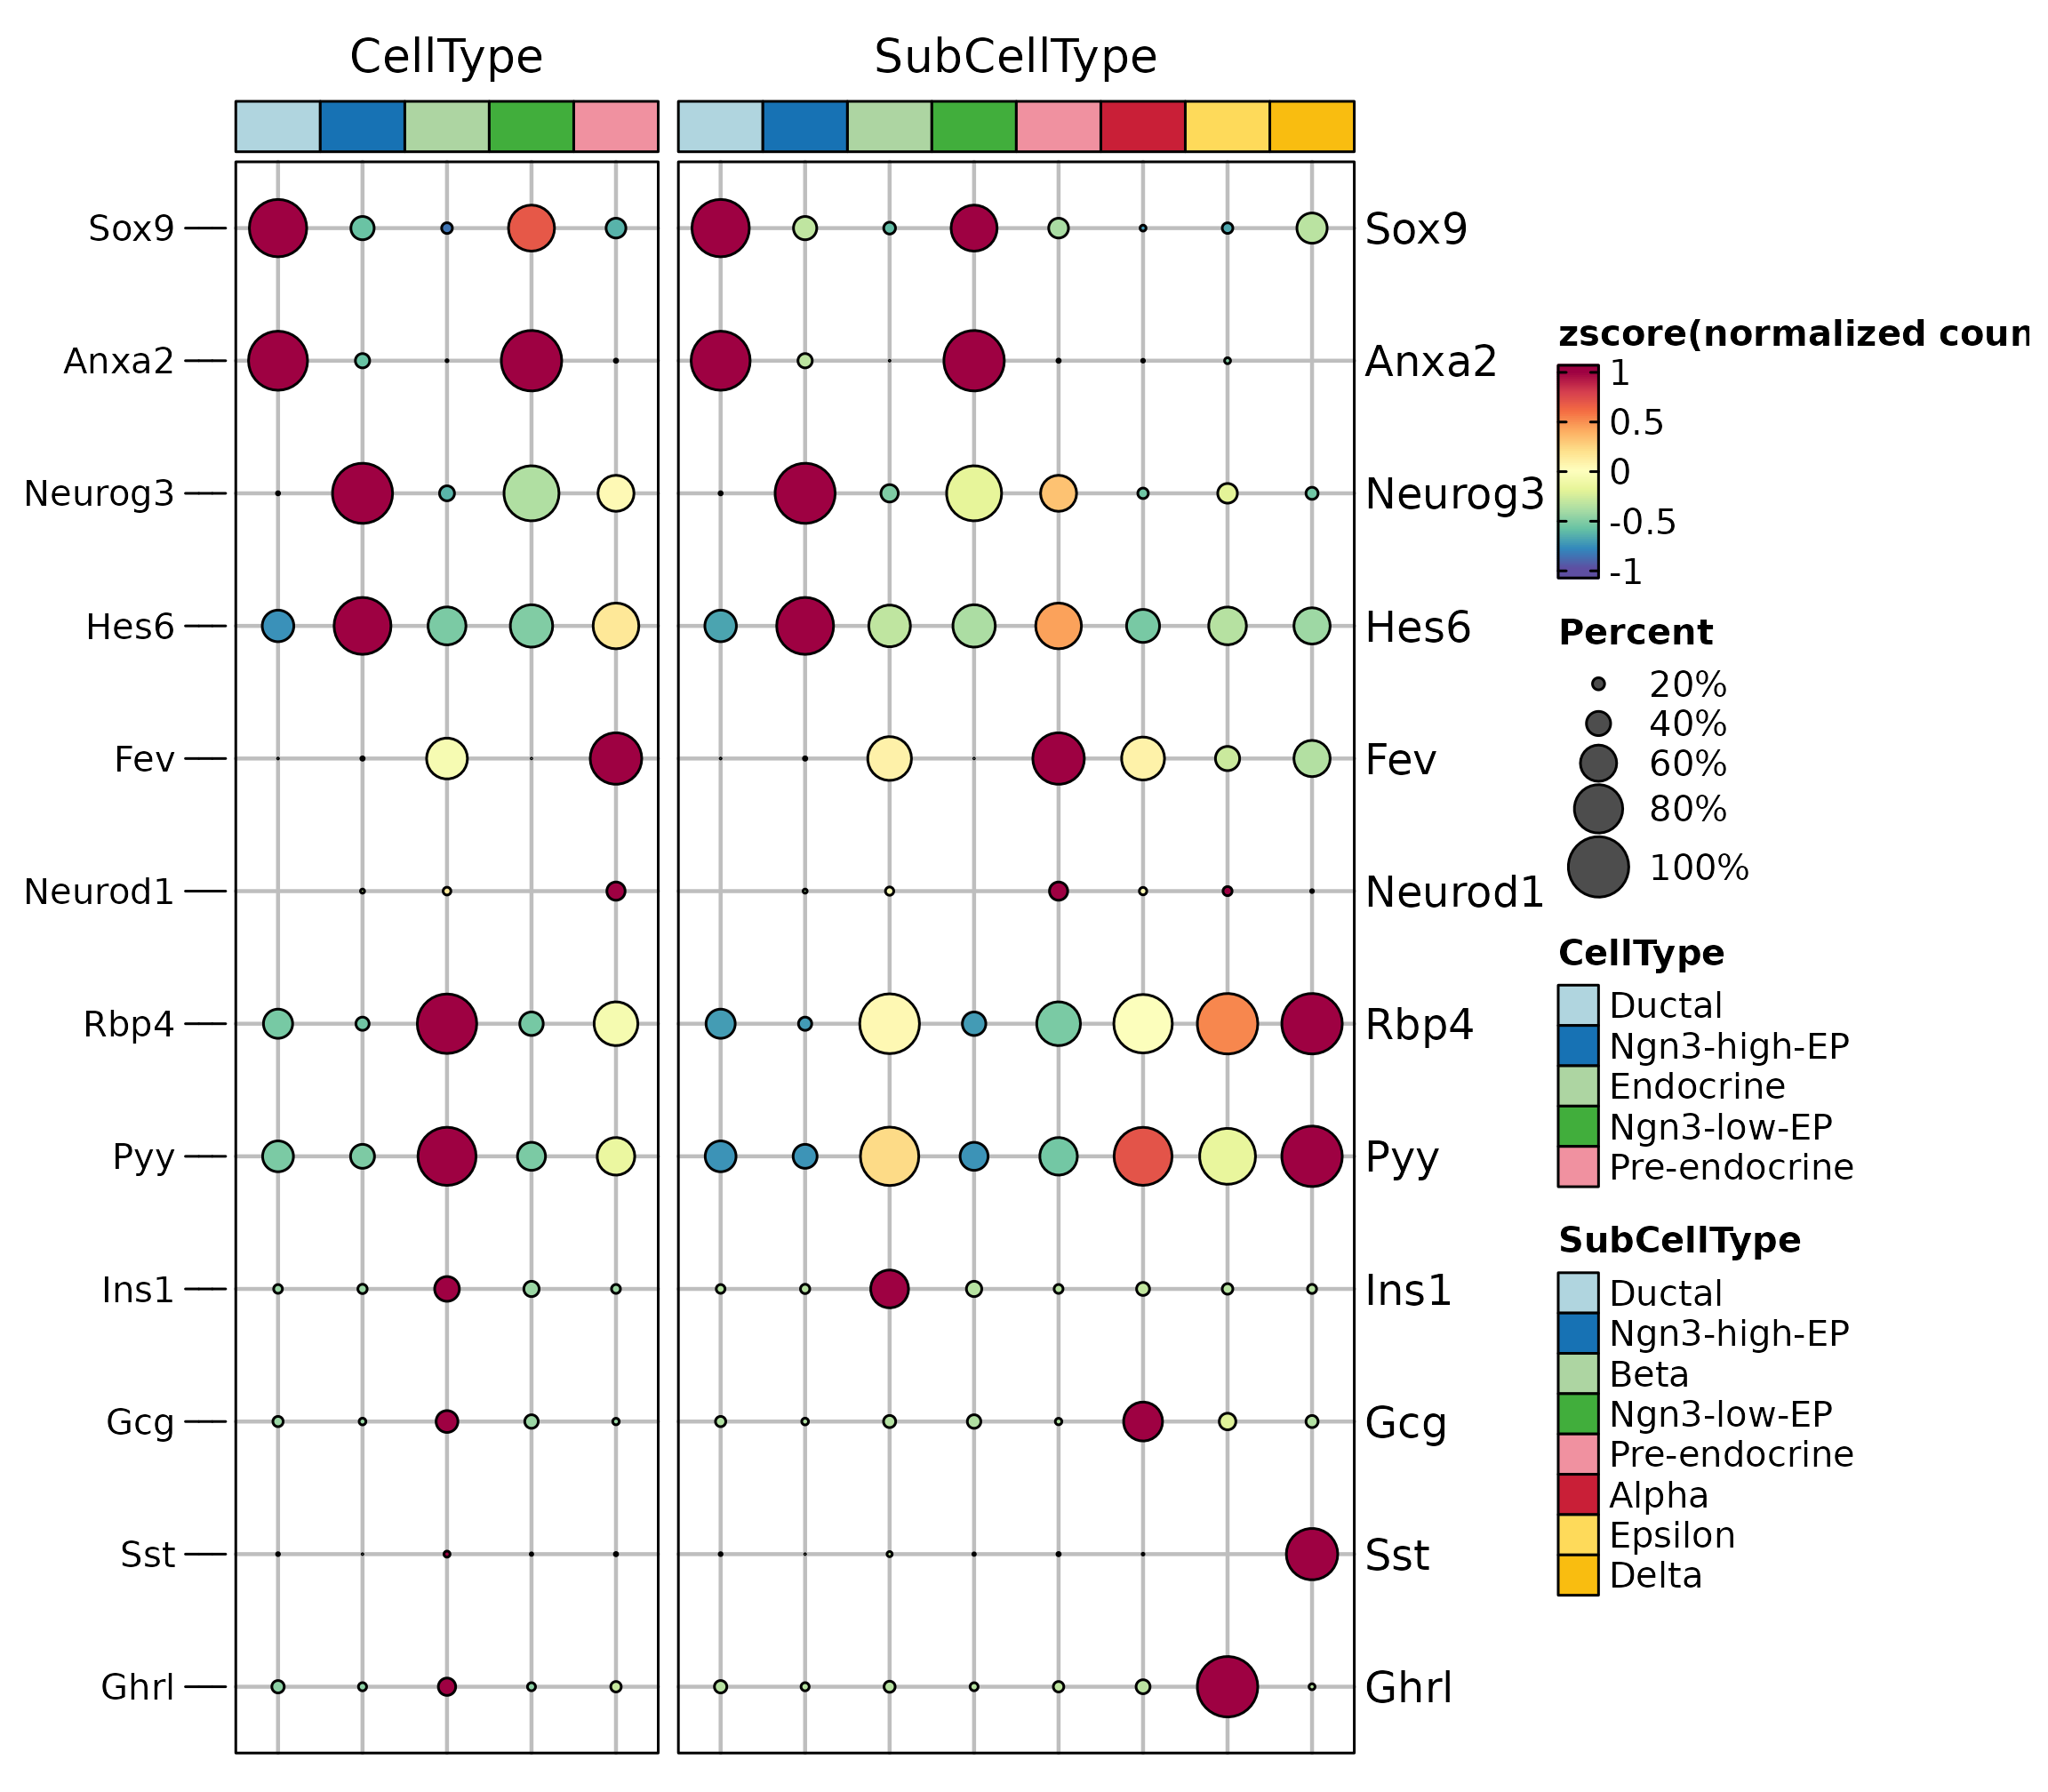
Reconstruct Developmental Trajectories
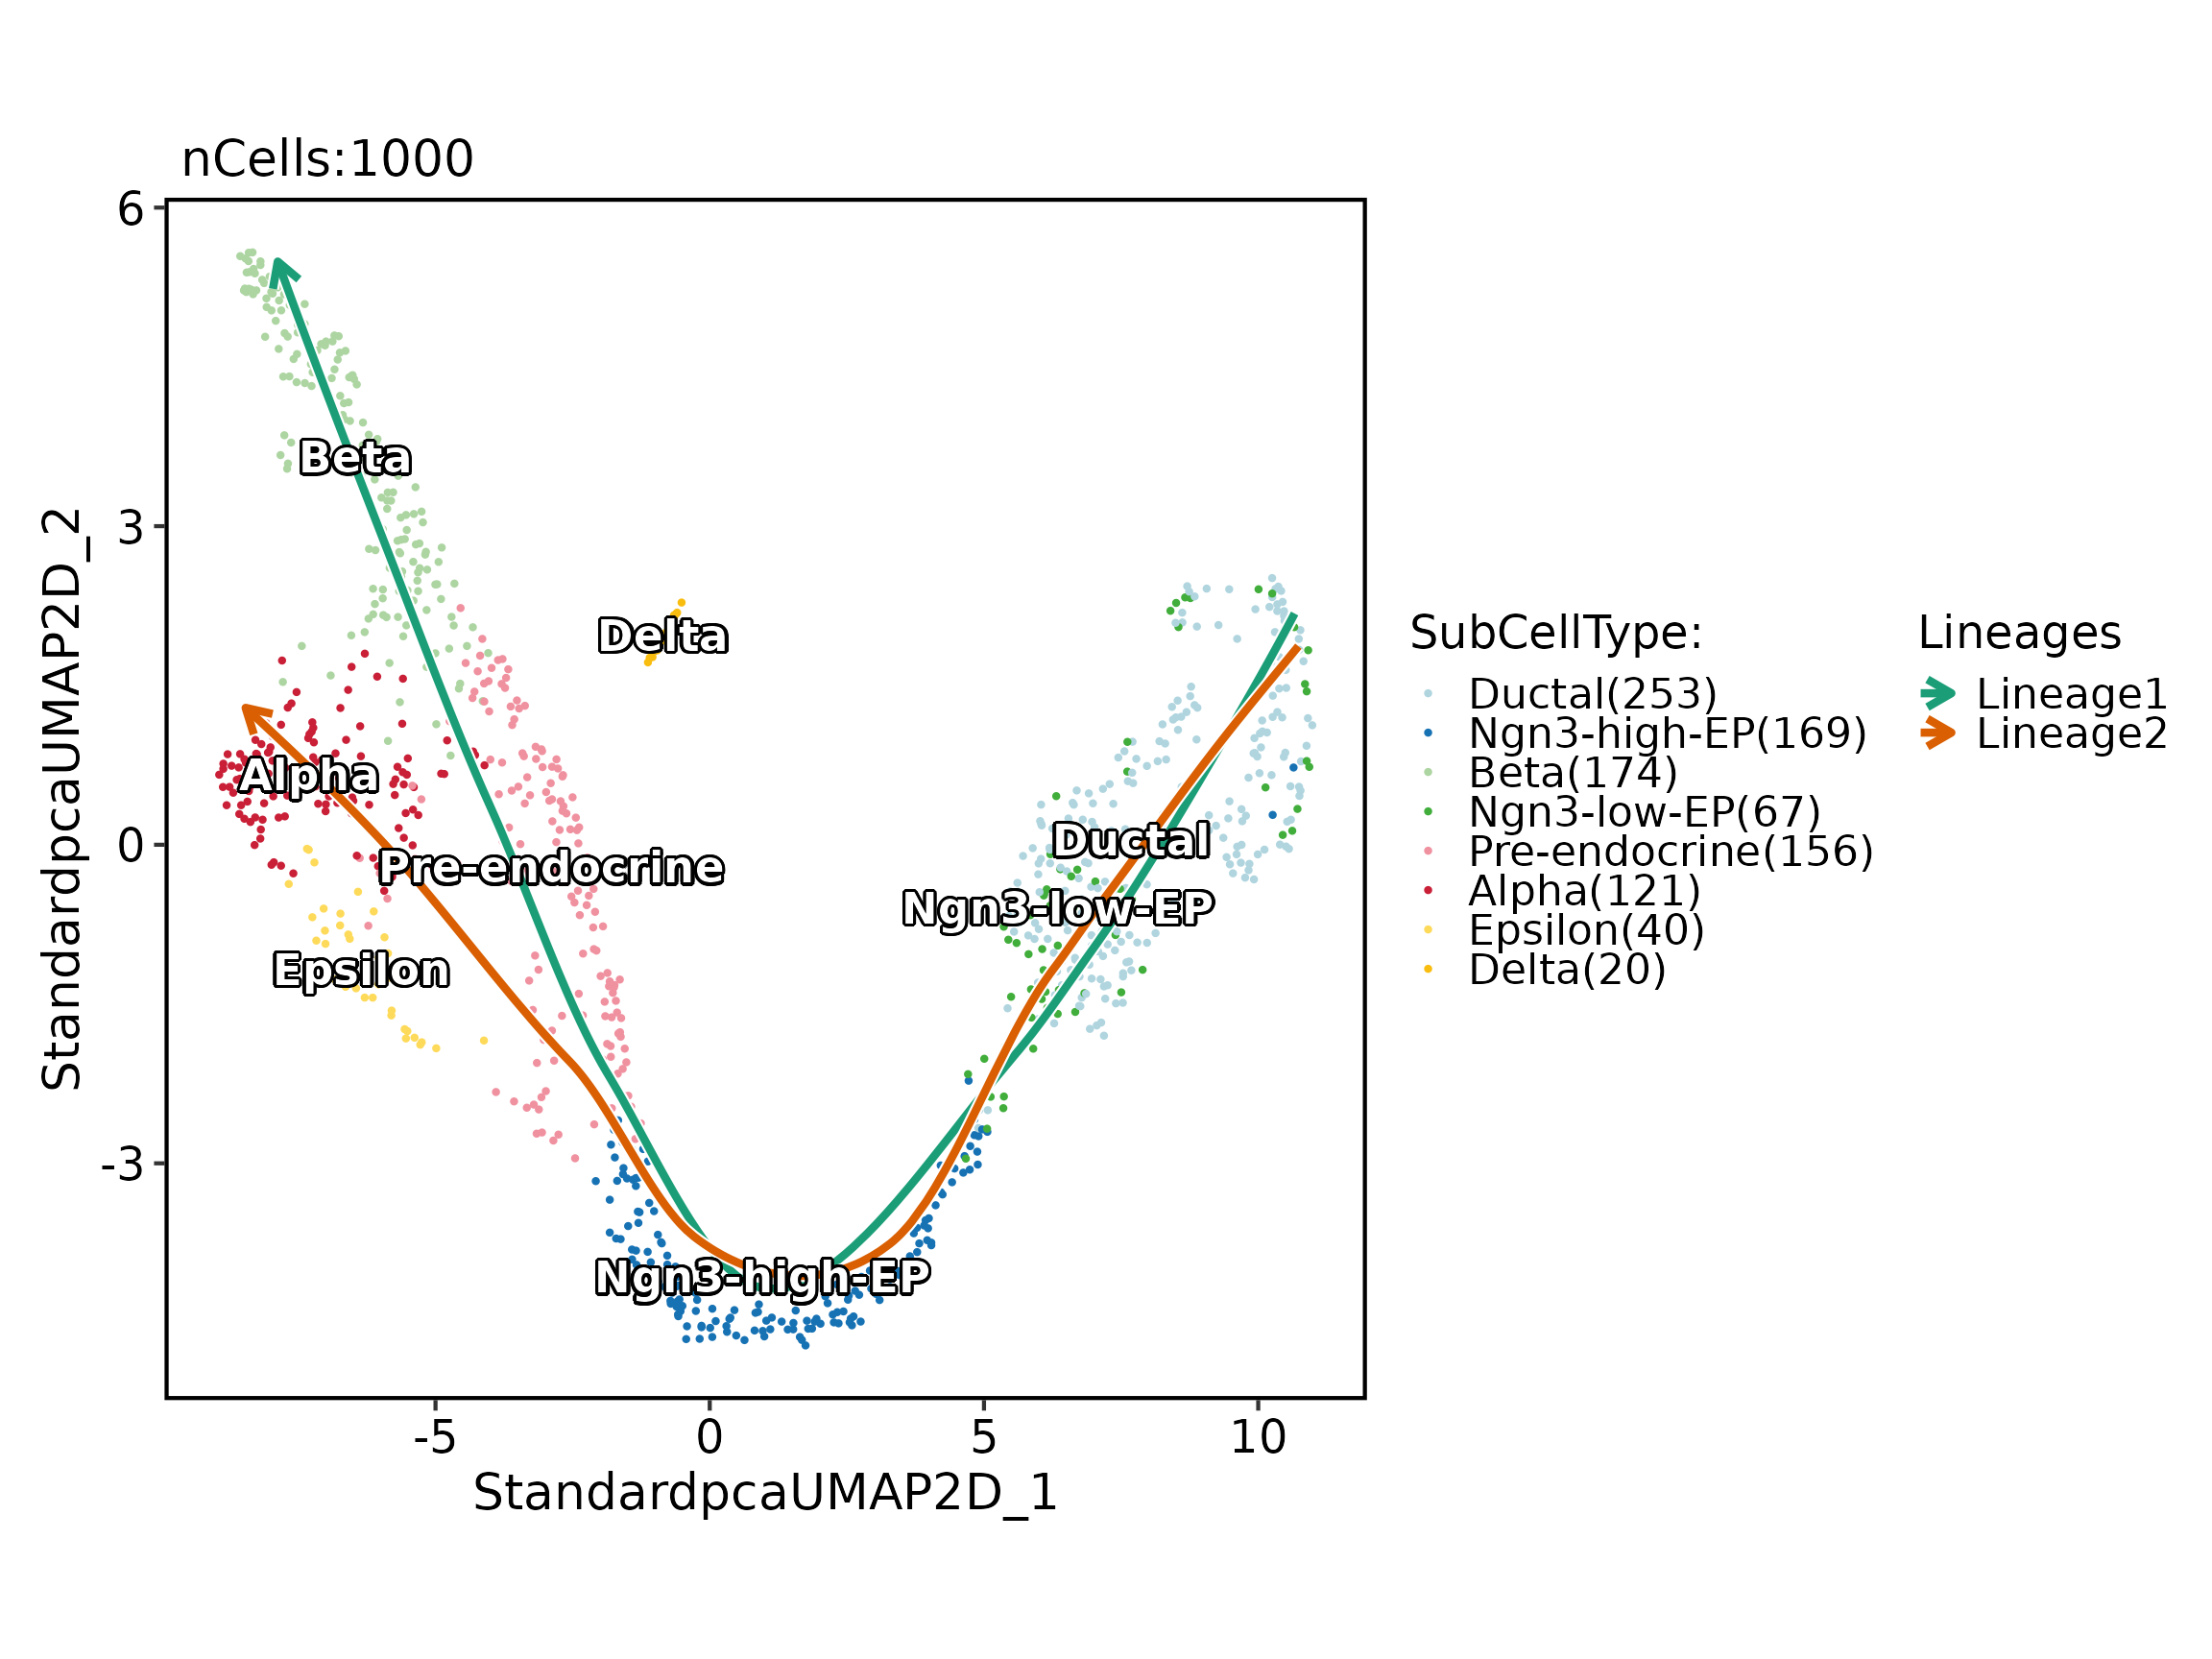
The endocrine differentiation branch is directional, so the trajectory needs an explicit start state. Here the ductal population is used as the root, with alpha and beta states as two terminal endpoints.
pancreas_sub <- RunSlingshot(
  pancreas_sub,
  group.by = "SubCellType",
  reduction = "UMAP",
  start = "Ductal",
  end = c("Alpha", "Beta"),
  show_plot = FALSE, seed = 11
)

CellDimPlot(
  pancreas_sub,
  group.by = "SubCellType",
  lineages = c("Lineage1", "Lineage2"),
  reduction = "UMAP",
  label = TRUE
)
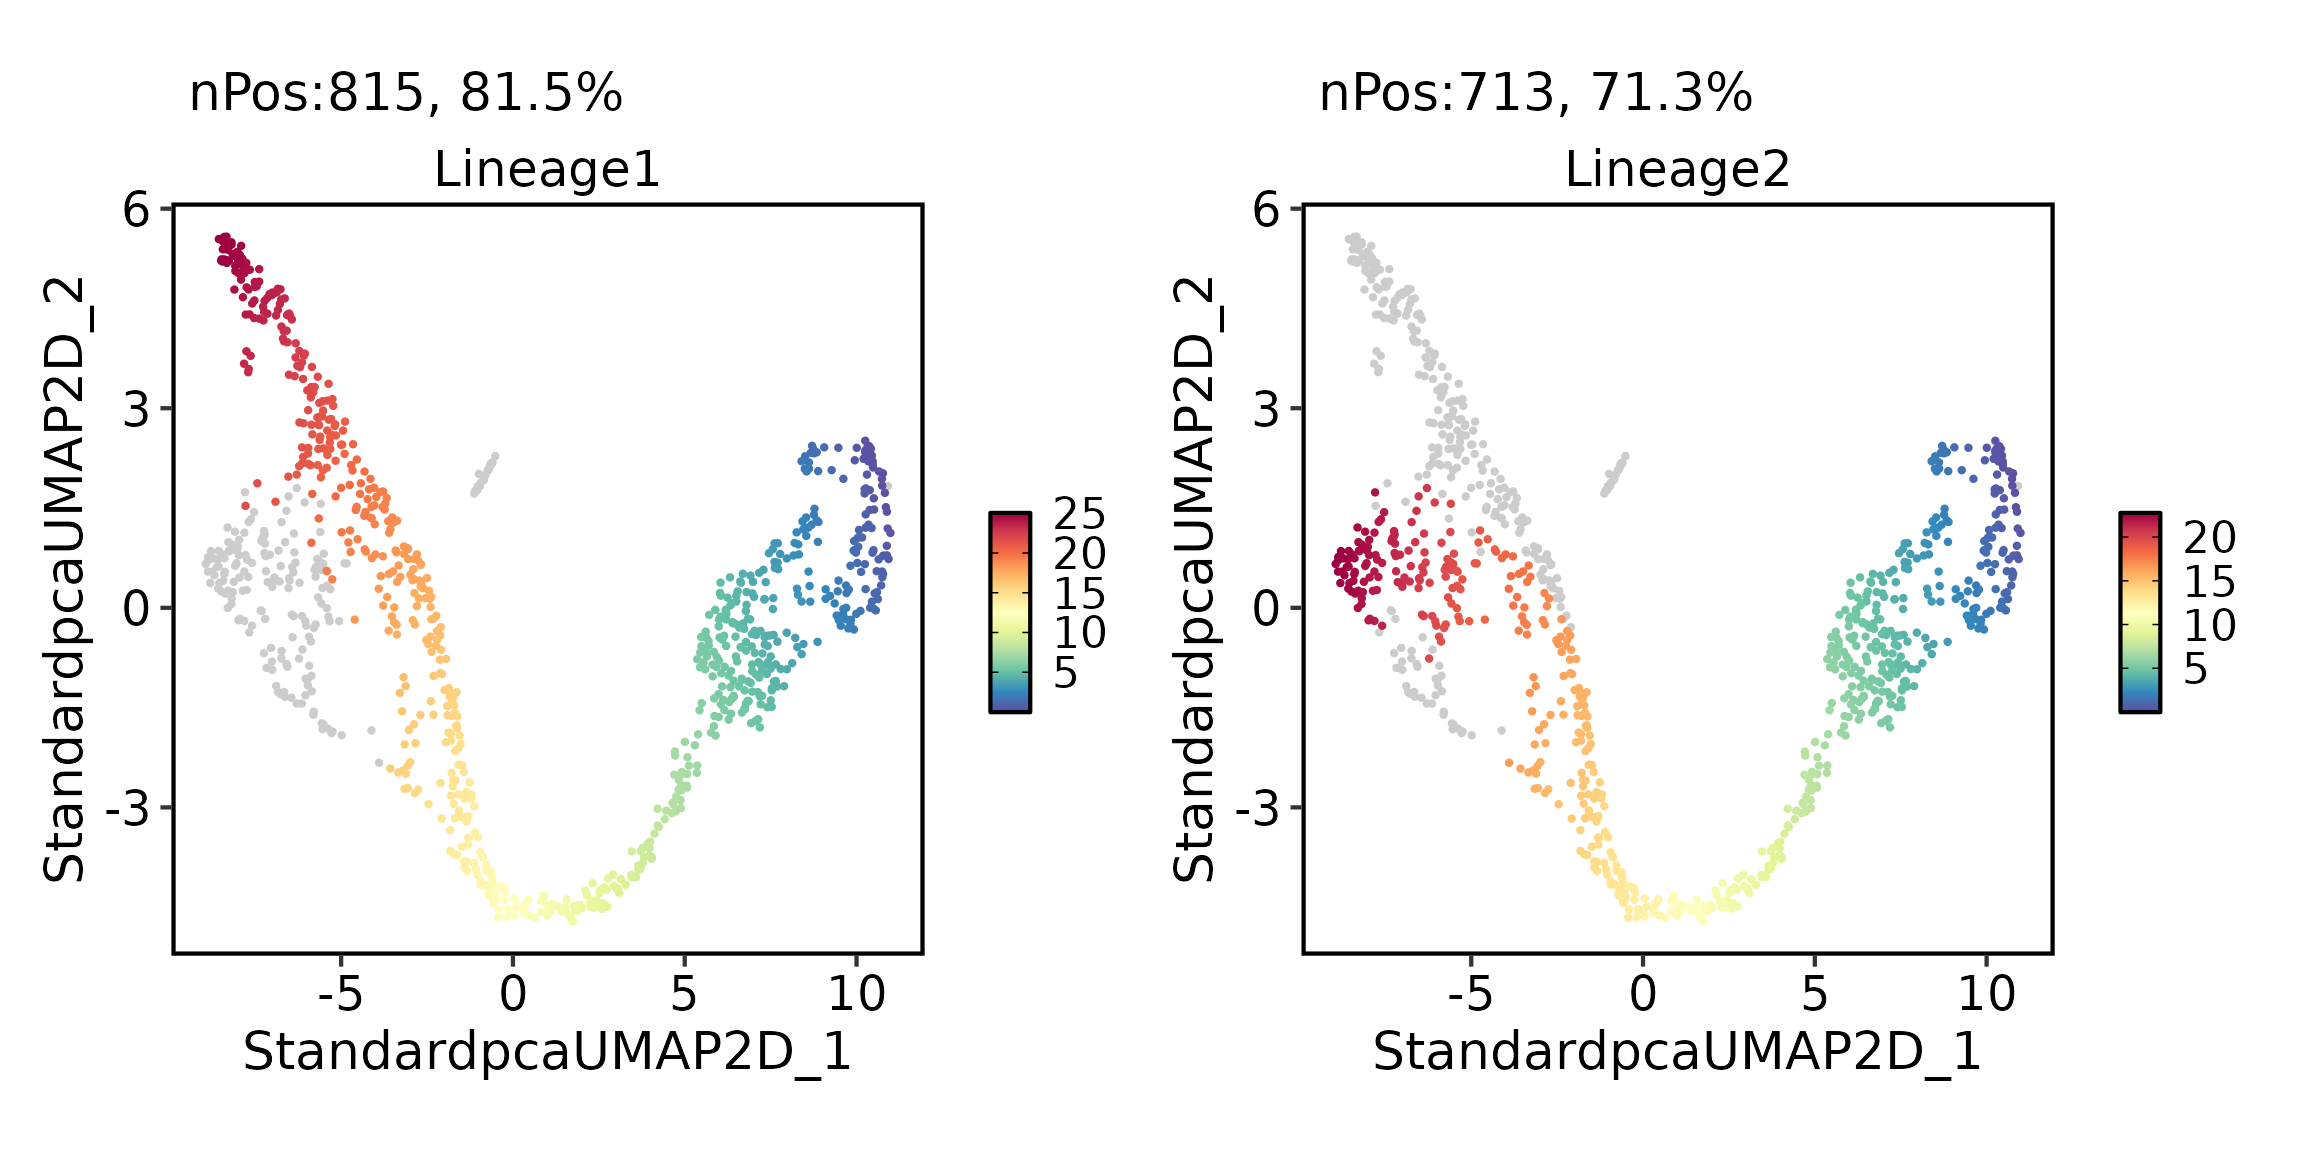
FeatureDimPlot(
  pancreas_sub,
  features = c("Lineage1", "Lineage2"),
  reduction = "UMAP"
)
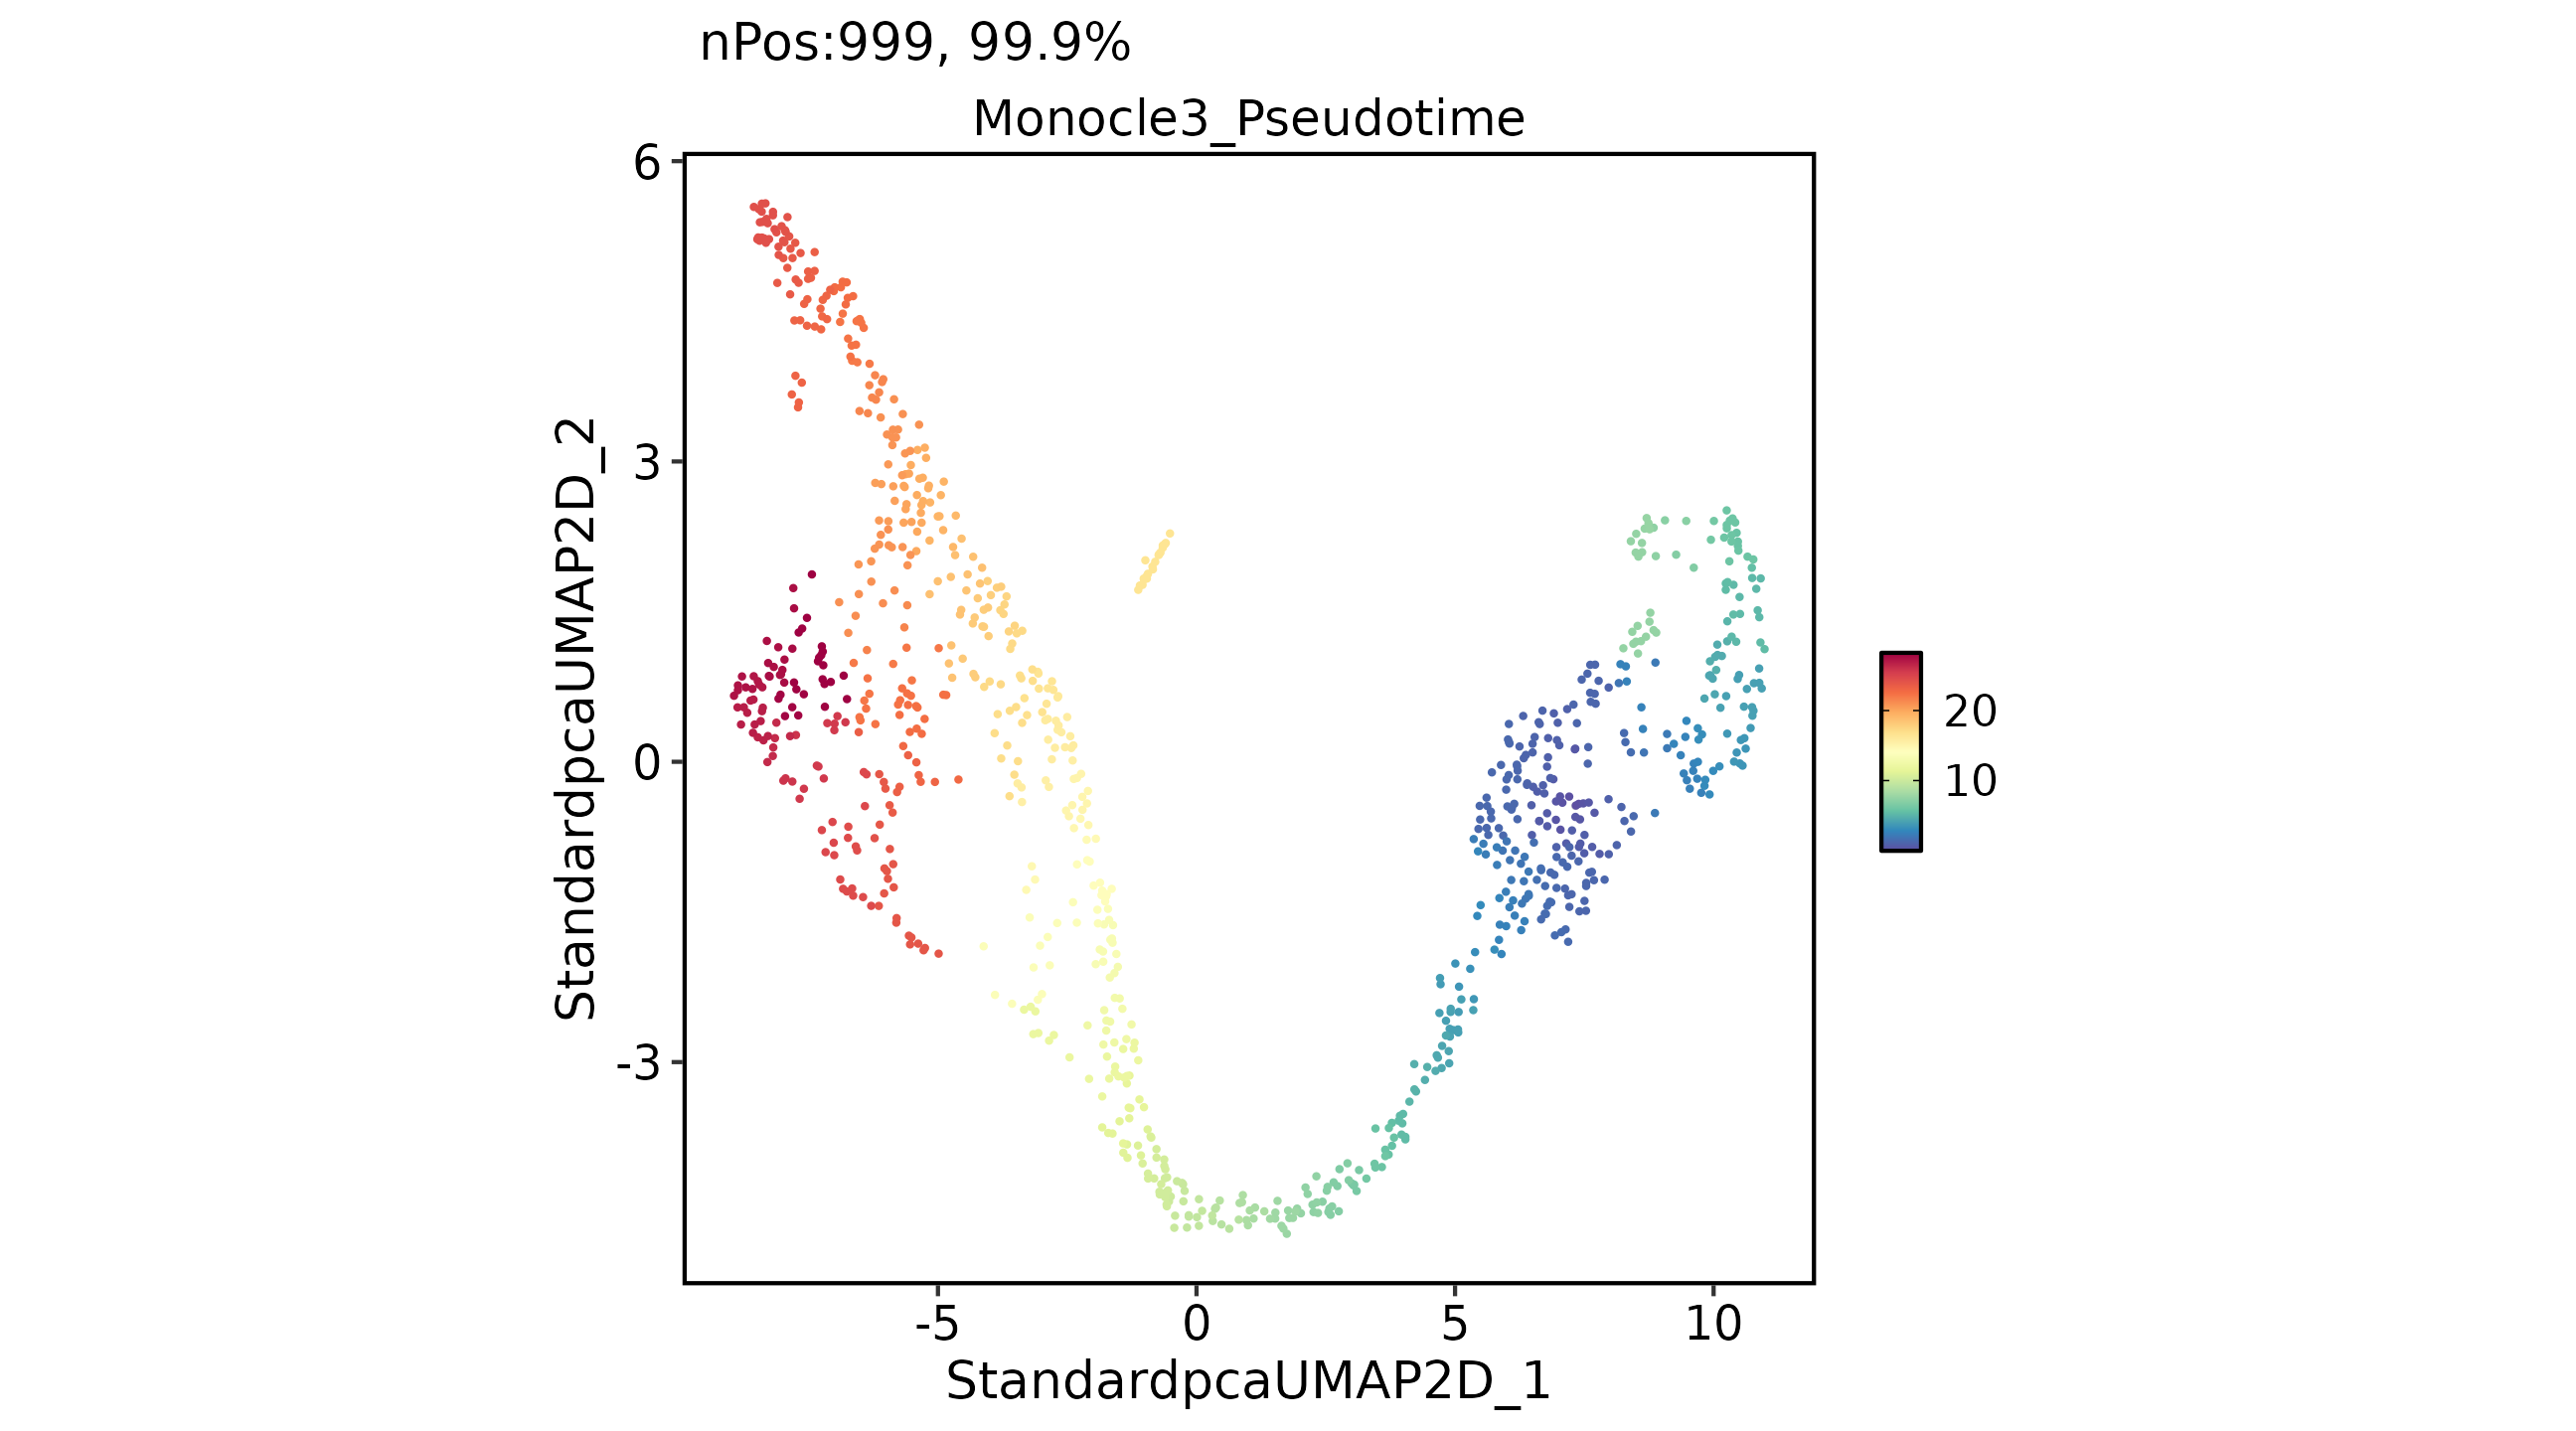
Monocle3 provides an independent graph-based pseudotime layer. The root cell is set to the first ductal cell.
ductal_root <- colnames(pancreas_sub)[pancreas_sub$SubCellType == "Ductal"][1]

pancreas_sub <- RunMonocle3(
  pancreas_sub,
  group.by = "SubCellType",
  use_partition = FALSE,
  root_cells = ductal_root
)
#>   |                                                                              |                                                                      |   0%  |                                                                              |======================================================================| 100%

FeatureDimPlot(
  pancreas_sub,
  features = "Monocle3_Pseudotime",
  reduction = "UMAP"
)
Add RNA Velocity
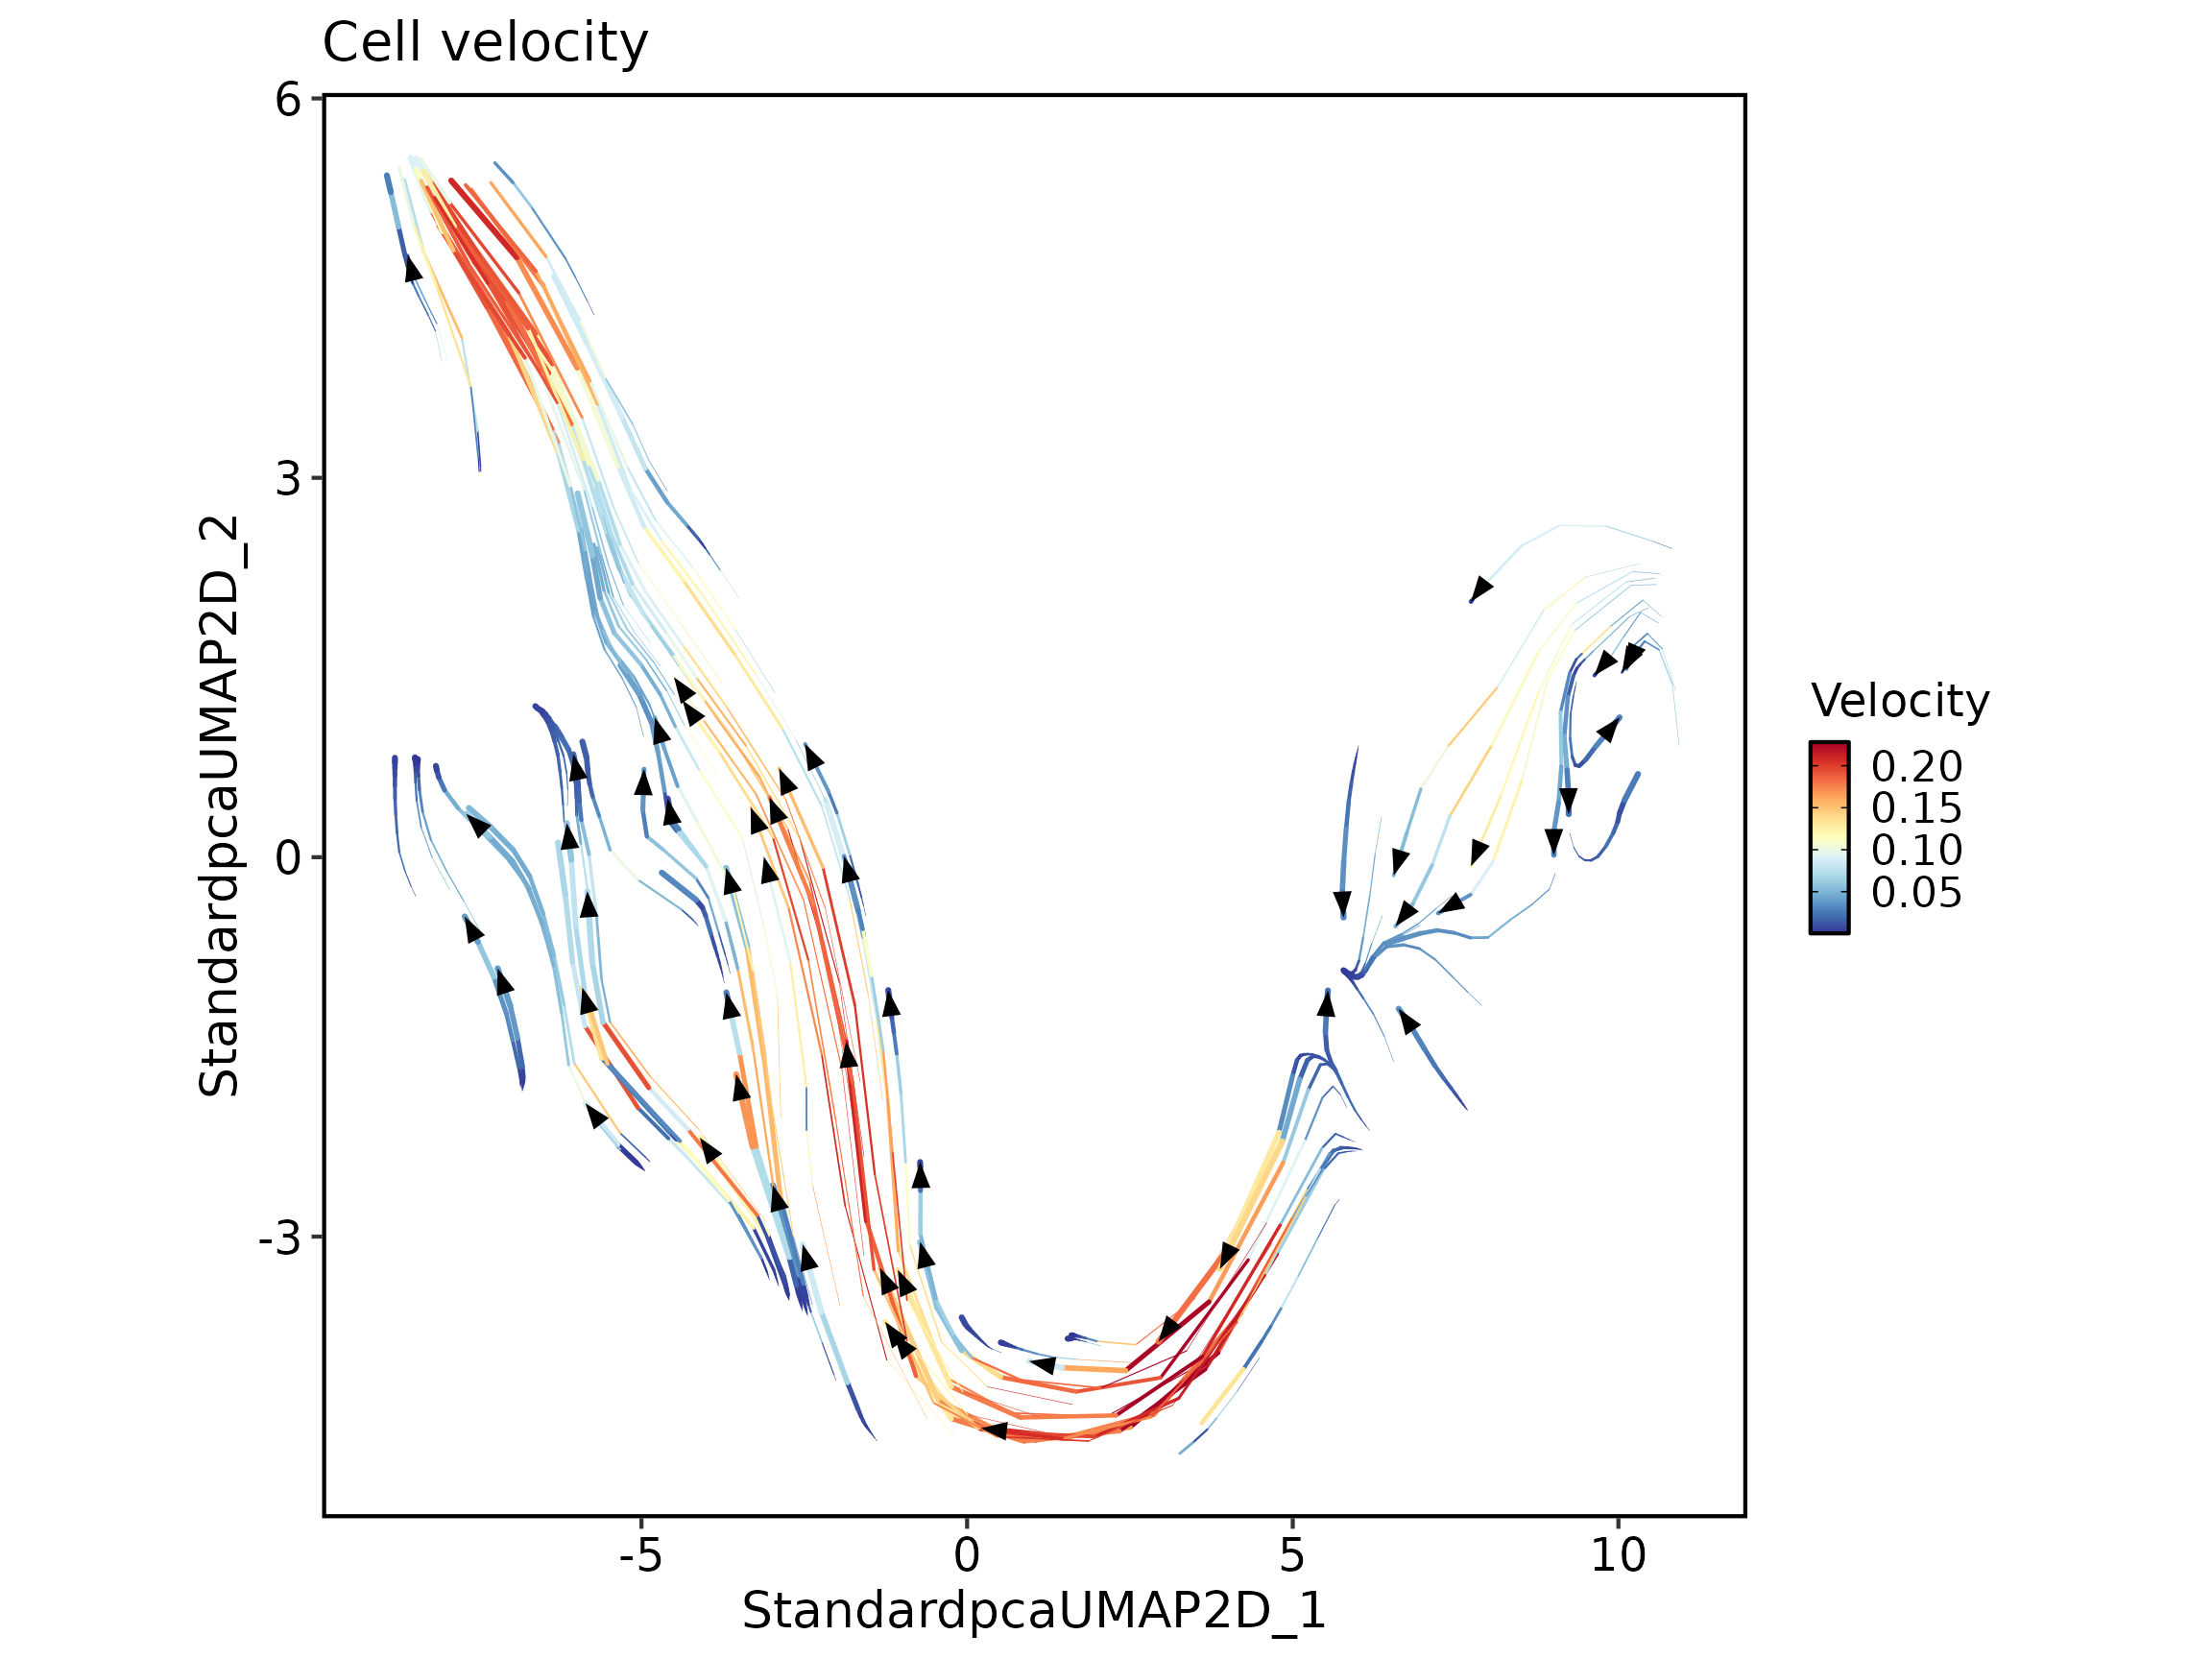
This example explicitly uses SCOP’s native C++ velocity backend, not a Python scVelo run. RNA velocity adds a local direction field on the same embedding. This is useful for checking whether the inferred flow points from ductal and progenitor states toward endocrine states.
pancreas_sub <- RunSCVELO(
  pancreas_sub,
  group.by = "SubCellType",
  linear_reduction = "PCA",
  nonlinear_reduction = "UMAP",
  backend = "cpp", cores = 1, show_plot = FALSE,
  verbose = FALSE
)

VelocityPlot(
  pancreas_sub,
  group.by = "SubCellType",
  reduction = "UMAP",
  plot_type = "stream"
)
Detect Dynamic Genes Along Lineages
Dynamic genes connect the trajectory geometry to interpretable gene programs. The heatmap is split along the two lineages. The 200 candidate genes are a declared feature-selection step; no cells are subsampled. This executed plot shows expression patterns without external pathway or feature-class annotation.
pancreas_sub <- RunDynamicFeatures(
  pancreas_sub,
  lineages = c("Lineage1", "Lineage2"),
  n_candidates = 200
)


ht_dynamic <- DynamicHeatmap(
  pancreas_sub,
  lineages = c("Lineage1", "Lineage2"),
  use_fitted = TRUE,
  n_split = 6,
  reverse_ht = "Lineage1",
  species = "Mus_musculus",
  db = "GO_BP",
  anno_terms = FALSE,
  anno_keys = FALSE,
  anno_features = FALSE,
  heatmap_palette = "viridis",
  cell_annotation = "SubCellType"
)
print(ht_dynamic$plot)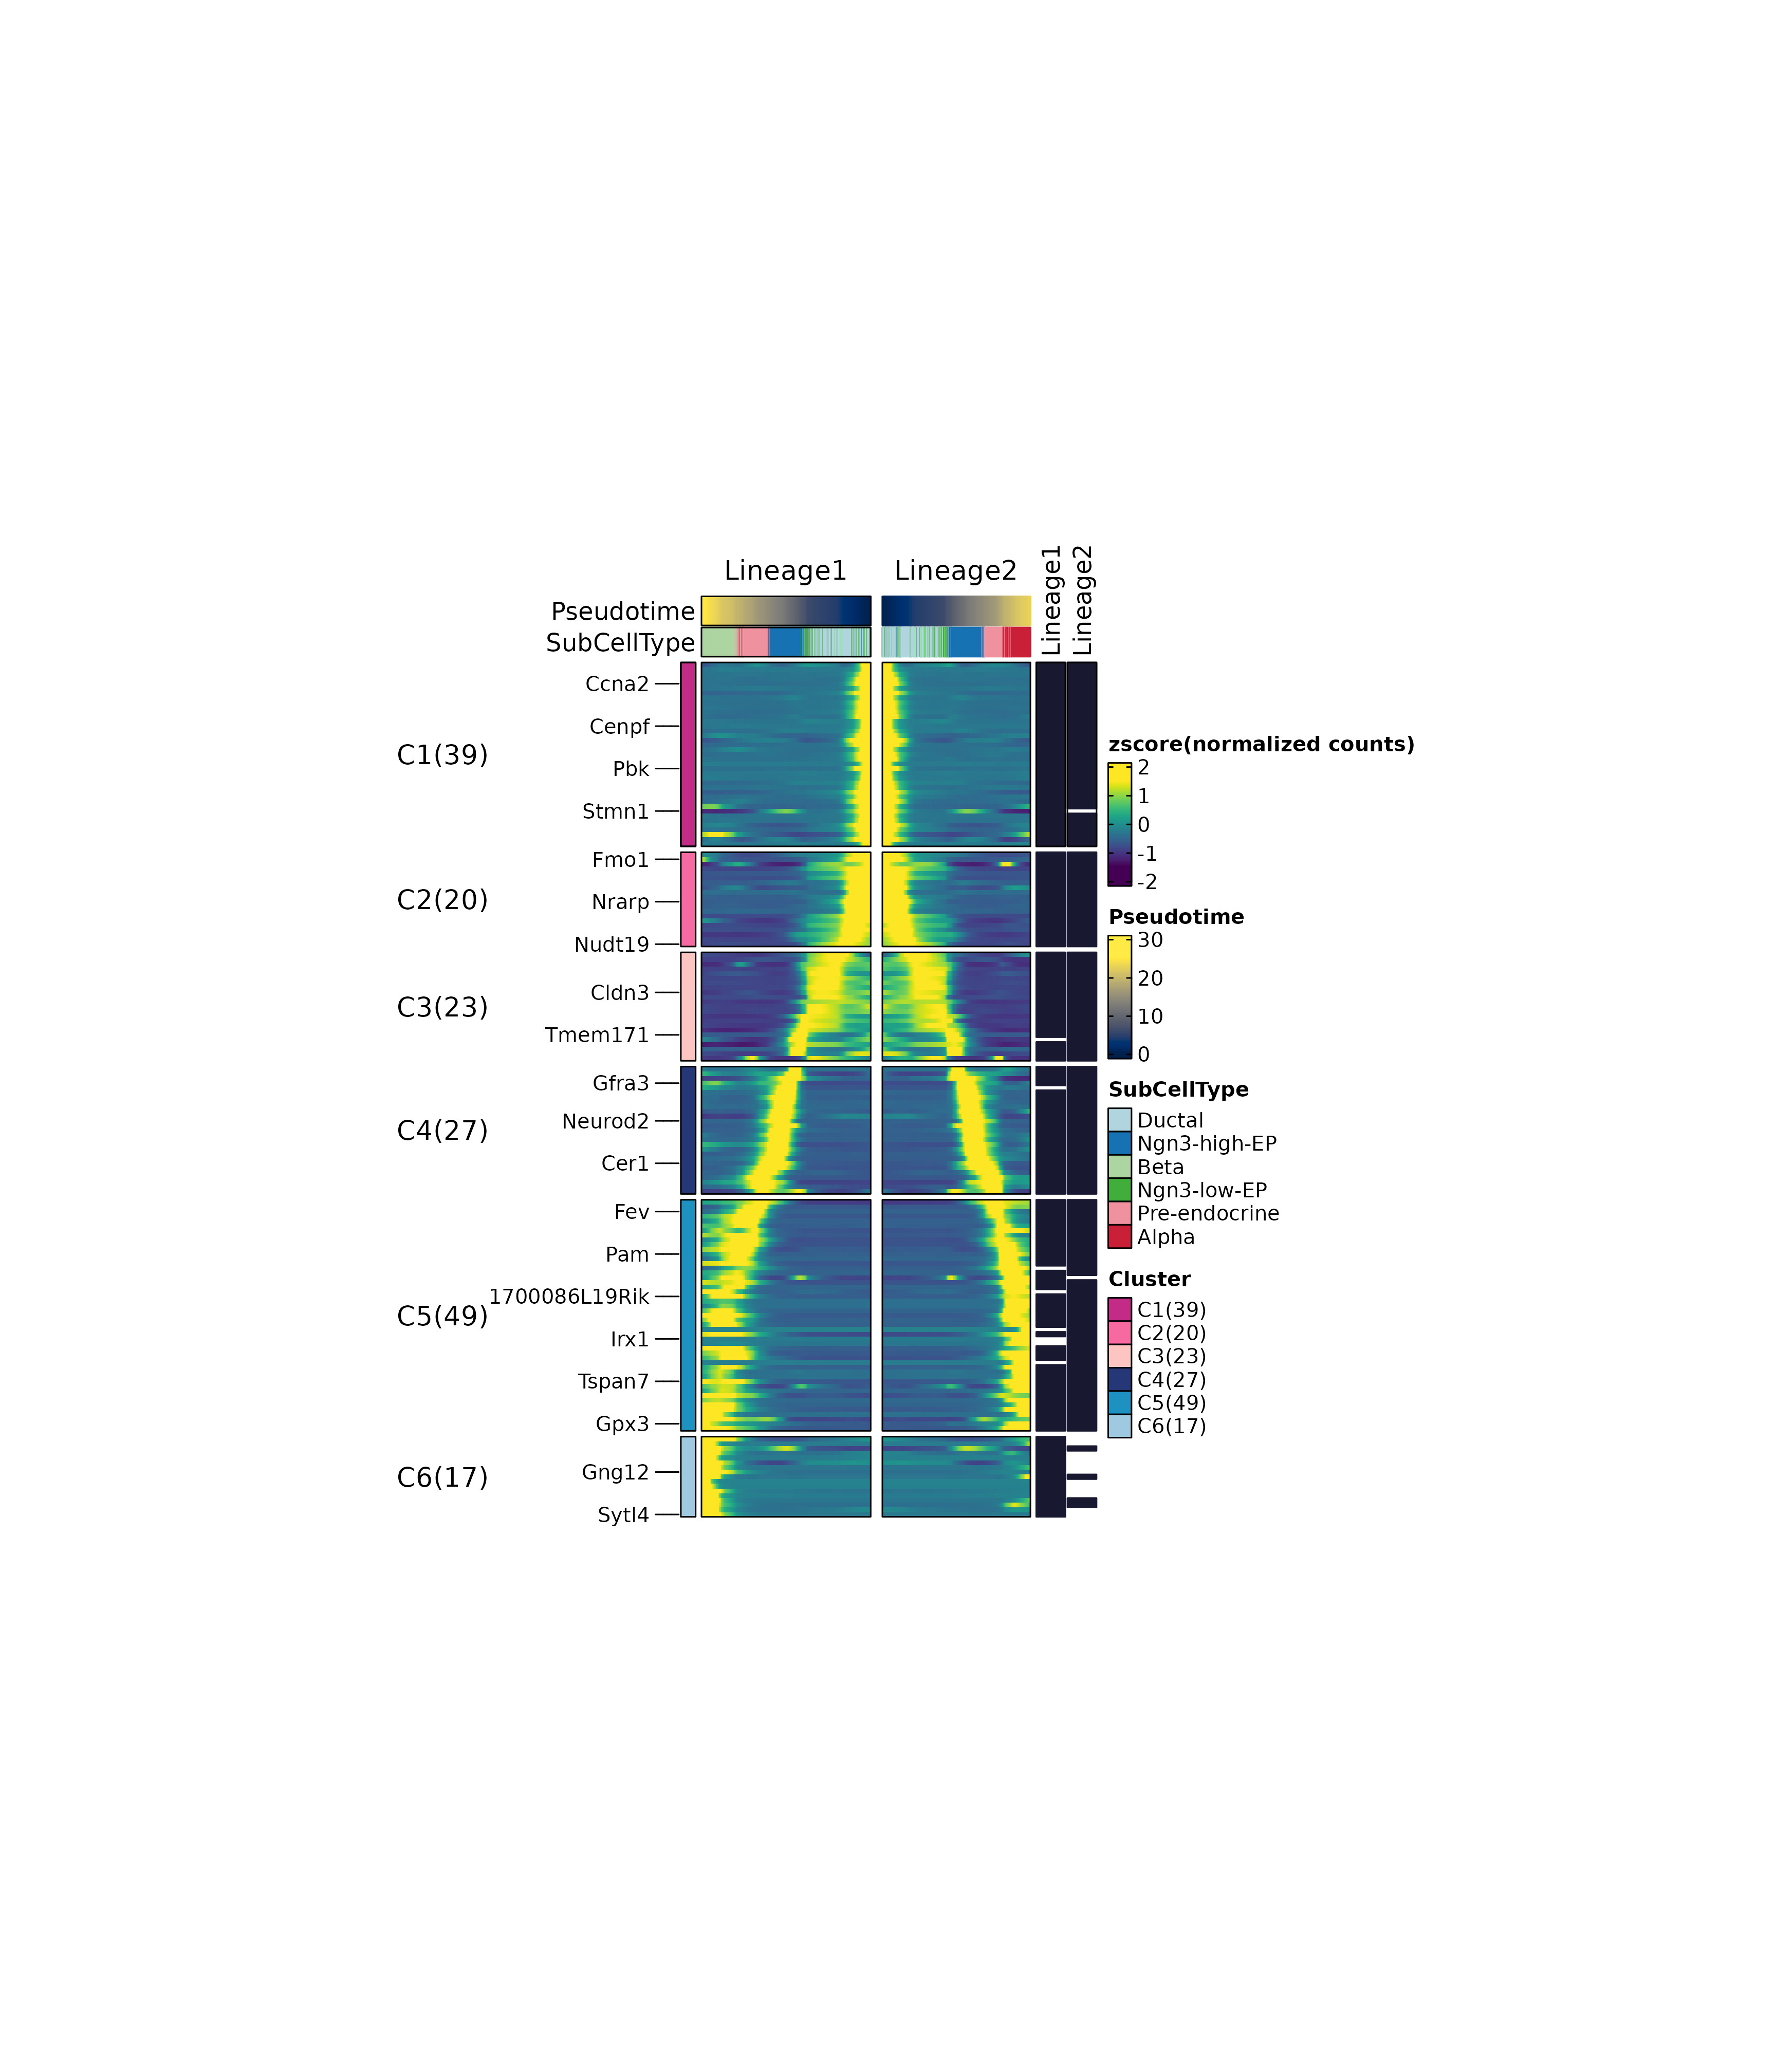
Optional regulatory and enrichment recipes (not executed)
The following code-only sections require additional environments and databases. No SCENIC, GRNBoost2, enrichment or scExplorer results are claimed by this render. For an executed differential-expression example, see the differential and enrichment workflow.
Infer TF Links and Regulatory Activity
The reproduction then moves from dynamic genes to regulatory hypotheses. Use a focused set of pancreatic-development TFs as candidate regulators and combine them with marker genes and highly variable genes as targets.
pancreas_tfs <- c(
  "Sox9", "Neurog3", "Neurod1", "Fev", "Pdx1", "Nkx2-2", "Pax4",
  "Arx", "Mafb", "Mafa", "Rfx6", "Isl1", "Insm1"
)
pancreas_tfs <- intersect(pancreas_tfs, rownames(pancreas_sub))

pancreas_targets <- unique(c(
  pancreas_markers,
  pancreas_tfs,
  head(SeuratObject::VariableFeatures(pancreas_sub), 250)
))
pancreas_targets <- intersect(pancreas_targets, rownames(pancreas_sub))

data.frame(
  candidate_tfs = length(pancreas_tfs),
  candidate_targets = length(pancreas_targets),
  tf_examples = paste(head(pancreas_tfs, 8), collapse = ", ")
)
Run GRNBoost2 first to inspect direct TF-target edges. The table is useful for checking which TFs are connected to hormone genes or progenitor-state markers before regulon scoring.
grn_edges <- RunGRNBoost2(
  pancreas_sub,
  regulators = pancreas_tfs,
  targets = pancreas_targets,
  backend = "cpp",
  max_edges_per_target = 3,
  n_rounds = 500,
  cores = 1,
  seed = 1234,
  verbose = FALSE
)

head(grn_edges[order(grn_edges$importance, decreasing = TRUE), ], 10)
SCENIC prunes regulatory links with cisTarget and scores cellular
regulon activity using AUCell. Each regulon consists of a transcription
factor (TF) and its direct cisTarget-supported target genes. AUCell
computes the enrichment of target genes within each single cell’s
expression ranking, yielding a per-cell Regulon Activity Score (RAS)
matrix stored in the scenic assay. The reference files are
cached by scop; the first run may download the mouse
cisTarget resources.
scenic_dir <- file.path(tempdir(), "scop_pancreas_scenic")

pancreas_sub <- RunSCENIC(
  pancreas_sub,
  species = "Mus_musculus",
  backend = "cpp",
  regulators = pancreas_tfs,
  targets = pancreas_targets,
  work_dir = scenic_dir,
  min_regulon_size = 3,
  max_regulon_targets = 30,
  n_rounds = 500,
  cores = 1,
  seed = 1234,
  force = TRUE,
  verbose = FALSE
)

data.frame(
  scenic_entries = paste(names(pancreas_sub@tools$SCENIC), collapse = ", "),
  regulons = length(pancreas_sub@tools$SCENIC$regulon_list)
)
Rank regulons by cell-state specificity using the Regulon Specificity Score (RSS, calculated from the cell-by-regulon RAS matrix) and keep the top regulons for heatmaps and network plots.
scenic_rss <- SCENICPlot(
  pancreas_sub,
  group.by = "SubCellType",
  plot_type = "rss_rank",
  top_n = 6,
  highlight_tf = pancreas_tfs,
  label_size = 2.5
)
print_scop_plot(scenic_rss)
top_regulons <- unique(scenic_rss$top_table$regulon)
top_tfs <- unique(scenic_rss$top_table$TF)

top_regulons <- head(top_regulons, 10)
top_tfs <- head(top_tfs, 4)

data.frame(
  top_regulons = paste(top_regulons, collapse = ", "),
  top_tfs = paste(top_tfs, collapse = ", ")
)
scenic_rss_heatmap <- SCENICPlot(
  pancreas_sub,
  group.by = "SubCellType",
  plot_type = "rss_heatmap",
  features = top_regulons,
  rss_scale = TRUE,
  heatmap_order = "group",
  heatmap_show_row_names = TRUE,
  heatmap_cluster_columns = FALSE
)
print_scop_plot(scenic_rss_heatmap)
The rss_heatmap above illustrates cluster-level
specificity (RSS). Use GroupHeatmap() to compare Regulon
Activity Scores (RAS) across cell types from the stored
scenic assay.
activity_features <- rownames(pancreas_sub[["scenic"]])[
  match(top_regulons, pancreas_sub[["scenic"]][[]]$termnames)
]
scenic_activity_heatmap <- GroupHeatmap(
  pancreas_sub,
  group.by = "SubCellType",
  assay = "scenic",
  layer = "data",
  features = activity_features,
  exp_method = "zscore",
  show_row_names = TRUE,
  cluster_columns = FALSE
)
print_scop_plot(scenic_activity_heatmap)
scenic_network <- SCENICPlot(
  pancreas_sub,
  group.by = "SubCellType",
  plot_type = "network",
  network_tf = top_tfs,
  max_targets = 12,
  label_nodes = "tfs"
)
print_scop_plot(scenic_network)
scenic_targets <- SCENICPlot(
  pancreas_sub,
  group.by = "SubCellType",
  plot_type = "target_bar",
  features = head(top_regulons, 4),
  max_targets = 12
)
print_scop_plot(scenic_targets)
Differential Genes and Pathway Terms
Marker and enrichment analysis provide a second downstream layer. These results should be interpreted together with the trajectory and TF analyses: dynamic genes show when programs change, while DE and enrichment show which programs separate annotated states.
pancreas_sub <- RunDEtest(
  pancreas_sub,
  group.by = "CellType",
  fc.threshold = 1,
  only.pos = FALSE
)

pancreas_sub <- RunEnrichment(
  pancreas_sub,
  group.by = "CellType",
  db = "GO_BP",
  species = "Mus_musculus",
  DE_threshold = "avg_log2FC > log2(1.5) & p_val_adj < 0.05"
)

go_bp_overlay_values <- setNames(
  rep("#CFE8CC", 2),
  c(paste("Enrichment", "GO_BP", sep = " | "), "GO_BP")
)

de_volcano_plots <- DEtestPlot(
  pancreas_sub,
  group.by = "CellType",
  plot_type = "volcano",
  threshold_method = "hyperbolic",
  hyperbola_c = 6,
  annotate_enrichment = TRUE,
  enrich_from = "Enrichment",
  enrich_db = "GO_BP",
  enrich_top_terms = 2,
  enrich_nlabel = 10,
  label.size = 2,
  combine = FALSE
)

de_volcano_plots <- lapply(
  de_volcano_plots,
  function(p) {
    p +
      ggplot2::scale_fill_manual(
        name = "Enrichment",
        values = go_bp_overlay_values,
        labels = function(x) sub("^.* \\|\\s*", "", x)
      ) +
      ggplot2::guides(
        fill = ggplot2::guide_legend(override.aes = list(size = 2))
      ) +
      ggplot2::theme(legend.box = "vertical")
  }
)

patchwork::wrap_plots(de_volcano_plots, ncol = 2, guides = "collect") &
  ggplot2::theme(legend.position = "right")
Here GO_BP denotes the Gene Ontology Biological Process
database used for the enrichment overlay. The circled genes are genes
from the top enriched GO-BP terms selected for each cell-state
comparison; GO_BP is the database label, not one specific
pathway term. The specific enriched terms are summarized in the bar plot
below.
EnrichmentPlot(
  pancreas_sub,
  group.by = "CellType",
  group_use = c("Ductal", "Endocrine"),
  plot_type = "bar"
)
Export the Reproduction Object
The final object contains the upstream preprocessing state, trajectory metadata, velocity output, dynamic genes, SCENIC regulon activity (RAS), differential genes, and enrichment results. Export it for interactive review in SCExplorer.
scexplorer_dir <- file.path(tempdir(), "SCExplorer_pancreas_reproduction")

PrepareSCExplorer(
  list(pancreas_reproduction = pancreas_sub),
  base_dir = scexplorer_dir
)

head(list.files(scexplorer_dir), 10)
Reproduction Summary
This compact reproduction should be read as a linked evidence trail:
- marker genes validate the major developmental states;
- Slingshot, Monocle3, and velocity provide directional support for the endocrine differentiation path;
- dynamic genes recover stage-specific programs along the pseudotime axis;
- GRNBoost2 and SCENIC prioritize TF-target links and regulon activity (RAS);
- DE and GO enrichment summarize the state-level transcriptional programs;
- SCExplorer keeps the full object available for interactive inspection.