Normalize, find variable features, scale, reduce dimensions, and cluster a
Seurat object. workflow = "spatial" adds spot QC, spatial variable
features, optional spatial clustering, and optional deconvolution. It is
not a multi-slice integration orchestrator.
Objects that also contain a ChromatinAssay are preprocessed sequentially
(default assay, then chromatin).
Usage
RunStandardWorkflow(
  object,
  prefix = "Standard",
  workflow = c("single_cell", "spatial"),
  assay = NULL,
  image = NULL,
  coord.cols = c("x", "y"),
  do_spot_qc = TRUE,
  spot_qc_params = list(),
  do_spatial_variable_features = TRUE,
  spatial_variable_features_params = list(),
  do_spatial_cluster = FALSE,
  spatial_cluster_method = "BayesSpace",
  spatial_q = NULL,
  bayesspace_params = list(),
  reference = NULL,
  reference_label = NULL,
  reference_assay = NULL,
  do_deconvolution = !is.null(reference),
  deconvolution_method = "RCTD",
  deconvolution_params = list(),
  do_normalization = NULL,
  normalization_method = "LogNormalize",
  do_HVF_finding = TRUE,
  HVF_method = "vst",
  nHVF = 2000,
  HVF = NULL,
  do_scaling = TRUE,
  vars_to_regress = NULL,
  regression_model = "linear",
  linear_reduction = "pca",
  linear_reduction_dims = 50,
  linear_reduction_dims_use = NULL,
  linear_reduction_params = list(),
  force_linear_reduction = FALSE,
  nonlinear_reduction = "umap",
  nonlinear_reduction_dims = 2,
  nonlinear_reduction_params = list(),
  force_nonlinear_reduction = TRUE,
  neighbor_metric = "euclidean",
  neighbor_k = 20L,
  cluster_algorithm = "louvain",
  cluster_resolution = 0.6,
  cores = 1L,
  verbose = TRUE,
  seed = 11,
  spatial_cluster_params = list(),
  do_spatial_qc = FALSE,
  spatial_qc_params = list(),
  spanorm_params = list(),
  spatial_data_type = "auto",
  srt = NULL,
  ...
)
Arguments
- object
A
Seuratobject.- prefix
Prefix for intermediate object names.
- workflow
"single_cell"or"spatial"(one explicitly selected spatial context).- assay
Assay to use.
NULLuses the default assay.- image
Spatial image name. Required when multiple images are present; a single image is selected automatically when
NULL.- coord.cols
Metadata coordinate columns used when no image is available.
- do_spot_qc, spot_qc_params
Run
RunSpotQC()and extra arguments.- do_spatial_variable_features, spatial_variable_features_params
Run
RunSpatialVariableFeatures(). The workflow defaultsset_variable_features = FALSEso expression HVFs are kept.- do_spatial_cluster, spatial_cluster_method, spatial_q, bayesspace_params
Spatial clustering with
"BayesSpace","BANKSY", or"SmoothClust".spatial_q = NULLuses ordinary clusters for BayesSpace/SmoothClust. BANKSY uses its resolution parameter and rejects a suppliedspatial_q.- reference, reference_label, reference_assay
Optional single-cell reference for deconvolution.
- do_deconvolution, deconvolution_method, deconvolution_params
Deconvolution (
"RCTD","SPOTlight", or"Cell2location").NULLruns whenreferenceor cell2location signatures are provided.- do_normalization, normalization_method
Normalize if the assay has no scaled data (
NULL). One of"LogNormalize","SCT","TFIDF","scran"."SCT"switches downstream steps to the"SCT"assay.- do_HVF_finding, HVF_method, nHVF, HVF
Highly variable features.
HVF_methodis"vst","mvp","disp", or"scran".- do_scaling
Force scaling via ScaleData.
- vars_to_regress
Regressors used in scaling.
NULLuses none.- regression_model
"linear","poisson", or"negativebinomial".- linear_reduction, linear_reduction_dims, linear_reduction_dims_use, linear_reduction_params, force_linear_reduction
Linear reduction (
"pca","svd","ica","nmf","mds","glmpca").linear_reduction_dims_use = NULLuses estimated dimensions unless the method specifies a different default; explicit values select computed components.- nonlinear_reduction, nonlinear_reduction_dims, nonlinear_reduction_params, force_nonlinear_reduction
Nonlinear reduction (
"umap","umap-naive","tsne","dm","phate","pacmap","trimap","largevis","fr").- neighbor_metric, neighbor_k
Neighbor graph (
"euclidean","cosine","manhattan","hamming").- cluster_algorithm, cluster_resolution
Clustering (
"louvain","slm","leiden"). Largercluster_resolutionyields fewer clusters.- cores
Number of CPU cores.
NULLlets each method pick its own default: the process OpenMP team (OMP_NUM_THREADS) for C++ kernels and one worker for R/Python parallel execution.- verbose
Whether to print the message. Default is
TRUE.- seed
Random seed.
- spatial_cluster_params
Named method-specific arguments. For BayesSpace, use either this list or the retained
bayesspace_params, not both.- do_spatial_qc, spatial_qc_params
Run spatially aware
RunSpotSweeper()before preprocessing. Filtering is disabled; inspect its QC labels first.- spanorm_params
Arguments for
RunSpaNorm()whennormalization_method = "SpaNorm". Creates a separate normalized assay; count-based methods continue to use the original assay.- spatial_data_type
Observation type:
"auto","spot","bin", or"cell". Auto uses import provenance or image evidence, otherwise unknown. Cell observations cannot use BayesSpace or spot deconvolution in this workflow.- srt
Deprecated alias for
object; supply exactly one of the two. It will be removed in scop 1.0.0.- ...
Arguments passed to other functions.
Value
A Seurat object. Spatial workflows store per-stage execution and
result-storage state in srt@tools[["run_standard_spatial_workflow"]],
including the effective set_variable_features value, result_stored, and
result_location. A failed stage signals an error with the same table in
attribute standard_spatial_stages.
Details
ATAC defaults select the available dimensions from 2:30. Explicit ATAC
dimensions must exist in the computed reduction.
ATAC workflows record selected dimensions, cells, features and Pearson
correlations with raw library depth in
Misc(reduction, "scop_atac_representation"). Undefined correlations remain
NA. A requested ATAC graph, clustering or nonlinear-reduction failure stops
the workflow; a partially processed object is not returned as successful.
Examples
data(pancreas_sub)
pancreas_sub <- RunStandardWorkflow(pancreas_sub)
#> ℹ [2026-11-12 06:05:30] Start standard processing workflow...
#> ℹ [2026-11-12 06:05:30] Checking a list of <Seurat>...
#> ! [2026-11-12 06:05:30] Data 1/1 of the `srt_list` is "unknown"
#> ℹ [2026-11-12 06:05:30] Perform `NormalizeData()` with `normalization.method = 'LogNormalize'` on 1/1 of `srt_list`...
#> ℹ [2026-11-12 06:05:30] Perform `FindVariableFeatures()` on 1/1 of `srt_list`...
#> ℹ [2026-11-12 06:05:30] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 06:05:30] Number of available HVF: 2000
#> ℹ [2026-11-12 06:05:30] Finished check
#> ℹ [2026-11-12 06:05:30] Perform `ScaleData()`
#> ℹ [2026-11-12 06:05:30] Perform pca linear dimension reduction
#> ℹ [2026-11-12 06:05:31] Use stored estimated dimensions 1:23 for Standardpca
#> ℹ [2026-11-12 06:05:31] Perform `Seurat::FindClusters()` with `cluster_algorithm = 'louvain'` and `cluster_resolution = 0.6`
#> ℹ [2026-11-12 06:05:31] Reorder clusters...
#> ℹ [2026-11-12 06:05:31] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 06:05:31] Perform umap nonlinear dimension reduction
#> ✔ [2026-11-12 06:05:41] Standard processing workflow completed
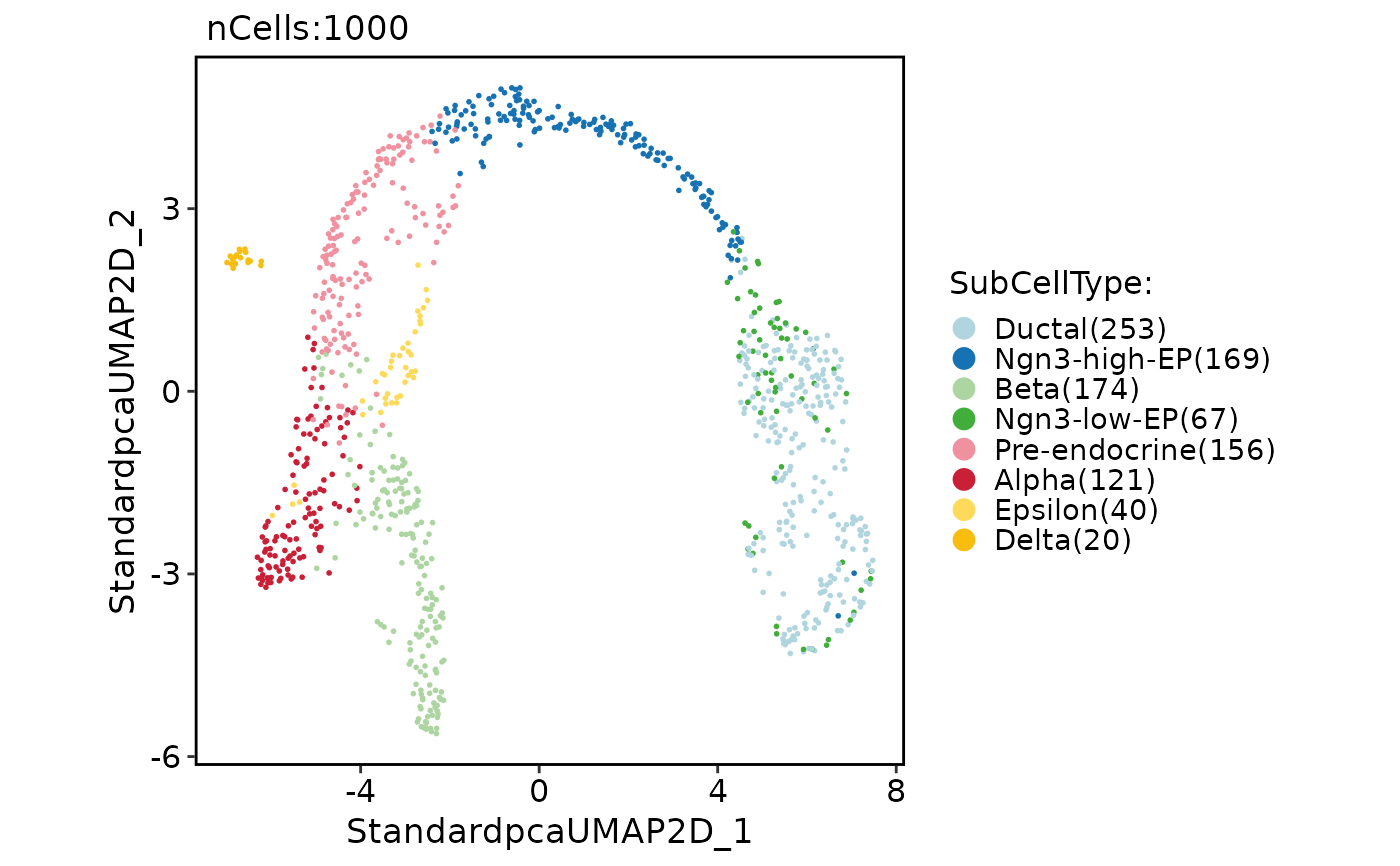
CellDimPlot(
pancreas_sub,
group.by = "SubCellType"
)
 # Use a combination of different linear
# or nonlinear dimension reduction methods
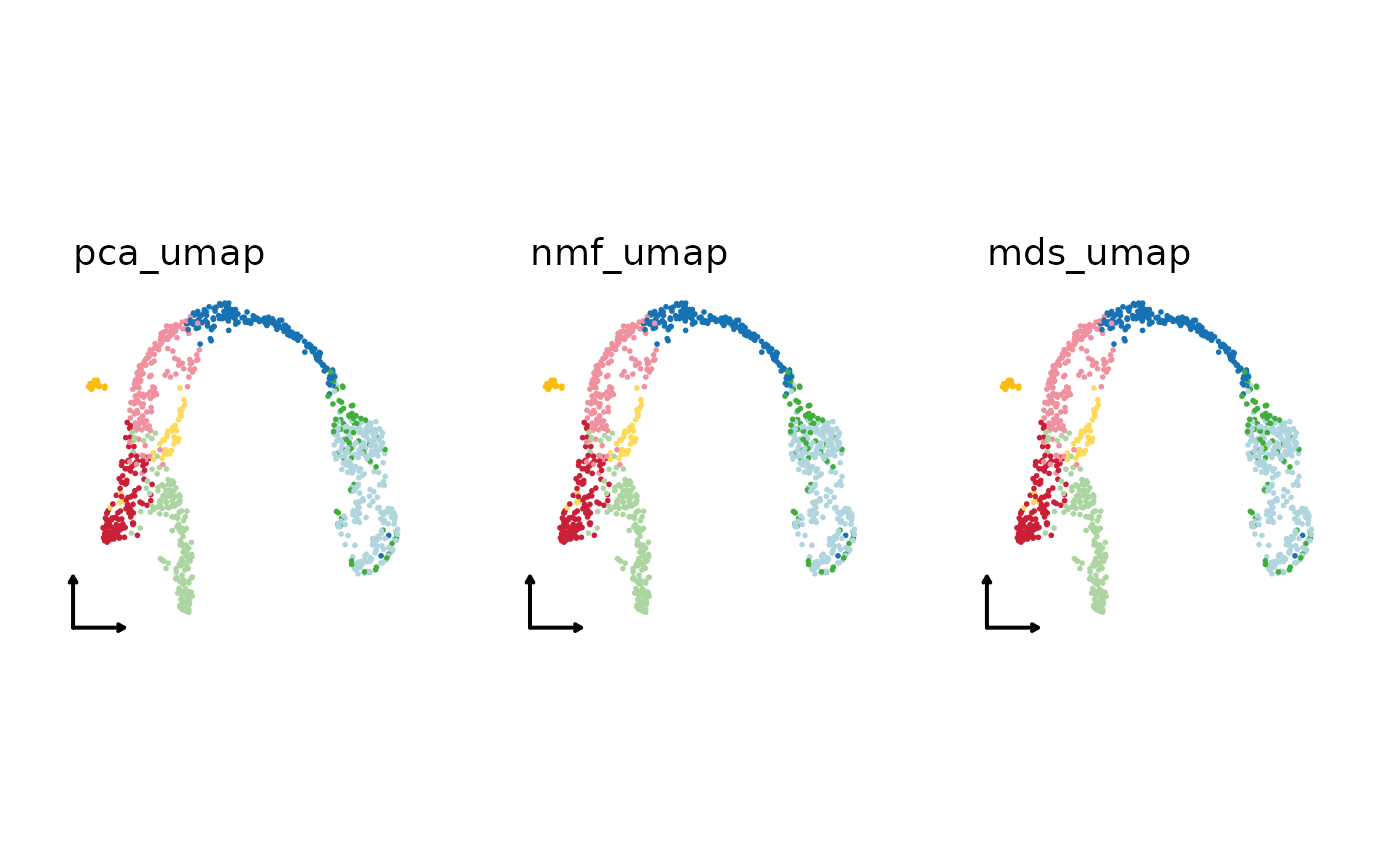
linear_reductions <- c(
"pca", "nmf", "mds"
)
pancreas_sub <- RunStandardWorkflow(
pancreas_sub,
linear_reduction = linear_reductions,
nonlinear_reduction = "umap"
)
#> ℹ [2026-11-12 06:05:41] Start standard processing workflow...
#> ℹ [2026-11-12 06:05:41] Checking a list of <Seurat>...
#> ℹ [2026-11-12 06:05:42] Data 1/1 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 06:05:42] Perform `FindVariableFeatures()` on 1/1 of `srt_list`...
#> ℹ [2026-11-12 06:05:42] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 06:05:42] Number of available HVF: 2000
#> ℹ [2026-11-12 06:05:42] Finished check
#> ℹ [2026-11-12 06:05:42] Perform `ScaleData()`
#> ℹ [2026-11-12 06:05:42] Perform pca linear dimension reduction
#> ℹ [2026-11-12 06:05:42] Use stored estimated dimensions 1:23 for Standardpca
#> ℹ [2026-11-12 06:05:43] Perform `Seurat::FindClusters()` with `cluster_algorithm = 'louvain'` and `cluster_resolution = 0.6`
#> ℹ [2026-11-12 06:05:43] Reorder clusters...
#> ℹ [2026-11-12 06:05:43] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 06:05:43] Perform umap nonlinear dimension reduction
#> ℹ [2026-11-12 06:05:52] Perform nmf linear dimension reduction
#> ℹ [2026-11-12 06:05:52] Running NMF...
#> ℹ StandardBE_ 1
#> ℹ Positive: Ccnd1, Spp1, Mdk, Rps2, Ldha, Pebp1, Cd24a, Dlk1, Krt8, Mgst1
#> ℹ Clu, Gapdh, Eno1, Prdx1, Cldn10, Mif, Cldn7, Npm1, Dbi, Vim
#> ℹ Sox9, Rpl12, Aldh1b1, Rplp1, Wfdc2, Krt18, Tkt, Aldoa, Hspe1, Ptma
#> ℹ Negative: Tmem108, Poc1a, Epn3, Wipi1, Tmcc3, Nhsl1, Fgf12, Plekho1, Tecpr2, Zbtb4
#> ℹ Gm10941, Trf, Man1c1, Hmgcs1, Nipal1, Jam3, Pgap1, Alpl, Kcnip3, Tnr
#> ℹ Gm15915, Rbp2, Cbfa2t2, Sh2d4a, Bbc3, Megf6, Naaladl2, Fam46d, Hist2h2ac, Tox2
#> ℹ StandardBE_ 2
#> ℹ Positive: Spp1, Gsta3, Sparc, Vim, Atp1b1, Mt1, Dbi, Anxa2, Rps2, Id2
#> ℹ Rpl22l1, Rplp1, Mgst1, Clu, Sox9, Cldn6, Mdk, Pdzk1ip1, Bicc1, 1700011H14Rik
#> ℹ Rps12, S100a10, Cldn3, Rpl36a, Ppp1r1b, Adamts1, Serpinh1, Mt2, Ifitm2, Rpl39
#> ℹ Negative: Rpa3, Aacs, Tmem108, Poc1a, Epn3, Wipi1, B830012L14Rik, Tmcc3, Wsb1, Plekho1
#> ℹ Ppp2r2b, Tecpr2, Zbtb4, Haus8, Trf, Gm5420, Man1c1, Hmgcs1, Nipal1, Jam3
#> ℹ Tcerg1, Pgap1, Snrpa1, Alpl, Larp1b, Kcnip3, Tnr, Lsm12, Ptbp3, Gm15915
#> ℹ StandardBE_ 3
#> ℹ Positive: Cck, Mdk, Gadd45a, Neurog3, Selm, Sox4, Btbd17, Tmsb4x, Btg2, Cldn6
#> ℹ Cotl1, Ptma, Jun, Ppp1r14a, Rps2, Ifitm2, Neurod2, Igfbpl1, Gnas, Krt7
#> ℹ Nkx6-1, Aplp1, Ppp3ca, Lrpap1, Rplp1, Hn1, Rps12, Mfng, BC023829, Smarcd2
#> ℹ Negative: Elovl6, Tmem108, Poc1a, Epn3, Nop56, Wipi1, B830012L14Rik, Rrp15, Rfc1, Fgf12
#> ℹ Slc20a1, Ppp2r2b, Lama1, Tecpr2, Zbtb4, Eif1ax, Fam162a, P4ha3, Gm10941, Tenm4
#> ℹ Pde4b, Gm5420, Man1c1, Hmgcs1, Pgap1, Mgst2, Larp1b, Kcnip3, Tnr, Lsm12
#> ℹ StandardBE_ 4
#> ℹ Positive: Spp1, Cyr61, Krt18, Tpm1, Krt8, Myl12a, Vim, Jun, Anxa5, Tnfrsf12a
#> ℹ Csrp1, Sparc, Cldn7, Nudt19, Anxa2, Clu, Myl9, Atp1b1, Cldn3, Tagln2
#> ℹ S100a10, 1700011H14Rik, Cd24a, Rps2, Dbi, Id2, Lurap1l, Rplp1, Myl12b, Klf6
#> ℹ Negative: Rpa3, Elovl6, Aacs, Tmem108, Poc1a, Tmcc3, Rfc1, Plekho1, Slc20a1, Ppp2r2b
#> ℹ Lama1, Tecpr2, Gm10941, Tenm4, Pde4b, Man1c1, Nipal1, Jam3, Pgap1, Alpl
#> ℹ Mgst2, Kcnip3, Tnr, Ptbp3, Gm15915, Cntln, Ocln, Fras1, Rbp2, Cbfa2t2
#> ℹ StandardBE_ 5
#> ℹ Positive: 2810417H13Rik, Rrm2, Hmgb2, Dut, Pcna, Lig1, H2afz, Tipin, Tuba1b, Tk1
#> ℹ Mcm5, Dek, Tyms, Gmnn, Ran, Tubb5, Rfc2, Srsf2, Ranbp1, Orc6
#> ℹ Mcm3, Uhrf1, Gins2, Dnajc9, Mcm6, Siva1, Rfc3, Mcm7, Rpa2, Ptma
#> ℹ Negative: 1110002L01Rik, Aacs, Wipi1, B830012L14Rik, Tmcc3, Trib1, Fgf12, Plekho1, Ppp2r2b, Lama1
#> ℹ Tenm4, Trf, Gm5420, Man1c1, Jam3, Mgst2, Kcnip3, Tnr, Gm15915, Cbfa2t2
#> ℹ Sh2d4a, Bbc3, Fkbp9, Ano6, Prkcb, Megf6, Fam46d, Slc52a3, Ankrd2, Tox2
#> ✔ [2026-11-12 06:06:03] NMF compute completed
#> ℹ [2026-11-12 06:06:03] Use stored estimated dimensions 1:50 for Standardnmf
#> ℹ [2026-11-12 06:06:03] Perform `Seurat::FindClusters()` with `cluster_algorithm = 'louvain'` and `cluster_resolution = 0.6`
#> ℹ [2026-11-12 06:06:03] Reorder clusters...
#> ℹ [2026-11-12 06:06:03] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 06:06:03] Perform umap nonlinear dimension reduction
#> ℹ [2026-11-12 06:06:13] Perform mds linear dimension reduction
#> ℹ [2026-11-12 06:06:14] Use stored estimated dimensions 1:13 for Standardmds
#> ℹ [2026-11-12 06:06:14] Perform `Seurat::FindClusters()` with `cluster_algorithm = 'louvain'` and `cluster_resolution = 0.6`
#> ℹ [2026-11-12 06:06:14] Reorder clusters...
#> ℹ [2026-11-12 06:06:14] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 06:06:14] Perform umap nonlinear dimension reduction
#> ✔ [2026-11-12 06:06:24] Standard processing workflow completed
plist1 <- lapply(
linear_reductions, function(lr) {
CellDimPlot(
pancreas_sub,
group.by = "SubCellType",
reduction = paste0(
"Standard", lr, "UMAP2D"
),
xlab = "", ylab = "",
title = paste0(lr, "_umap"),
legend.position = "none",
theme_use = "theme_blank"
)
}
)
patchwork::wrap_plots(plist1)
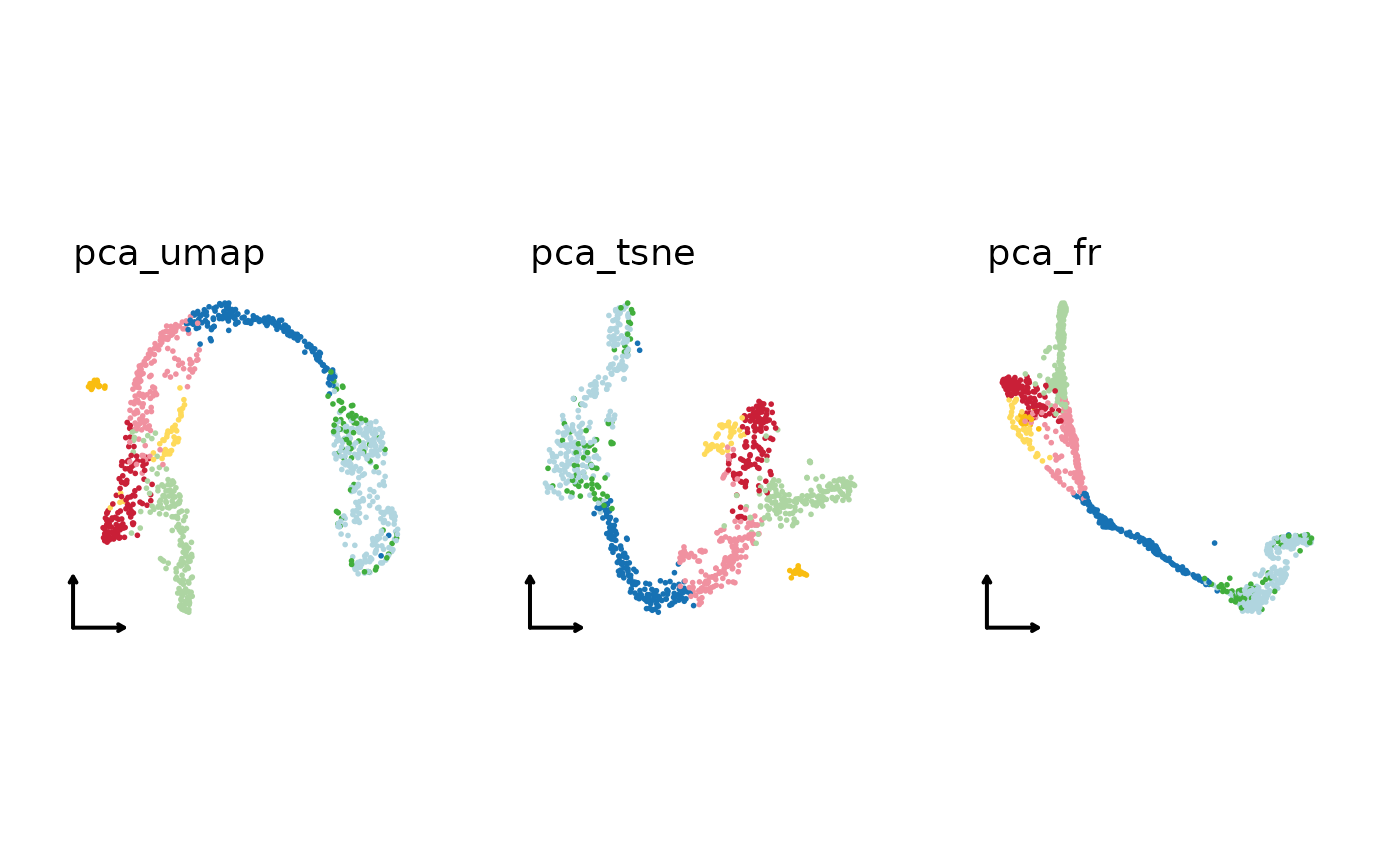
 nonlinear_reductions <- c(
"umap", "tsne", "fr"
)
pancreas_sub <- RunStandardWorkflow(
pancreas_sub,
linear_reduction = "pca",
nonlinear_reduction = nonlinear_reductions
)
#> ℹ [2026-11-12 06:06:24] Start standard processing workflow...
#> ℹ [2026-11-12 06:06:24] Checking a list of <Seurat>...
#> ℹ [2026-11-12 06:06:25] Data 1/1 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 06:06:25] Perform `FindVariableFeatures()` on 1/1 of `srt_list`...
#> ℹ [2026-11-12 06:06:25] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 06:06:25] Number of available HVF: 2000
#> ℹ [2026-11-12 06:06:25] Finished check
#> ℹ [2026-11-12 06:06:25] Perform `ScaleData()`
#> ℹ [2026-11-12 06:06:25] Perform pca linear dimension reduction
#> ℹ [2026-11-12 06:06:26] Use stored estimated dimensions 1:23 for Standardpca
#> ℹ [2026-11-12 06:06:26] Perform `Seurat::FindClusters()` with `cluster_algorithm = 'louvain'` and `cluster_resolution = 0.6`
#> ℹ [2026-11-12 06:06:26] Reorder clusters...
#> ℹ [2026-11-12 06:06:26] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 06:06:26] Perform umap nonlinear dimension reduction
#> ℹ [2026-11-12 06:06:36] Perform tsne nonlinear dimension reduction
#> ℹ [2026-11-12 06:06:36] Perform tsne nonlinear dimension reduction using Standardpca (1:23)
#> ℹ [2026-11-12 06:06:39] Perform fr nonlinear dimension reduction
#> ℹ [2026-11-12 06:06:39] Perform fr nonlinear dimension reduction using Standardpca_SNN
#> ✔ [2026-11-12 06:06:40] Standard processing workflow completed
plist2 <- lapply(
nonlinear_reductions, function(nr) {
CellDimPlot(
pancreas_sub,
group.by = "SubCellType",
reduction = paste0(
"Standardpca", nr, "2D"
),
xlab = "", ylab = "",
title = paste0("pca_", nr),
legend.position = "none",
theme_use = "theme_blank"
)
}
)
patchwork::wrap_plots(plist2)
 data(visium_human_pancreas_sub)
spatial <- RunStandardWorkflow(
visium_human_pancreas_sub,
workflow = "spatial",
assay = "Spatial",
do_spatial_cluster = FALSE,
spatial_cluster_method = "BayesSpace",
do_deconvolution = FALSE,
deconvolution_method = "RCTD",
linear_reduction_dims = 10,
linear_reduction_dims_use = 1:5,
nonlinear_reduction_dims = 2,
spatial_variable_features_params = list(nfeatures = 50)
)
#> ℹ [2026-11-12 06:06:41] Start standard spot-level spatial workflow...
#> ◌ [2026-11-12 06:06:41] Running spot-level quality control
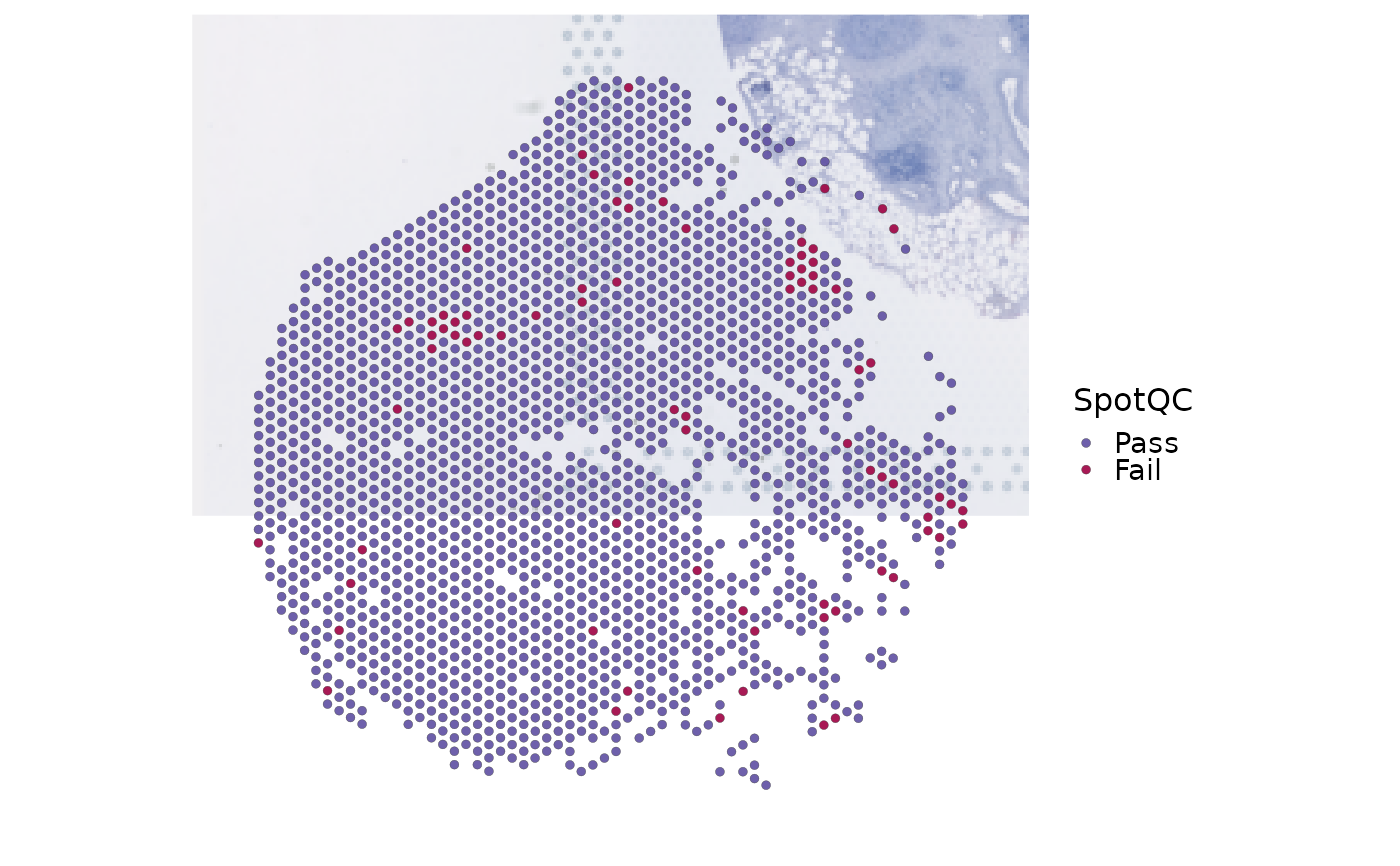
#> ✔ [2026-11-12 06:06:41] Spot QC completed: 1986 evaluated, 1907 Pass, 79 Fail
#> ℹ Scope assay "Spatial", layer "counts"
#> ℹ Saved metadata column `SpotQC`
#> ℹ Plot returned object `SpatialSpotPlot(<returned_object>, group.by = "SpotQC")`
#> ℹ [2026-11-12 06:06:41] Start standard processing workflow...
#> ℹ [2026-11-12 06:06:41] Checking a list of <Seurat>...
#> ! [2026-11-12 06:06:41] Data 1/1 of the `srt_list` is "unknown"
#> ℹ [2026-11-12 06:06:41] Perform `NormalizeData()` with `normalization.method = 'LogNormalize'` on 1/1 of `srt_list`...
#> ℹ [2026-11-12 06:06:41] Perform `FindVariableFeatures()` on 1/1 of `srt_list`...
#> ℹ [2026-11-12 06:06:41] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 06:06:41] Number of available HVF: 2000
#> ℹ [2026-11-12 06:06:41] Finished check
#> ℹ [2026-11-12 06:06:41] Perform `ScaleData()`
#> ℹ [2026-11-12 06:06:41] Perform pca linear dimension reduction
#> ℹ [2026-11-12 06:06:42] Perform `Seurat::FindClusters()` with `cluster_algorithm = 'louvain'` and `cluster_resolution = 0.6`
#> ℹ [2026-11-12 06:06:43] Reorder clusters...
#> ℹ [2026-11-12 06:06:43] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 06:06:43] Perform umap nonlinear dimension reduction
#> ✔ [2026-11-12 06:06:54] Standard processing workflow completed
#> ◌ [2026-11-12 06:06:54] Running spatial variable feature detection
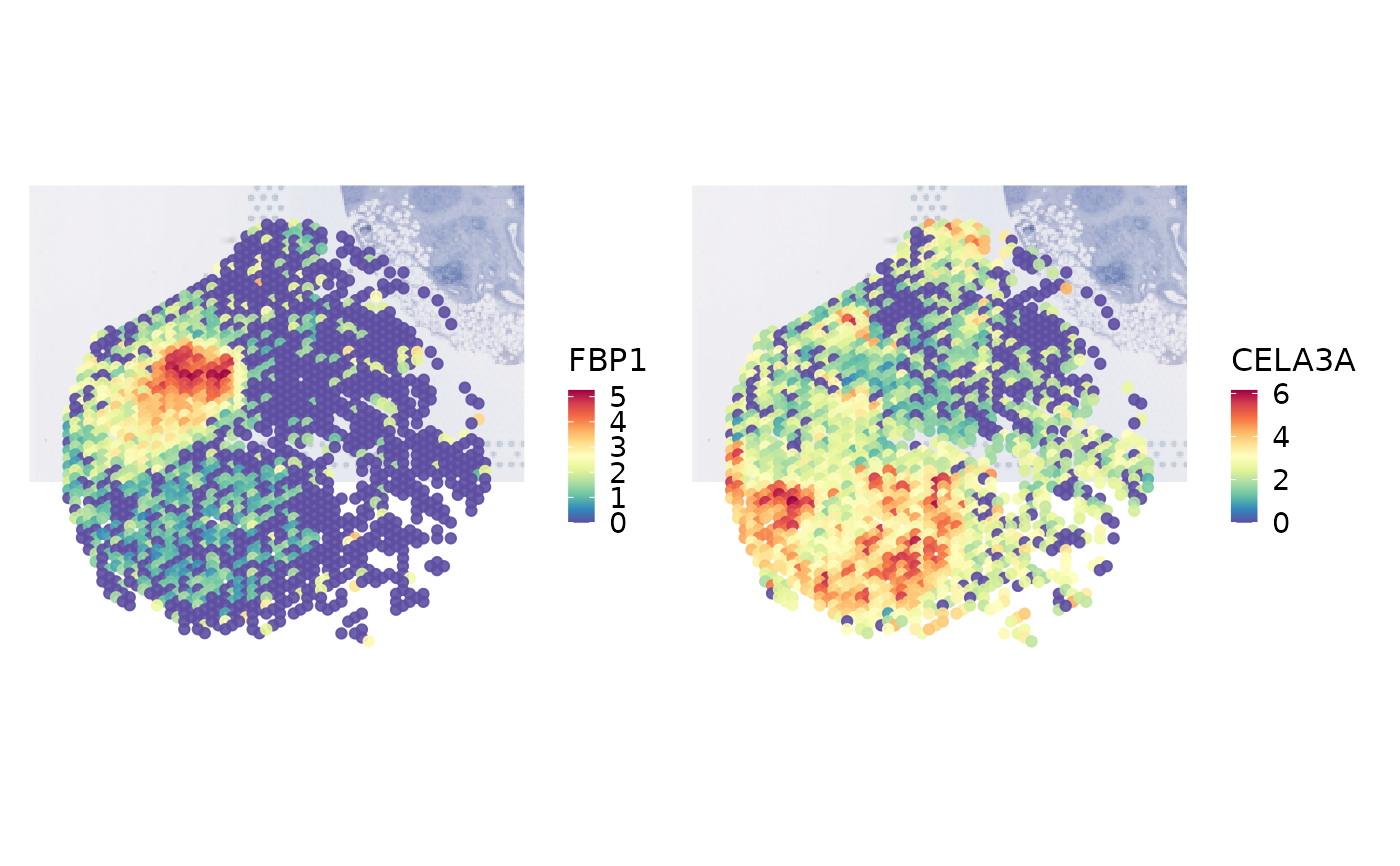
#> ✔ [2026-11-12 06:06:54] Spatial variable features completed: 2000 tested, 50 ranked in the top set
#> ℹ Scope method "moran" ("cpp" backend); assay "Spatial", layer "data"; 1986 spots; coordinates "raw"
#> ℹ Saved full result in returned object tool bundle `SpatialVariableFeatures`
#> ℹ Plot returned object `SpatialVariableFeaturePlot(<returned_object>, plot_type = "combined", assay = "Spatial", image = "slice1", coord.cols = c("x", "y"))`
#> ✔ [2026-11-12 06:06:54] Standard spot-level spatial workflow completed
SpatialSpotPlot(spatial, group.by = "SpotQC")
 SpatialSpotPlot(
spatial,
features = spatial@tools[["SpatialVariableFeatures"]]$summary$top_features[1:2]
)
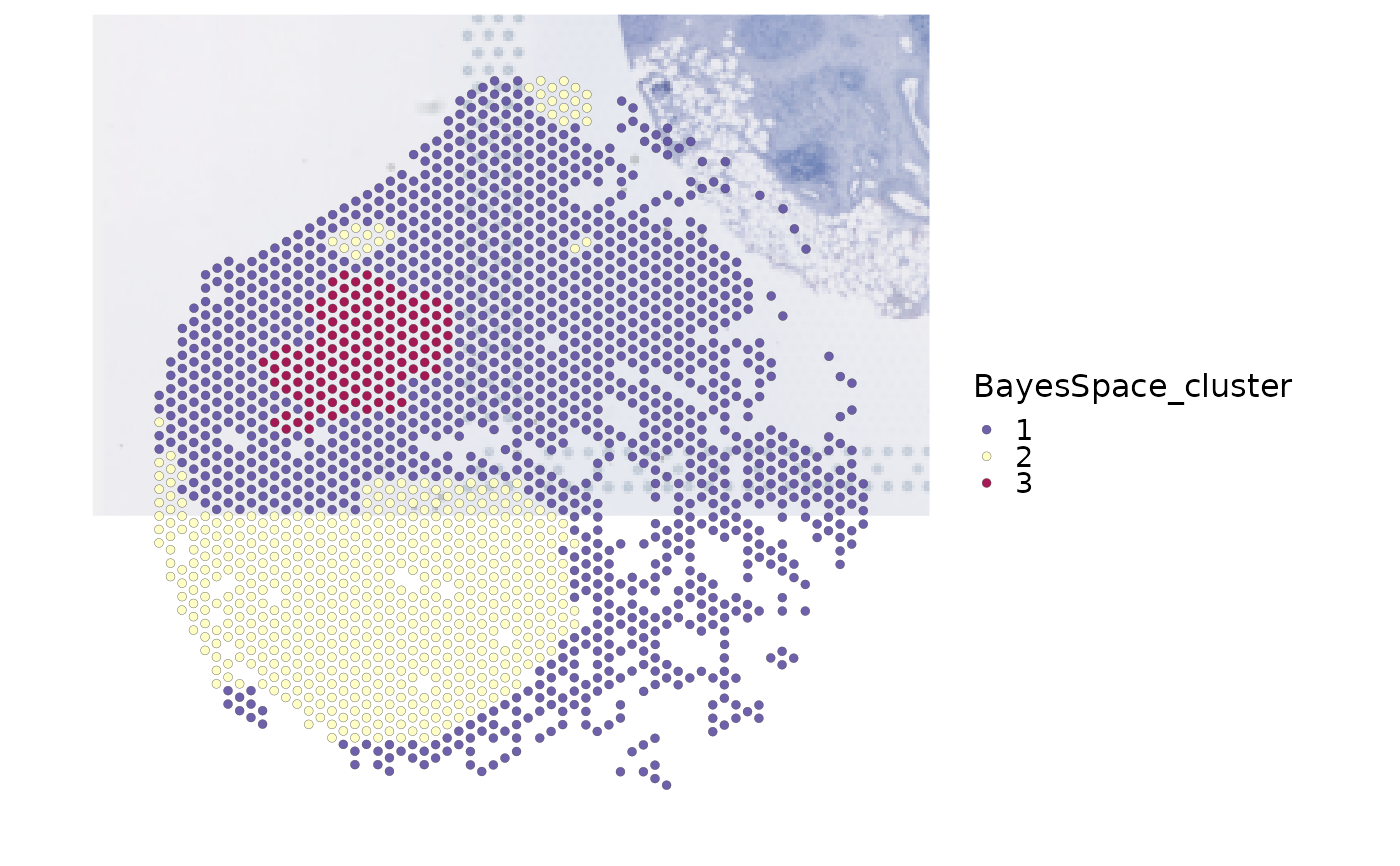
 spatial_bayes <- RunStandardWorkflow(
visium_human_pancreas_sub,
workflow = "spatial",
assay = "Spatial",
do_spatial_cluster = TRUE,
spatial_cluster_method = "BayesSpace",
spatial_q = 3,
do_deconvolution = FALSE,
deconvolution_method = "RCTD",
bayesspace_params = list(
n.PCs = 5,
n.HVGs = 200,
store_sce = FALSE,
spatial_cluster_params = list(
nrep = 200,
burn.in = 50,
thin = 10,
save.chain = FALSE
)
)
)
#> ℹ [2026-11-12 06:06:55] Start standard spot-level spatial workflow...
#> ◌ [2026-11-12 06:06:55] Running spot-level quality control
#> ✔ [2026-11-12 06:06:55] Spot QC completed: 1986 evaluated, 1907 Pass, 79 Fail
#> ℹ Scope assay "Spatial", layer "counts"
#> ℹ Saved metadata column `SpotQC`
#> ℹ Plot returned object `SpatialSpotPlot(<returned_object>, group.by = "SpotQC")`
#> ℹ [2026-11-12 06:06:55] Start standard processing workflow...
#> ℹ [2026-11-12 06:06:55] Checking a list of <Seurat>...
#> ! [2026-11-12 06:06:55] Data 1/1 of the `srt_list` is "unknown"
#> ℹ [2026-11-12 06:06:55] Perform `NormalizeData()` with `normalization.method = 'LogNormalize'` on 1/1 of `srt_list`...
#> ℹ [2026-11-12 06:06:55] Perform `FindVariableFeatures()` on 1/1 of `srt_list`...
#> ℹ [2026-11-12 06:06:55] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 06:06:55] Number of available HVF: 2000
#> ℹ [2026-11-12 06:06:55] Finished check
#> ℹ [2026-11-12 06:06:55] Perform `ScaleData()`
#> ℹ [2026-11-12 06:06:55] Perform pca linear dimension reduction
#> ℹ [2026-11-12 06:06:56] Use stored estimated dimensions 1:30 for Standardpca
#> ℹ [2026-11-12 06:06:57] Perform `Seurat::FindClusters()` with `cluster_algorithm = 'louvain'` and `cluster_resolution = 0.6`
#> ℹ [2026-11-12 06:06:57] Reorder clusters...
#> ℹ [2026-11-12 06:06:57] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 06:06:57] Perform umap nonlinear dimension reduction
#> ✔ [2026-11-12 06:07:09] Standard processing workflow completed
#> ◌ [2026-11-12 06:07:09] Running spatial variable feature detection
#> ✔ [2026-11-12 06:07:09] Spatial variable features completed: 2000 tested, 2000 ranked in the top set
#> ℹ Scope method "moran" ("cpp" backend); assay "Spatial", layer "data"; 1986 spots; coordinates "raw"
#> ℹ Saved full result in returned object tool bundle `SpatialVariableFeatures`
#> ℹ Plot returned object `SpatialVariableFeaturePlot(<returned_object>, plot_type = "combined", assay = "Spatial", image = "slice1", coord.cols = c("x", "y"))`
#> ℹ [2026-11-12 06:07:09] Convert <Seurat> to <SingleCellExperiment> for BayesSpace
#> ℹ [2026-11-12 06:07:09] Run BayesSpace spatial clustering with `q = 3`
#> Neighbors were identified for 1974 out of 1986 spots.
#> Fitting model...
#> Calculating labels using iterations 51 through 200.
#> ✔ [2026-11-12 06:07:15] BayesSpace completed: 1986 spots, 3 domains, domain size 131-1308
#> ℹ Scope assay "Spatial", image "slice1", raw coordinates
#> ℹ Saved metadata column `BayesSpace_cluster` and returned object tool bundle `BayesSpace`
#> ℹ Plot returned object `SpatialSpotPlot(<returned_object>, group.by = "BayesSpace_cluster", image = "slice1")`
#> ✔ [2026-11-12 06:07:15] Standard spot-level spatial workflow completed
SpatialSpotPlot(spatial_bayes, group.by = "BayesSpace_cluster")