CellRank and Palantir fate workflow
Source:vignettes/cellrank-palantir-fate-workflow.Rmd
cellrank-palantir-fate-workflow.RmdThis workflow keeps the Palantir pseudotime direction and the CellRank fate model as separate, inspectable result layers. Pseudotime is a relative ordering and fate probabilities are model-based transition probabilities; neither is a direct experimental time course.
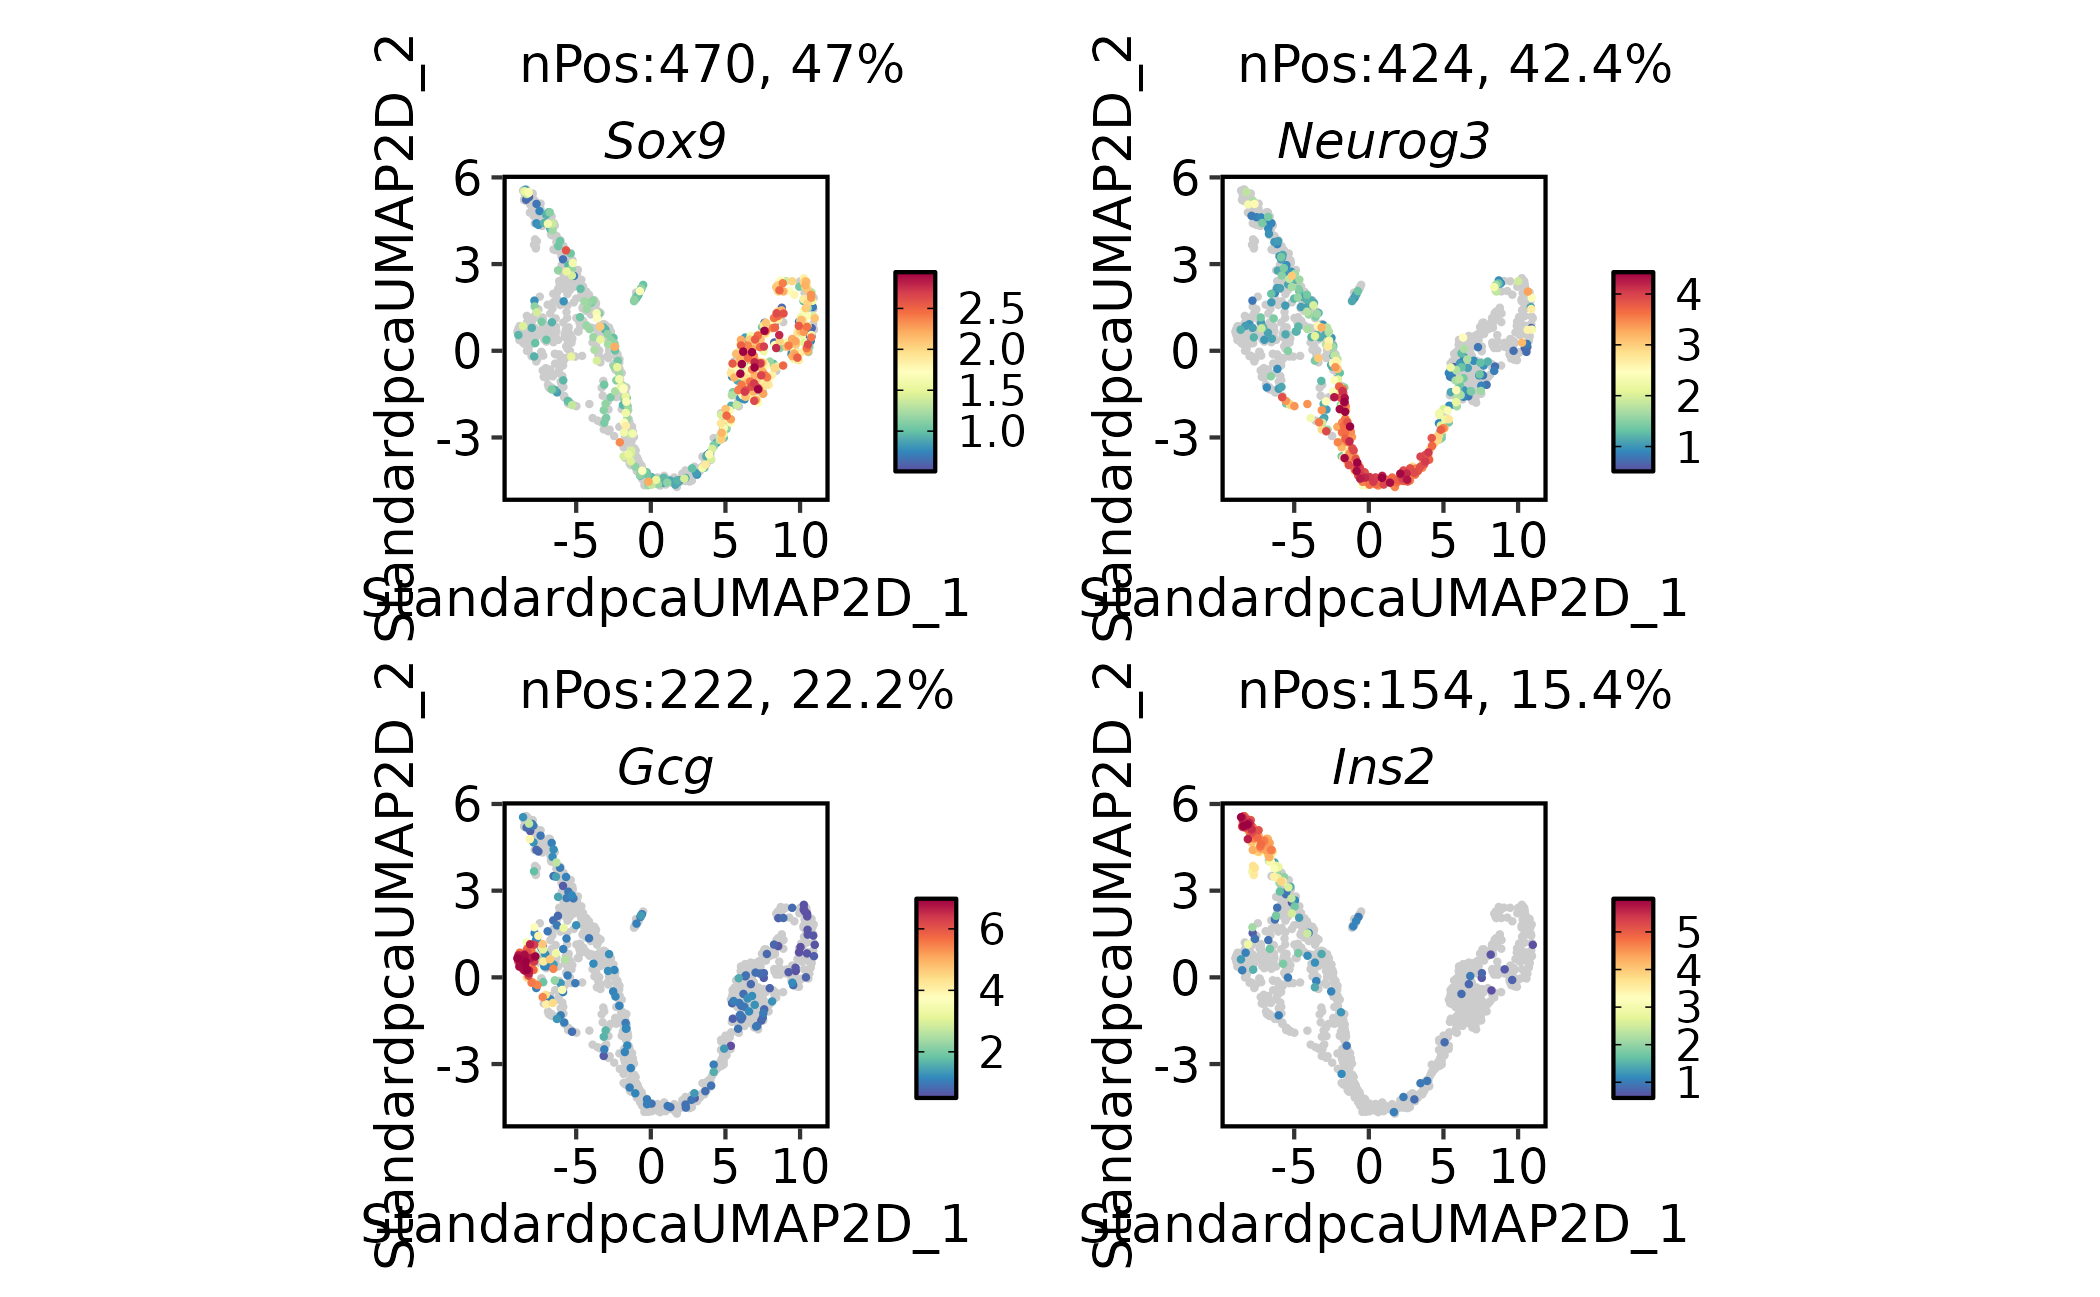
The input overview below is executed on all bundled cells. The Python analysis sections are code-only recipes and do not claim fitted Palantir or CellRank results from this website build. Run them in a prepared Python environment in the order shown; the overview embedding alone is not evidence of cell fate.
Inspect the input
library(scop)
data(pancreas_sub)
input_cells <- colnames(pancreas_sub)
pancreas_sub <- RunStandardWorkflow(pancreas_sub,
  assay = "RNA", seed = 11,
  cores = 1, verbose = FALSE
)
stopifnot(identical(colnames(pancreas_sub), input_cells))
table(pancreas_sub$SubCellType)
##
## Alpha Beta Delta Ductal Epsilon
## 121 174 20 253 40
## Ngn3-high-EP Ngn3-low-EP Pre-endocrine
## 169 67 156
CellDimPlot(pancreas_sub, group.by = "SubCellType", reduction = "UMAP", label = TRUE)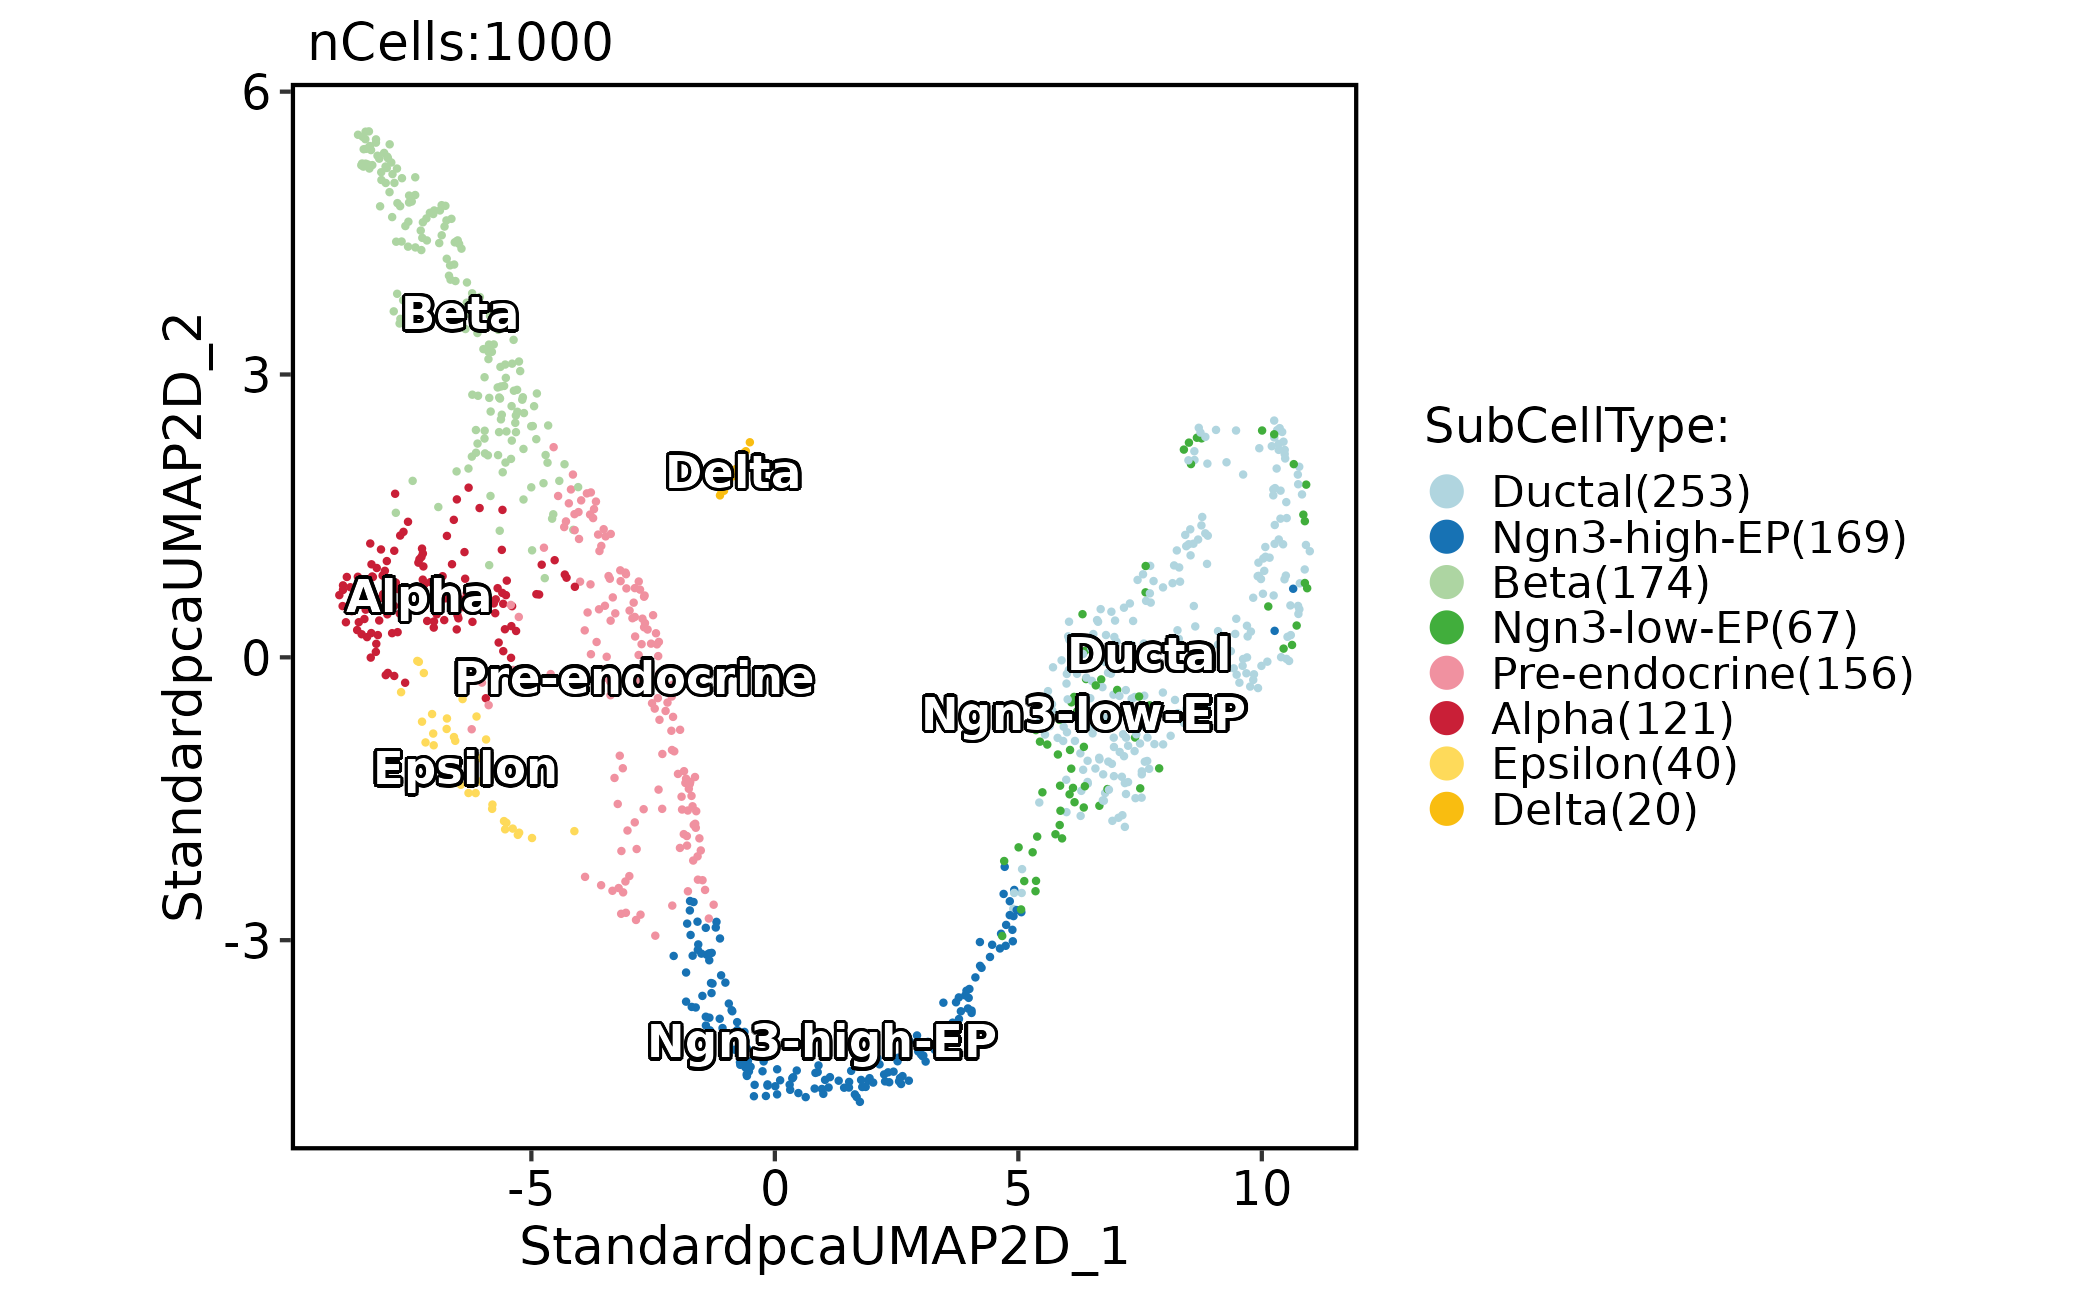
FeatureDimPlot(pancreas_sub,
  features = c("Sox9", "Neurog3", "Gcg", "Ins2"),
  reduction = "UMAP", ncol = 2
)
Palantir direction and MAGIC layer
The Python reference backend reuses the SCOP environment selected by
PrepareEnv(). Existing Python 3.10/3.11 environments
receive the compatible legacy pins, while Python 3.12 environments
receive the current pins. MAGIC is optional and should be used for
visualization or trend fitting, never as a replacement for raw counts in
differential testing.
pancreas_sub <- RunPalantir(
  pancreas_sub,
  group.by = "SubCellType",
  linear_reduction = "PCA",
  nonlinear_reduction = "UMAP",
  early_group = "Ductal",
  terminal_groups = c("Alpha", "Beta", "Delta", "Epsilon"),
  magic_impute = TRUE,
  backend = "python"
)
FeatureDimPlot(
  pancreas_sub,
  features = c("palantir_pseudotime", "palantir_diff_potential")
)
PalantirTrajectoryPlot(pancreas_sub, reduction = "UMAP")
CellRank fate mapping
Use the stored Palantir pseudotime to construct a directed
PseudotimeKernel. The explicit Schur size makes the small
tutorial run reproducible. The computed macrostate names are printed
before any optional manual terminal-state rerun; unknown terminal states
stop before the Seurat object is mutated.
pancreas_sub <- RunCellRank(
  pancreas_sub,
  group.by = "SubCellType",
  kernel_type = "pseudotime",
  time_key = "palantir_pseudotime",
  # `brandts` is portable for small tutorial data; use `krylov` only after
  # installing PETSc/SLEPc in the selected environment.
  schur_method = "brandts",
  schur_n_components = 10L,
  n_macrostates = 8L,
  n_cells_terminal = 10L,
  backend = "python"
)
names(pancreas_sub@tools$CellRank)
pancreas_sub@tools$CellRank$states$macrostate_names
CellRankPlot(pancreas_sub, plot_type = "fate", reduction = "UMAP")
CellRankPlot(pancreas_sub, plot_type = "circular")
Drivers, trends and enrichment
Drivers are statistical associations with fate probabilities. Trend modules are similar expression-shape clusters, not causal regulatory modules.
Use the common dynamic-feature workflow to fit and display expression
along Palantir pseudotime. These fits use
RunDynamicFeatures(); the separate CellRank GAM workflow
below uses fate-probability weights.
pancreas_sub <- RunDynamicFeatures(
  pancreas_sub,
  lineages = "palantir_pseudotime",
  features = c("Rbp4", "Sst", "Pyy"),
  assay = "RNA"
)
DynamicHeatmap(
  pancreas_sub,
  lineages = "palantir_pseudotime",
  features = c("Rbp4", "Sst", "Pyy"),
  use_fitted = TRUE,
  assay = "RNA",
  cell_annotation = "SubCellType"
)
DynamicPlot(
  pancreas_sub,
  lineages = "palantir_pseudotime",
  features = c("Rbp4", "Sst", "Pyy"),
  assay = "RNA",
  group.by = "SubCellType"
)
pancreas_sub <- RunCellRankTrends(
  pancreas_sub,
  lineage = "Alpha",
  assay = "MAGIC_imputed_data",
  layer = "counts",
  top_n = 500L,
  heatmap_n = 50L,
  n_points = 200L,
  output_dir = "cellrank_objects"
)
CellRankPlot(pancreas_sub, plot_type = "drivers", lineage = "Alpha")

pancreas_sub <- RunCellRankEnrichment(
  pancreas_sub,
  lineage = "Alpha",
  species = "Mus_musculus",
  output_dir = "cellrank_objects"
)
pancreas_sub@tools$CellRank$enrichment$Alpha$manifest
EnrichmentPlot(
  res = list(enrichment = pancreas_sub@tools$CellRank$enrichment$Alpha$databases$GO_BP),
  db = "GO_BP",
  plot_type = "comparison"
)
After executing the Python sections, the complete payload is stored
in srt@tools$Palantir and srt@tools$CellRank,
including the actual backend, versions, cell/lineage names, transition
matrix, fate probabilities, drivers, trend curves, modules, enrichment
tables and run parameters.