Integrate single-cell data with one or more methods. For ChromatinAssay,
the workflow uses TFIDF + SVD/LSI; Uncorrected is supported directly,
Harmony5 is redirected to Harmony, and Seurat/RPCA are not supported.
Usage
RunIntegration(
  srt_merge = NULL,
  batch,
  append = TRUE,
  srt_list = NULL,
  assay = NULL,
  integration_methods = c("Uncorrected", "Seurat", "CCA", "RPCA", "scVI", "PeakVI",
    "PoissonVI", "WNN", "MultiMAP", "GLUE", "scVI5", "MNN", "fastMNN", "fastMNN5",
    "Harmony", "Harmony5", "Scanorama", "BBKNN", "CSS", "Coralysis", "LIGER", "Conos",
    "ComBat"),
  compute_lisi = FALSE,
  lisi_label_colnames = NULL,
  lisi_reduction = NULL,
  lisi_dims = NULL,
  lisi_prefix = NULL,
  lisi_tool_name = NULL,
  lisi_perplexity = 30,
  lisi_tol = 1e-05,
  lisi_max_iter = 50,
  lisi_knn_algorithm = c("auto", "brute_force", "clustered"),
  lisi_cores = NULL,
  lisi_max_dense_bytes = Inf,
  compute_metrics = FALSE,
  metrics_batch_col = NULL,
  metrics_celltype_col = NULL,
  metrics_reduction = NULL,
  metrics_cluster_col = NULL,
  metrics_tool_name = NULL,
  metrics_k_graph = 15,
  do_normalization = NULL,
  normalization_method = "LogNormalize",
  do_HVF_finding = TRUE,
  HVF_source = "separate",
  HVF_method = "vst",
  nHVF = 2000,
  HVF_min_intersection = 1,
  HVF = NULL,
  do_scaling = TRUE,
  vars_to_regress = NULL,
  regression_model = "linear",
  scale_within_batch = FALSE,
  linear_reduction = "pca",
  linear_reduction_dims = 50,
  linear_reduction_dims_use = NULL,
  linear_reduction_params = list(),
  force_linear_reduction = FALSE,
  nonlinear_reduction = "umap",
  nonlinear_reduction_dims = c(2, 3),
  nonlinear_reduction_params = list(),
  force_nonlinear_reduction = TRUE,
  neighbor_metric = "euclidean",
  neighbor_k = 20L,
  cluster_algorithm = "louvain",
  cluster_resolution = 0.6,
  seed = 11,
  verbose = TRUE,
  integration_method = NULL,
  ...
)
Arguments
- srt_merge
A merged `Seurat` object that includes the batch information.
- batch
Batch variable name.
- append
Append integrated results to
srt_merge.- srt_list
A list of
Seuratobjects to be checked and preprocessed.- assay
Assay to use.
NULLuses the default assay.- integration_methods
Method(s) to run. Multiple methods require
append = TRUEand are applied sequentially. ForChromatinAssay, prefer"Uncorrected"or"Harmony5".- compute_lisi, lisi_label_colnames, lisi_reduction, lisi_dims, lisi_prefix, lisi_tool_name, lisi_perplexity, lisi_tol, lisi_max_iter, lisi_knn_algorithm, lisi_cores, lisi_max_dense_bytes
LISI scores.
lisi_label_colnames = NULLusesbatchwhen it is a single metadata column;lisi_reduction = NULLusesDefaultReduction().- compute_metrics, metrics_batch_col, metrics_celltype_col, metrics_reduction, metrics_cluster_col, metrics_tool_name, metrics_k_graph
Integration summary metrics on the selected reduction.
- do_normalization
Whether data normalization should be performed.
- normalization_method
The normalization method to be used. Possible values are
"LogNormalize","SCT","TFIDF", and"scran".- do_HVF_finding, HVF_method, nHVF, HVF
Highly variable features.
HVF_methodis"vst","mvp","disp", or"scran".- HVF_source
The source of highly variable features. Possible values are
"global"and"separate".- HVF_min_intersection
The feature needs to be present in batches for a minimum number of times in order to be considered as highly variable.
- do_scaling
Force scaling via ScaleData.
- vars_to_regress
A vector of variable names to include as additional regression variables.
- regression_model
"linear","poisson", or"negativebinomial".- scale_within_batch
Scale within each batch. Only used by
"Uncorrected","Seurat","MNN","Harmony","BBKNN","CSS","ComBat".- linear_reduction, linear_reduction_dims, linear_reduction_dims_use, linear_reduction_params, force_linear_reduction
Linear reduction (
"pca","svd","ica","nmf","mds","glmpca").linear_reduction_dims_use = NULLuses estimated dimensions unless the method specifies a different default; explicit values select computed components.- nonlinear_reduction
Nonlinear reduction (
"umap","umap-naive","tsne","dm","phate","pacmap","trimap","largevis","fr").- nonlinear_reduction_dims
Number(s) of nonlinear dimensions to compute.
- nonlinear_reduction_params
Shared parameters, optionally overridden by lists named after individual nonlinear reduction methods.
- force_nonlinear_reduction
Recompute nonlinear reductions even when stored results exist.
- neighbor_metric, neighbor_k
Neighbor graph (
"euclidean","cosine","manhattan","hamming").- cluster_algorithm, cluster_resolution
Clustering (
"louvain","slm","leiden"). Largercluster_resolutionyields fewer clusters.- seed
Random seed.
- verbose
Whether to print the message. Default is
TRUE.- integration_method
Deprecated alias of
integration_methods.- ...
Arguments passed to other functions.
Value
A Seurat object. For ChromatinAssay, names follow the ATAC
convention (*lsi, *UMAP2D, cluster aliases, ATAC_default_*).
See also
Seurat_integrate, scVI_integrate, MultiMAP_integrate, WNN_integrate, GLUE_integrate, MNN_integrate, fastMNN_integrate, Harmony_integrate, Scanorama_integrate, BBKNN_integrate, CSS_integrate, Coralysis_integrate, LIGER_integrate, Conos_integrate, ComBat_integrate, RunIntegrationBenchmark, IntegrationBenchmarkPlot
Examples
data(panc8_sub)
panc8_sub <- RunIntegration(
panc8_sub,
batch = "tech",
integration_methods = "Harmony",
nHVF = 500,
linear_reduction_dims = 20,
linear_reduction_dims_use = 1:10,
nonlinear_reduction_dims = 2,
compute_lisi = TRUE,
lisi_label_colnames = "tech",
lisi_perplexity = 10
)
#> ◌ [2026-11-12 05:39:14] Run integration workflow...
#> ℹ [2026-11-12 05:39:14] Split `srt_merge` into `srt_list` by "tech"
#> ℹ [2026-11-12 05:39:14] Checking a list of <Seurat>...
#> ! [2026-11-12 05:39:15] Data 1/5 of the `srt_list` is "unknown"
#> ℹ [2026-11-12 05:39:15] Perform `NormalizeData()` with `normalization.method = 'LogNormalize'` on 1/5 of `srt_list`...
#> ℹ [2026-11-12 05:39:15] Perform `FindVariableFeatures()` on 1/5 of `srt_list`...
#> ! [2026-11-12 05:39:15] Data 2/5 of the `srt_list` is "unknown"
#> ℹ [2026-11-12 05:39:15] Perform `NormalizeData()` with `normalization.method = 'LogNormalize'` on 2/5 of `srt_list`...
#> ℹ [2026-11-12 05:39:15] Perform `FindVariableFeatures()` on 2/5 of `srt_list`...
#> ! [2026-11-12 05:39:15] Data 3/5 of the `srt_list` is "unknown"
#> ℹ [2026-11-12 05:39:15] Perform `NormalizeData()` with `normalization.method = 'LogNormalize'` on 3/5 of `srt_list`...
#> ℹ [2026-11-12 05:39:15] Perform `FindVariableFeatures()` on 3/5 of `srt_list`...
#> ! [2026-11-12 05:39:15] Data 4/5 of the `srt_list` is "unknown"
#> ℹ [2026-11-12 05:39:15] Perform `NormalizeData()` with `normalization.method = 'LogNormalize'` on 4/5 of `srt_list`...
#> ℹ [2026-11-12 05:39:15] Perform `FindVariableFeatures()` on 4/5 of `srt_list`...
#> ! [2026-11-12 05:39:15] Data 5/5 of the `srt_list` is "unknown"
#> ℹ [2026-11-12 05:39:15] Perform `NormalizeData()` with `normalization.method = 'LogNormalize'` on 5/5 of `srt_list`...
#> ℹ [2026-11-12 05:39:15] Perform `FindVariableFeatures()` on 5/5 of `srt_list`...
#> ℹ [2026-11-12 05:39:16] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 05:39:16] Number of available HVF: 500
#> ℹ [2026-11-12 05:39:16] Finished check
#> ℹ [2026-11-12 05:39:18] Perform `Seurat::ScaleData()`
#> ℹ [2026-11-12 05:39:19] Perform linear dimension reduction("pca")
#> ℹ [2026-11-12 05:39:19] Perform Harmony integration
#> ℹ [2026-11-12 05:39:19] Using "Harmonypca" (1:10) as input
#> ℹ [2026-11-12 05:39:19] Adjust neighbor k from 20 to 20 for small-sample clustering
#> ℹ [2026-11-12 05:39:20] Perform `Seurat::FindClusters()` with "louvain"
#> ℹ [2026-11-12 05:39:20] Reorder clusters...
#> ℹ [2026-11-12 05:39:20] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 05:39:20] Perform umap nonlinear dimension reduction using Harmony (1:10)
#> ℹ [2026-11-12 05:39:27] Perform umap nonlinear dimension reduction using Harmonypca (1:10)
#> ℹ [2026-11-12 05:39:34] Compute LISI scores from reduction "HarmonypcaUMAP2D"
#> ℹ [2026-11-12 05:39:34] Compute LISI scores from reduction "HarmonyUMAP2D"
#> ✔ [2026-11-12 05:39:34] Stored LISI scores in metadata: "HarmonypcaUMAP2D_tech_LISI" and "HarmonyUMAP2D_tech_LISI"
#> ✔ [2026-11-12 05:39:35] Harmony integration completed
CellDimPlot(
panc8_sub,
group.by = c("tech", "celltype"),
reduction = "HarmonyUMAP2D"
)
 IntegrationBenchmarkPlot(panc8_sub, plot_type = "box")
 panc8_sub <- RunIntegration(
panc8_sub,
batch = "tech",
integration_methods = "LIGER"
)
#> ◌ [2026-11-12 05:39:35] Run integration workflow...
#> ℹ [2026-11-12 05:39:36] Split `srt_merge` into `srt_list` by "tech"
#> ℹ [2026-11-12 05:39:37] Checking a list of <Seurat>...
#> ℹ [2026-11-12 05:39:37] Data 1/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:39:37] Perform `FindVariableFeatures()` on 1/5 of `srt_list`...
#> ℹ [2026-11-12 05:39:37] Data 2/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:39:37] Perform `FindVariableFeatures()` on 2/5 of `srt_list`...
#> ℹ [2026-11-12 05:39:38] Data 3/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:39:38] Perform `FindVariableFeatures()` on 3/5 of `srt_list`...
#> ℹ [2026-11-12 05:39:38] Data 4/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:39:38] Perform `FindVariableFeatures()` on 4/5 of `srt_list`...
#> ℹ [2026-11-12 05:39:38] Data 5/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:39:38] Perform `FindVariableFeatures()` on 5/5 of `srt_list`...
#> ℹ [2026-11-12 05:39:38] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 05:39:38] Number of available HVF: 2000
#> ℹ [2026-11-12 05:39:38] Finished check
#> ℹ [2026-11-12 05:39:39] Prepare rliger layer "ligerScaleData" ...
#> ℹ [2026-11-12 05:39:39] Perform LIGER integration
#> ℹ [2026-11-12 05:39:44] Adjust neighbor k from 20 to 20 for small-sample clustering
#> ℹ [2026-11-12 05:39:44] Perform `Seurat::FindClusters()` with "louvain"
#> ℹ [2026-11-12 05:39:44] Reorder clusters...
#> ℹ [2026-11-12 05:39:45] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 05:39:45] Perform umap nonlinear dimension reduction using LIGER (1:20)
#> ℹ [2026-11-12 05:39:52] Perform umap nonlinear dimension reduction using LIGER (1:20)
#> ℹ [2026-11-12 05:39:59] Perform umap nonlinear dimension reduction using LIGER (1:20)
#> ✔ [2026-11-12 05:40:07] LIGER integration completed
panc8_sub <- RunIntegration(
panc8_sub,
batch = "tech",
integration_methods = "Harmony",
compute_lisi = TRUE,
lisi_label_colnames = "tech"
)
#> ◌ [2026-11-12 05:40:07] Run integration workflow...
#> ℹ [2026-11-12 05:40:08] Split `srt_merge` into `srt_list` by "tech"
#> ℹ [2026-11-12 05:40:09] Checking a list of <Seurat>...
#> ℹ [2026-11-12 05:40:09] Data 1/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:40:09] Perform `FindVariableFeatures()` on 1/5 of `srt_list`...
#> ℹ [2026-11-12 05:40:09] Data 2/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:40:09] Perform `FindVariableFeatures()` on 2/5 of `srt_list`...
#> ℹ [2026-11-12 05:40:09] Data 3/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:40:09] Perform `FindVariableFeatures()` on 3/5 of `srt_list`...
#> ℹ [2026-11-12 05:40:10] Data 4/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:40:10] Perform `FindVariableFeatures()` on 4/5 of `srt_list`...
#> ℹ [2026-11-12 05:40:10] Data 5/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:40:10] Perform `FindVariableFeatures()` on 5/5 of `srt_list`...
#> ℹ [2026-11-12 05:40:10] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 05:40:10] Number of available HVF: 2000
#> ℹ [2026-11-12 05:40:10] Finished check
#> ℹ [2026-11-12 05:40:10] Perform `Seurat::ScaleData()`
#> ℹ [2026-11-12 05:40:10] Perform linear dimension reduction("pca")
#> ℹ [2026-11-12 05:40:11] Perform Harmony integration
#> ℹ [2026-11-12 05:40:11] Using "Harmonypca" (1:20) as input
#> ℹ [2026-11-12 05:40:11] Adjust neighbor k from 20 to 20 for small-sample clustering
#> ℹ [2026-11-12 05:40:12] Perform `Seurat::FindClusters()` with "louvain"
#> ℹ [2026-11-12 05:40:12] Reorder clusters...
#> ℹ [2026-11-12 05:40:12] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 05:40:12] Perform umap nonlinear dimension reduction using Harmony (1:20)
#> ℹ [2026-11-12 05:40:19] Perform umap nonlinear dimension reduction using Harmony (1:20)
#> ℹ [2026-11-12 05:40:26] Perform umap nonlinear dimension reduction using Harmonypca (1:20)
#> ℹ [2026-11-12 05:40:33] Compute LISI scores from reduction "HarmonypcaUMAP2D"
#> ℹ [2026-11-12 05:40:33] Compute LISI scores from reduction "HarmonyUMAP2D"
#> ✔ [2026-11-12 05:40:33] Stored LISI scores in metadata: "HarmonypcaUMAP2D_tech_LISI" and "HarmonyUMAP2D_tech_LISI"
#> ✔ [2026-11-12 05:40:34] Harmony integration completed
IntegrationBenchmarkPlot(panc8_sub, plot_type = "box")
 data("pbmcmultiome_sub", package = "scop")
pbmcmultiome_sub$batch <- rep(c("batch1", "batch2"), length.out = ncol(pbmcmultiome_sub))
pbmcmultiome_sub <- RunIntegration(
pbmcmultiome_sub,
batch = "batch",
assay = "peaks",
integration_methods = "Harmony5",
normalization_method = "TFIDF"
)
#> ◌ [2026-11-12 05:40:34] Run integration workflow...
#> ! [2026-11-12 05:40:34] `integration_method = 'Harmony5'` is not compatible with <ChromatinAssay> in current Seurat v5 workflow. Automatically switch to "Harmony"
#> ℹ [2026-11-12 05:40:34] Split `srt_merge` into `srt_list` by "batch"
#> ℹ [2026-11-12 05:40:34] Checking a list of <Seurat>...
#> ! [2026-11-12 05:40:35] Data 1/2 of the `srt_list` is "raw_counts"
#> ℹ [2026-11-12 05:40:35] Perform `RunTFIDF()` on 1/2 of `srt_list`...
#> ℹ [2026-11-12 05:40:35] Perform `FindTopFeatures()` on 1/2 of `srt_list`...
#> ! [2026-11-12 05:40:35] Data 2/2 of the `srt_list` is "raw_counts"
#> ℹ [2026-11-12 05:40:35] Perform `RunTFIDF()` on 2/2 of `srt_list`...
#> ℹ [2026-11-12 05:40:35] Perform `FindTopFeatures()` on 2/2 of `srt_list`...
#> ℹ [2026-11-12 05:40:35] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 05:40:35] Number of available HVF: 2000
#> ℹ [2026-11-12 05:40:35] Finished check
#> ℹ [2026-11-12 05:40:35] `normalization_method` is "TFIDF". Use lsi workflow...
#> ℹ [2026-11-12 05:40:35] Perform linear dimension reduction("svd")
#> Running SVD
#> Scaling cell embeddings
#> ℹ [2026-11-12 05:40:36] Perform Harmony integration
#> ℹ [2026-11-12 05:40:36] Using "Harmonysvd" (2:5) as input
#> ℹ [2026-11-12 05:40:36] Perform `Seurat::FindClusters()` with "louvain"
#> ℹ [2026-11-12 05:40:36] Reorder clusters...
#> ℹ [2026-11-12 05:40:36] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 05:40:36] Perform umap nonlinear dimension reduction using Harmony (1:4)
#> ℹ [2026-11-12 05:40:42] Perform umap nonlinear dimension reduction using Harmony (1:4)
#> ✔ [2026-11-12 05:40:48] Harmony integration completed
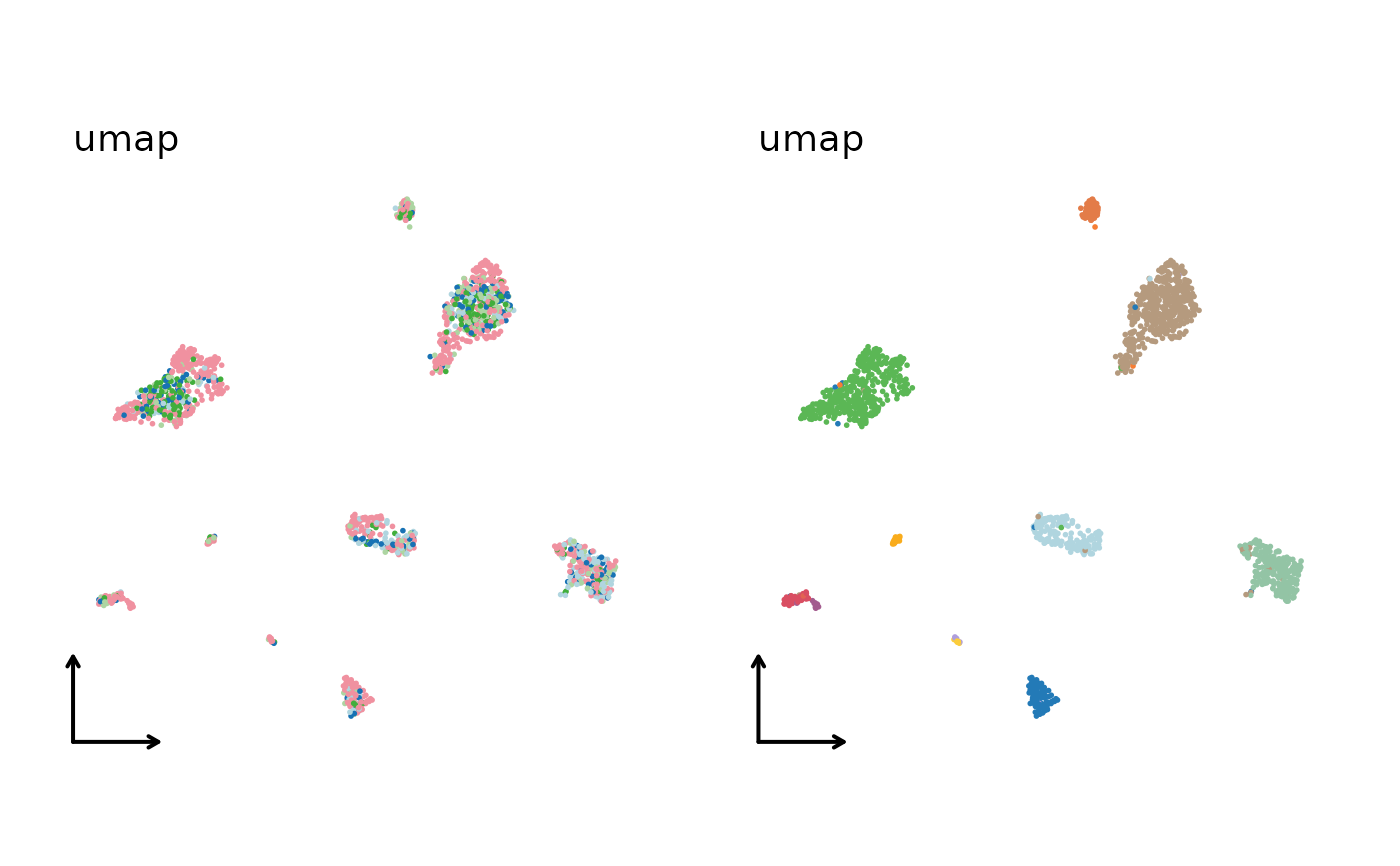
integration_methods <- c(
"Uncorrected", "Seurat", "CCA", "RPCA",
"MNN", "fastMNN", "Harmony", "Harmony5",
"Coralysis", "LIGER", "Conos", "ComBat"
)
p_list <- list()
for (method in integration_methods) {
panc8_sub <- RunIntegration(
panc8_sub,
batch = "tech",
integration_methods = method,
linear_reduction_dims_use = 1:50,
nonlinear_reduction = "umap",
RunParallelDivisiveICP_params = list(L = 10L)
)
p_list[[method]] <- CellDimPlot(
panc8_sub,
group.by = c("tech", "celltype"),
reduction = paste0(method, "UMAP2D"),
xlab = "", ylab = "",
title = method,
legend.position = "none",
theme_use = "theme_blank"
)
}
#> ◌ [2026-11-12 05:40:48] Run integration workflow...
#> ℹ [2026-11-12 05:40:49] Split `srt_merge` into `srt_list` by "tech"
#> ℹ [2026-11-12 05:40:50] Checking a list of <Seurat>...
#> ℹ [2026-11-12 05:40:50] Data 1/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:40:50] Perform `FindVariableFeatures()` on 1/5 of `srt_list`...
#> ℹ [2026-11-12 05:40:50] Data 2/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:40:50] Perform `FindVariableFeatures()` on 2/5 of `srt_list`...
#> ℹ [2026-11-12 05:40:50] Data 3/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:40:50] Perform `FindVariableFeatures()` on 3/5 of `srt_list`...
#> ℹ [2026-11-12 05:40:51] Data 4/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:40:51] Perform `FindVariableFeatures()` on 4/5 of `srt_list`...
#> ℹ [2026-11-12 05:40:51] Data 5/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:40:51] Perform `FindVariableFeatures()` on 5/5 of `srt_list`...
#> ℹ [2026-11-12 05:40:51] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 05:40:51] Number of available HVF: 2000
#> ℹ [2026-11-12 05:40:51] Finished check
#> ℹ [2026-11-12 05:40:51] Perform Uncorrected integration
#> ℹ [2026-11-12 05:40:51] Perform `Seurat::ScaleData()`
#> ℹ [2026-11-12 05:40:51] Perform "pca" linear dimension reduction
#> ℹ [2026-11-12 05:40:52] Adjust neighbor k from 20 to 20 for small-sample clustering
#> ℹ [2026-11-12 05:40:53] Perform `Seurat::FindClusters()` with "louvain"
#> ℹ [2026-11-12 05:40:53] Reorder clusters...
#> ℹ [2026-11-12 05:40:53] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 05:40:53] Perform umap nonlinear dimension reduction using Uncorrectedpca (1:50)
#> ℹ [2026-11-12 05:40:59] Perform umap nonlinear dimension reduction using Uncorrectedpca (1:50)
#> ℹ [2026-11-12 05:41:06] Perform umap nonlinear dimension reduction using Uncorrectedpca (1:50)
#> ✔ [2026-11-12 05:41:13] Uncorrected integration completed
#> ◌ [2026-11-12 05:41:14] Run integration workflow...
#> ℹ [2026-11-12 05:41:14] Split `srt_merge` into `srt_list` by "tech"
#> ℹ [2026-11-12 05:41:15] Checking a list of <Seurat>...
#> ℹ [2026-11-12 05:41:15] Data 1/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:41:15] Perform `FindVariableFeatures()` on 1/5 of `srt_list`...
#> ℹ [2026-11-12 05:41:16] Data 2/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:41:16] Perform `FindVariableFeatures()` on 2/5 of `srt_list`...
#> ℹ [2026-11-12 05:41:16] Data 3/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:41:16] Perform `FindVariableFeatures()` on 3/5 of `srt_list`...
#> ℹ [2026-11-12 05:41:16] Data 4/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:41:16] Perform `FindVariableFeatures()` on 4/5 of `srt_list`...
#> ℹ [2026-11-12 05:41:16] Data 5/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:41:16] Perform `FindVariableFeatures()` on 5/5 of `srt_list`...
#> ℹ [2026-11-12 05:41:16] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 05:41:17] Number of available HVF: 2000
#> ℹ [2026-11-12 05:41:17] Finished check
#> ℹ [2026-11-12 05:41:17] Perform FindIntegrationAnchors
#> ℹ [2026-11-12 05:41:40] Perform Seurat integration
#> ℹ [2026-11-12 05:41:59] Perform ScaleData on `srt_integrated`
#> ℹ [2026-11-12 05:42:00] Perform "pca" linear dimension reduction
#> ℹ [2026-11-12 05:42:01] Perform `Seurat::FindClusters()` with "louvain"
#> ℹ [2026-11-12 05:42:01] Reorder clusters...
#> ℹ [2026-11-12 05:42:01] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 05:42:01] Perform umap nonlinear dimension reduction using Seuratpca (1:50)
#> ℹ [2026-11-12 05:42:08] Perform umap nonlinear dimension reduction using Seuratpca (1:50)
#> ℹ [2026-11-12 05:42:14] Perform umap nonlinear dimension reduction using Seuratpca (1:50)
#> ✔ [2026-11-12 05:42:25] Seurat integration completed
#> ◌ [2026-11-12 05:42:25] Run integration workflow...
#> Splitting ‘counts’, ‘data’ layers. Not splitting . If you would like to split other layers, set in `layers` argument.
#> ℹ [2026-11-12 05:42:26] Data appears already log-normalized. Skipping `Seurat::NormalizeData()`
#> ℹ [2026-11-12 05:42:26] Perform `Seurat::FindVariableFeatures()` per batch (`HVF_source = 'separate'`)
#> ℹ [2026-11-12 05:42:26] Number of available HVF: 2000
#> ℹ [2026-11-12 05:42:28] Perform `Seurat::ScaleData()` on split layers for Seurat v5 integration
#> ℹ [2026-11-12 05:42:28] Perform PCA on split layers before `Seurat::IntegrateLayers()`
#> ℹ [2026-11-12 05:42:29] Perform Seurat v5 integration with `CCAIntegration()`
#> ℹ [2026-11-12 05:42:36] Adjust neighbor k from 20 to 20 for small-sample clustering
#> ℹ [2026-11-12 05:42:36] Perform `Seurat::FindClusters()` with "louvain"
#> ℹ [2026-11-12 05:42:36] Reorder clusters...
#> ℹ [2026-11-12 05:42:36] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 05:42:36] Perform umap nonlinear dimension reduction using CCA (1:50)
#> ℹ [2026-11-12 05:42:43] Perform umap nonlinear dimension reduction using CCA (1:50)
#> ℹ [2026-11-12 05:42:50] Perform umap nonlinear dimension reduction using pca (1:50)
#> ✔ [2026-11-12 05:42:59] CCA integration completed
#> ◌ [2026-11-12 05:42:59] Run integration workflow...
#> Splitting ‘counts’, ‘data’ layers. Not splitting . If you would like to split other layers, set in `layers` argument.
#> ℹ [2026-11-12 05:43:00] Data appears already log-normalized. Skipping `Seurat::NormalizeData()`
#> ℹ [2026-11-12 05:43:00] Perform `Seurat::FindVariableFeatures()` per batch (`HVF_source = 'separate'`)
#> ℹ [2026-11-12 05:43:01] Number of available HVF: 2000
#> ℹ [2026-11-12 05:43:02] Perform `Seurat::ScaleData()` on split layers for Seurat v5 integration
#> ℹ [2026-11-12 05:43:02] Perform PCA on split layers before `Seurat::IntegrateLayers()`
#> ℹ [2026-11-12 05:43:03] Perform Seurat v5 integration with `RPCAIntegration()`
#> ℹ [2026-11-12 05:43:15] Adjust neighbor k from 20 to 20 for small-sample clustering
#> ℹ [2026-11-12 05:43:15] Perform `Seurat::FindClusters()` with "louvain"
#> ℹ [2026-11-12 05:43:15] Reorder clusters...
#> ℹ [2026-11-12 05:43:15] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 05:43:15] Perform umap nonlinear dimension reduction using RPCA (1:50)
#> ℹ [2026-11-12 05:43:22] Perform umap nonlinear dimension reduction using RPCA (1:50)
#> ℹ [2026-11-12 05:43:29] Perform umap nonlinear dimension reduction using pca (1:50)
#> ✔ [2026-11-12 05:43:38] RPCA integration completed
#> ◌ [2026-11-12 05:43:38] Run integration workflow...
#> ℹ [2026-11-12 05:43:40] Checking a list of <Seurat>...
#> ℹ [2026-11-12 05:43:40] Data 1/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:43:40] Perform `FindVariableFeatures()` on 1/5 of `srt_list`...
#> ℹ [2026-11-12 05:43:40] Data 2/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:43:40] Perform `FindVariableFeatures()` on 2/5 of `srt_list`...
#> ℹ [2026-11-12 05:43:40] Data 3/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:43:40] Perform `FindVariableFeatures()` on 3/5 of `srt_list`...
#> ℹ [2026-11-12 05:43:41] Data 4/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:43:41] Perform `FindVariableFeatures()` on 4/5 of `srt_list`...
#> ℹ [2026-11-12 05:43:41] Data 5/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:43:41] Perform `FindVariableFeatures()` on 5/5 of `srt_list`...
#> ℹ [2026-11-12 05:43:41] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 05:43:41] Number of available HVF: 2000
#> ℹ [2026-11-12 05:43:41] Finished check
#> ℹ [2026-11-12 05:43:42] Perform MNN integration
#> ℹ [2026-11-12 05:44:27] Perform ScaleData
#> ℹ [2026-11-12 05:44:27] Perform "pca" linear dimension reduction
#> ℹ [2026-11-12 05:44:28] Perform `Seurat::FindClusters()` with "louvain"
#> ℹ [2026-11-12 05:44:28] Reorder clusters...
#> ℹ [2026-11-12 05:44:28] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 05:44:28] Perform umap nonlinear dimension reduction using MNNpca (1:50)
#> ℹ [2026-11-12 05:44:36] Perform umap nonlinear dimension reduction using MNNpca (1:50)
#> ℹ [2026-11-12 05:44:43] Perform umap nonlinear dimension reduction using MNNpca (1:50)
#> ✔ [2026-11-12 05:44:53] MNN integration completed
#> ◌ [2026-11-12 05:44:53] Run integration workflow...
#> ℹ [2026-11-12 05:44:55] Checking a list of <Seurat>...
#> ℹ [2026-11-12 05:44:55] Data 1/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:44:55] Perform `FindVariableFeatures()` on 1/5 of `srt_list`...
#> ℹ [2026-11-12 05:44:55] Data 2/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:44:55] Perform `FindVariableFeatures()` on 2/5 of `srt_list`...
#> ℹ [2026-11-12 05:44:55] Data 3/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:44:55] Perform `FindVariableFeatures()` on 3/5 of `srt_list`...
#> ℹ [2026-11-12 05:44:56] Data 4/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:44:56] Perform `FindVariableFeatures()` on 4/5 of `srt_list`...
#> ℹ [2026-11-12 05:44:56] Data 5/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:44:56] Perform `FindVariableFeatures()` on 5/5 of `srt_list`...
#> ℹ [2026-11-12 05:44:56] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 05:44:56] Number of available HVF: 2000
#> ℹ [2026-11-12 05:44:56] Finished check
#> ℹ [2026-11-12 05:44:56] Perform fastMNN integration
#> ℹ [2026-11-12 05:45:00] Perform `Seurat::FindClusters()` with "louvain"
#> ℹ [2026-11-12 05:45:01] Reorder clusters...
#> ℹ [2026-11-12 05:45:01] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 05:45:01] Perform umap nonlinear dimension reduction using fastMNN (1:50)
#> ℹ [2026-11-12 05:45:08] Perform umap nonlinear dimension reduction using fastMNN (1:50)
#> ℹ [2026-11-12 05:45:15] Perform umap nonlinear dimension reduction using fastMNN (1:50)
#> ✔ [2026-11-12 05:45:24] fastMNN integration completed
#> ◌ [2026-11-12 05:45:24] Run integration workflow...
#> ℹ [2026-11-12 05:45:26] Split `srt_merge` into `srt_list` by "tech"
#> ℹ [2026-11-12 05:45:27] Checking a list of <Seurat>...
#> ℹ [2026-11-12 05:45:28] Data 1/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:45:28] Perform `FindVariableFeatures()` on 1/5 of `srt_list`...
#> ℹ [2026-11-12 05:45:28] Data 2/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:45:28] Perform `FindVariableFeatures()` on 2/5 of `srt_list`...
#> ℹ [2026-11-12 05:45:28] Data 3/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:45:28] Perform `FindVariableFeatures()` on 3/5 of `srt_list`...
#> ℹ [2026-11-12 05:45:28] Data 4/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:45:28] Perform `FindVariableFeatures()` on 4/5 of `srt_list`...
#> ℹ [2026-11-12 05:45:28] Data 5/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:45:28] Perform `FindVariableFeatures()` on 5/5 of `srt_list`...
#> ℹ [2026-11-12 05:45:29] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 05:45:29] Number of available HVF: 2000
#> ℹ [2026-11-12 05:45:29] Finished check
#> ℹ [2026-11-12 05:45:29] Perform `Seurat::ScaleData()`
#> ℹ [2026-11-12 05:45:29] Perform linear dimension reduction("pca")
#> ℹ [2026-11-12 05:45:30] Perform Harmony integration
#> ℹ [2026-11-12 05:45:30] Using "Harmonypca" (1:50) as input
#> ℹ [2026-11-12 05:45:30] Adjust neighbor k from 20 to 20 for small-sample clustering
#> ℹ [2026-11-12 05:45:31] Perform `Seurat::FindClusters()` with "louvain"
#> ℹ [2026-11-12 05:45:31] Reorder clusters...
#> ℹ [2026-11-12 05:45:31] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 05:45:31] Perform umap nonlinear dimension reduction using Harmony (1:50)
#> ℹ [2026-11-12 05:45:38] Perform umap nonlinear dimension reduction using Harmony (1:50)
#> ℹ [2026-11-12 05:45:45] Perform umap nonlinear dimension reduction using Harmonypca (1:50)
#> ✔ [2026-11-12 05:45:54] Harmony integration completed
#> ◌ [2026-11-12 05:45:54] Run integration workflow...
#> Splitting ‘counts’, ‘data’ layers. Not splitting . If you would like to split other layers, set in `layers` argument.
#> ℹ [2026-11-12 05:45:56] Data appears already log-normalized. Skipping `Seurat::NormalizeData()`
#> ℹ [2026-11-12 05:45:56] Perform `Seurat::FindVariableFeatures()` per batch (`HVF_source = 'separate'`)
#> ℹ [2026-11-12 05:45:57] Number of available HVF: 2000
#> ℹ [2026-11-12 05:45:58] Perform `Seurat::ScaleData()` on split layers for Seurat v5 integration
#> ℹ [2026-11-12 05:45:58] Perform PCA on split layers before `Seurat::IntegrateLayers()`
#> ℹ [2026-11-12 05:45:59] Perform Seurat v5 integration with `HarmonyIntegration()`
#> The `features` argument is ignored by `HarmonyIntegration`.
#> This message is displayed once per session.
#> ℹ [2026-11-12 05:46:00] Adjust neighbor k from 20 to 20 for small-sample clustering
#> ℹ [2026-11-12 05:46:01] Perform `Seurat::FindClusters()` with "louvain"
#> ℹ [2026-11-12 05:46:01] Reorder clusters...
#> ℹ [2026-11-12 05:46:01] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 05:46:01] Perform umap nonlinear dimension reduction using Harmony5 (1:50)
#> ℹ [2026-11-12 05:46:08] Perform umap nonlinear dimension reduction using Harmony5 (1:50)
#> ℹ [2026-11-12 05:46:15] Perform umap nonlinear dimension reduction using pca (1:50)
#> ✔ [2026-11-12 05:46:24] Harmony5 integration completed
#> ◌ [2026-11-12 05:46:24] Run integration workflow...
#> ℹ [2026-11-12 05:46:26] Split `srt_merge` into `srt_list` by "tech"
#> ℹ [2026-11-12 05:46:27] Checking a list of <Seurat>...
#> ℹ [2026-11-12 05:46:27] Data 1/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:46:27] Perform `FindVariableFeatures()` on 1/5 of `srt_list`...
#> ℹ [2026-11-12 05:46:28] Data 2/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:46:28] Perform `FindVariableFeatures()` on 2/5 of `srt_list`...
#> ℹ [2026-11-12 05:46:28] Data 3/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:46:28] Perform `FindVariableFeatures()` on 3/5 of `srt_list`...
#> ℹ [2026-11-12 05:46:28] Data 4/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:46:28] Perform `FindVariableFeatures()` on 4/5 of `srt_list`...
#> ℹ [2026-11-12 05:46:28] Data 5/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:46:28] Perform `FindVariableFeatures()` on 5/5 of `srt_list`...
#> ℹ [2026-11-12 05:46:28] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 05:46:29] Number of available HVF: 2000
#> ℹ [2026-11-12 05:46:29] Finished check
#> ℹ [2026-11-12 05:46:29] Perform Coralysis integration
#> Data in `logcounts` slot already of `dgCMatrix` class...
#> 2000/2000 features remain after filtering features with only zero values.
#>
#> Building training set...
#> No. of cells is lower or equal than the no. of 'nclusters': 200 <= 500
#> All the cells will be included and the clustering step will be skipped!
#> Found more than one class "kcca" in cache; using the first, from namespace 'kernlab'
#> Also defined by ‘flexclust’
#> Found more than one class "kcca" in cache; using the first, from namespace 'kernlab'
#> Also defined by ‘flexclust’
#> No. of cells is lower or equal than the no. of 'nclusters': 200 <= 500
#> All the cells will be included and the clustering step will be skipped!
#> No. of cells is lower or equal than the no. of 'nclusters': 200 <= 500
#> All the cells will be included and the clustering step will be skipped!
#> No. of cells is lower or equal than the no. of 'nclusters': 200 <= 500
#> All the cells will be included and the clustering step will be skipped!
#> Training set successfully built.
#>
#> Computing cluster seed.
#>
#> Initializing divisive ICP clustering...
#>
|
| | 0%
|
|======= | 10%
|
|============== | 20%
|
|===================== | 30%
|
|============================ | 40%
|
|=================================== | 50%
|
|========================================== | 60%
|
|================================================= | 70%
|
|======================================================== | 80%
|
|=============================================================== | 90%
|
|======================================================================| 100%
#>
#>
#> Divisive ICP clustering completed successfully.
#>
#> Predicting cell cluster probabilities using ICP models...
#> Prediction of cell cluster probabilities completed successfully.
#>
#> Multi-level integration completed successfully.
#> Divisive ICP: selecting ICP tables multiple of 4
#> ℹ [2026-11-12 05:47:58] Adjust neighbor k from 20 to 20 for small-sample clustering
#> ℹ [2026-11-12 05:47:58] Perform `Seurat::FindClusters()` with "louvain"
#> ℹ [2026-11-12 05:47:58] Reorder clusters...
#> ℹ [2026-11-12 05:47:58] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 05:47:58] Perform umap nonlinear dimension reduction using Coralysis (1:50)
#> ℹ [2026-11-12 05:48:05] Perform umap nonlinear dimension reduction using Coralysis (1:50)
#> ℹ [2026-11-12 05:48:13] Perform umap nonlinear dimension reduction using Coralysis (1:50)
#> ✔ [2026-11-12 05:48:22] Coralysis integration completed
#> ◌ [2026-11-12 05:48:23] Run integration workflow...
#> ℹ [2026-11-12 05:48:24] Split `srt_merge` into `srt_list` by "tech"
#> ℹ [2026-11-12 05:48:26] Checking a list of <Seurat>...
#> ℹ [2026-11-12 05:48:26] Data 1/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:48:26] Perform `FindVariableFeatures()` on 1/5 of `srt_list`...
#> ℹ [2026-11-12 05:48:26] Data 2/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:48:26] Perform `FindVariableFeatures()` on 2/5 of `srt_list`...
#> ℹ [2026-11-12 05:48:26] Data 3/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:48:26] Perform `FindVariableFeatures()` on 3/5 of `srt_list`...
#> ℹ [2026-11-12 05:48:26] Data 4/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:48:27] Perform `FindVariableFeatures()` on 4/5 of `srt_list`...
#> ℹ [2026-11-12 05:48:27] Data 5/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:48:27] Perform `FindVariableFeatures()` on 5/5 of `srt_list`...
#> ℹ [2026-11-12 05:48:27] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 05:48:27] Number of available HVF: 2000
#> ℹ [2026-11-12 05:48:27] Finished check
#> ℹ [2026-11-12 05:48:27] Prepare rliger layer "ligerScaleData" ...
#> ℹ [2026-11-12 05:48:27] Perform LIGER integration
#> ℹ [2026-11-12 05:48:33] Adjust neighbor k from 20 to 20 for small-sample clustering
#> ℹ [2026-11-12 05:48:33] Perform `Seurat::FindClusters()` with "louvain"
#> ℹ [2026-11-12 05:48:33] Reorder clusters...
#> ℹ [2026-11-12 05:48:34] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 05:48:34] Perform umap nonlinear dimension reduction using LIGER (1:20)
#> ℹ [2026-11-12 05:48:41] Perform umap nonlinear dimension reduction using LIGER (1:20)
#> ℹ [2026-11-12 05:48:49] Perform umap nonlinear dimension reduction using LIGER (1:50)
#> ✔ [2026-11-12 05:48:58] LIGER integration completed
#> ◌ [2026-11-12 05:48:58] Run integration workflow...
#> ℹ [2026-11-12 05:49:00] Split `srt_merge` into `srt_list` by "tech"
#> ℹ [2026-11-12 05:49:01] Checking a list of <Seurat>...
#> ℹ [2026-11-12 05:49:01] Data 1/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:49:01] Perform `FindVariableFeatures()` on 1/5 of `srt_list`...
#> ℹ [2026-11-12 05:49:02] Data 2/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:49:02] Perform `FindVariableFeatures()` on 2/5 of `srt_list`...
#> ℹ [2026-11-12 05:49:02] Data 3/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:49:02] Perform `FindVariableFeatures()` on 3/5 of `srt_list`...
#> ℹ [2026-11-12 05:49:02] Data 4/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:49:02] Perform `FindVariableFeatures()` on 4/5 of `srt_list`...
#> ℹ [2026-11-12 05:49:02] Data 5/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:49:02] Perform `FindVariableFeatures()` on 5/5 of `srt_list`...
#> ℹ [2026-11-12 05:49:03] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 05:49:03] Number of available HVF: 2000
#> ℹ [2026-11-12 05:49:03] Finished check
#> ℹ [2026-11-12 05:49:03] Perform ScaleData on the data 1 ...
#> ℹ [2026-11-12 05:49:03] Perform "pca" linear dimension reduction
#> ℹ [2026-11-12 05:49:03] Perform ScaleData on the data 2 ...
#> ℹ [2026-11-12 05:49:03] Perform "pca" linear dimension reduction
#> ℹ [2026-11-12 05:49:03] Perform ScaleData on the data 3 ...
#> ℹ [2026-11-12 05:49:03] Perform "pca" linear dimension reduction
#> ℹ [2026-11-12 05:49:04] Perform ScaleData on the data 4 ...
#> ℹ [2026-11-12 05:49:04] Perform "pca" linear dimension reduction
#> ℹ [2026-11-12 05:49:04] Perform ScaleData on the data 5 ...
#> ℹ [2026-11-12 05:49:04] Perform "pca" linear dimension reduction
#> ℹ [2026-11-12 05:49:05] Perform Conos integration
#> ℹ [2026-11-12 05:49:05] Conos integration using pca (1:50) as input
#> ℹ [2026-11-12 05:49:10] Adjust neighbor k from 20 to 20 for small-sample clustering
#> ℹ [2026-11-12 05:49:10] Perform `Seurat::FindClusters()` with "louvain"
#> ℹ [2026-11-12 05:49:10] Reorder clusters...
#> ℹ [2026-11-12 05:49:10] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 05:49:10] Perform umap nonlinear dimension reduction using Conos
#> ℹ [2026-11-12 05:49:18] Perform umap nonlinear dimension reduction using Conos
#> ℹ [2026-11-12 05:49:25] Perform umap nonlinear dimension reduction using ConosUMAP2D (1:50)
#> ✔ [2026-11-12 05:49:35] Conos integration completed
#> ◌ [2026-11-12 05:49:35] Run integration workflow...
#> ℹ [2026-11-12 05:49:37] Split `srt_merge` into `srt_list` by "tech"
#> ℹ [2026-11-12 05:49:38] Checking a list of <Seurat>...
#> ℹ [2026-11-12 05:49:39] Data 1/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:49:39] Perform `FindVariableFeatures()` on 1/5 of `srt_list`...
#> ℹ [2026-11-12 05:49:39] Data 2/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:49:39] Perform `FindVariableFeatures()` on 2/5 of `srt_list`...
#> ℹ [2026-11-12 05:49:39] Data 3/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:49:39] Perform `FindVariableFeatures()` on 3/5 of `srt_list`...
#> ℹ [2026-11-12 05:49:39] Data 4/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:49:39] Perform `FindVariableFeatures()` on 4/5 of `srt_list`...
#> ℹ [2026-11-12 05:49:40] Data 5/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:49:40] Perform `FindVariableFeatures()` on 5/5 of `srt_list`...
#> ℹ [2026-11-12 05:49:40] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 05:49:40] Number of available HVF: 2000
#> ℹ [2026-11-12 05:49:40] Finished check
#> ℹ [2026-11-12 05:49:40] Perform ComBat integration
#> Found 138 genes with uniform expression within a single batch (all zeros); these will not be adjusted for batch.
#> ℹ [2026-11-12 05:49:41] Perform `Seurat::ScaleData()`
#> ℹ [2026-11-12 05:49:41] Perform linear dimension reduction ("pca")
#> ℹ [2026-11-12 05:49:42] Perform `Seurat::FindClusters()` with "louvain"
#> ℹ [2026-11-12 05:49:42] Reorder clusters...
#> ℹ [2026-11-12 05:49:42] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 05:49:42] Perform umap nonlinear dimension reduction using ComBatpca (1:50)
#> ℹ [2026-11-12 05:49:50] Perform umap nonlinear dimension reduction using ComBatpca (1:50)
#> ℹ [2026-11-12 05:49:57] Perform umap nonlinear dimension reduction using ComBatpca (1:50)
#> ✔ [2026-11-12 05:50:07] ComBat integration completed
# Python-backed methods prepare a scVI/scvi-tools environment and run model
# training, so keep them separate from ordinary example checks.
if (FALSE) { # \dontrun{
panc8_sub <- RunIntegration(
panc8_sub,
batch = "tech",
integration_methods = "scVI",
train_params = list(max_epochs = 2L),
nonlinear_reduction = "umap"
)
panc8_sub <- RunIntegration(
panc8_sub,
batch = "tech",
integration_methods = "scVI5",
IntegrateLayers_params = list(max_epochs = 2L),
nonlinear_reduction = "umap"
)
} # }
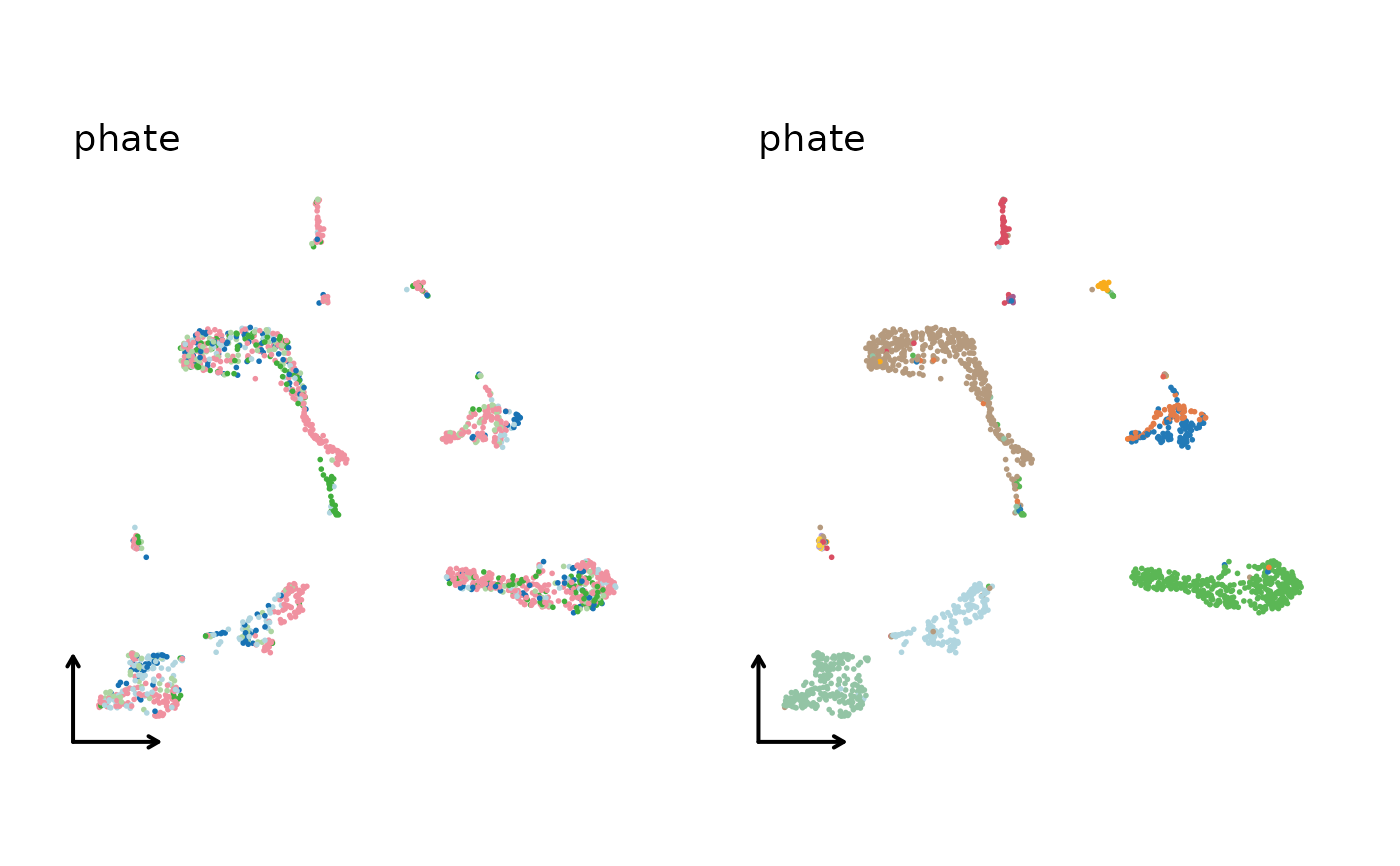
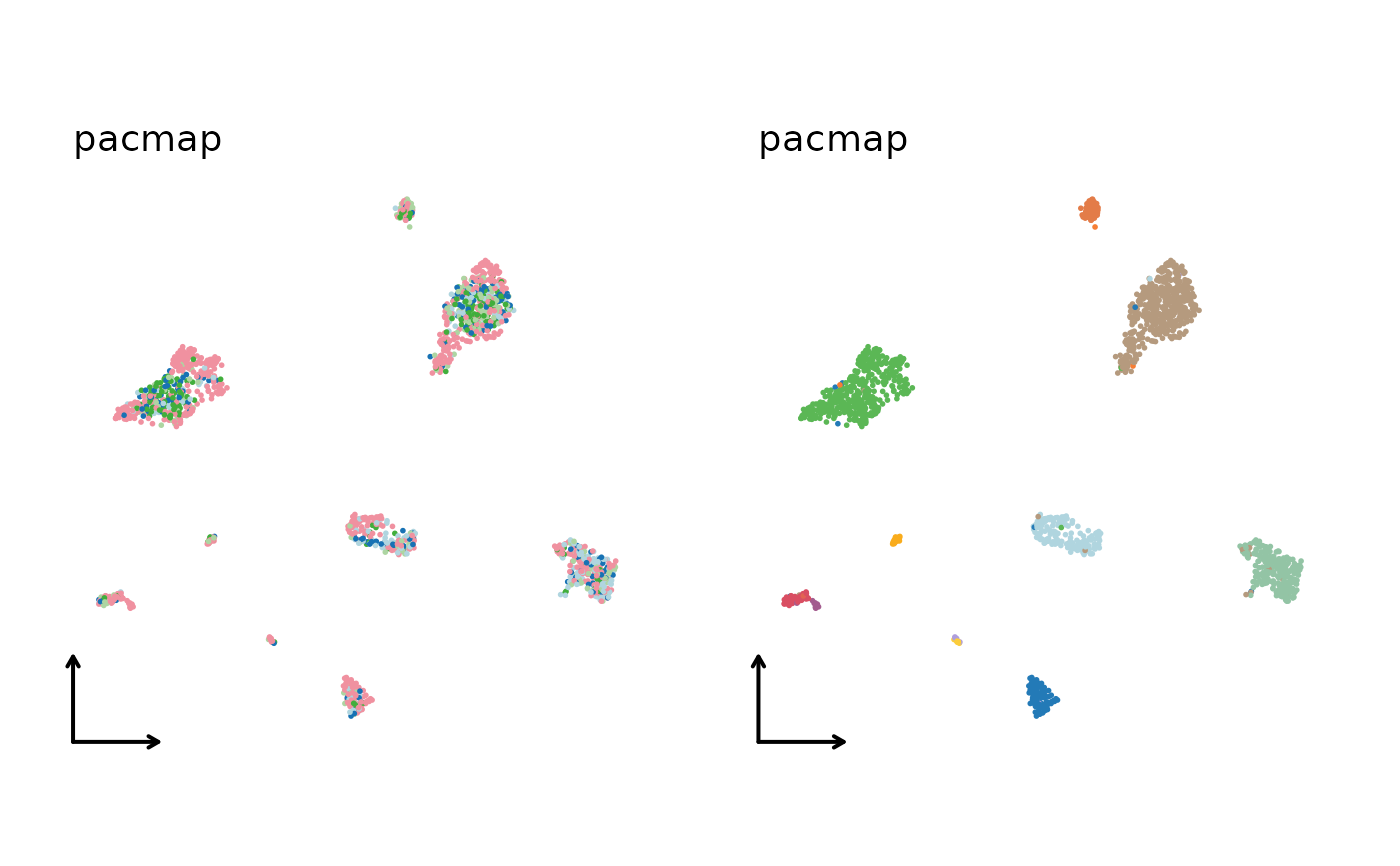
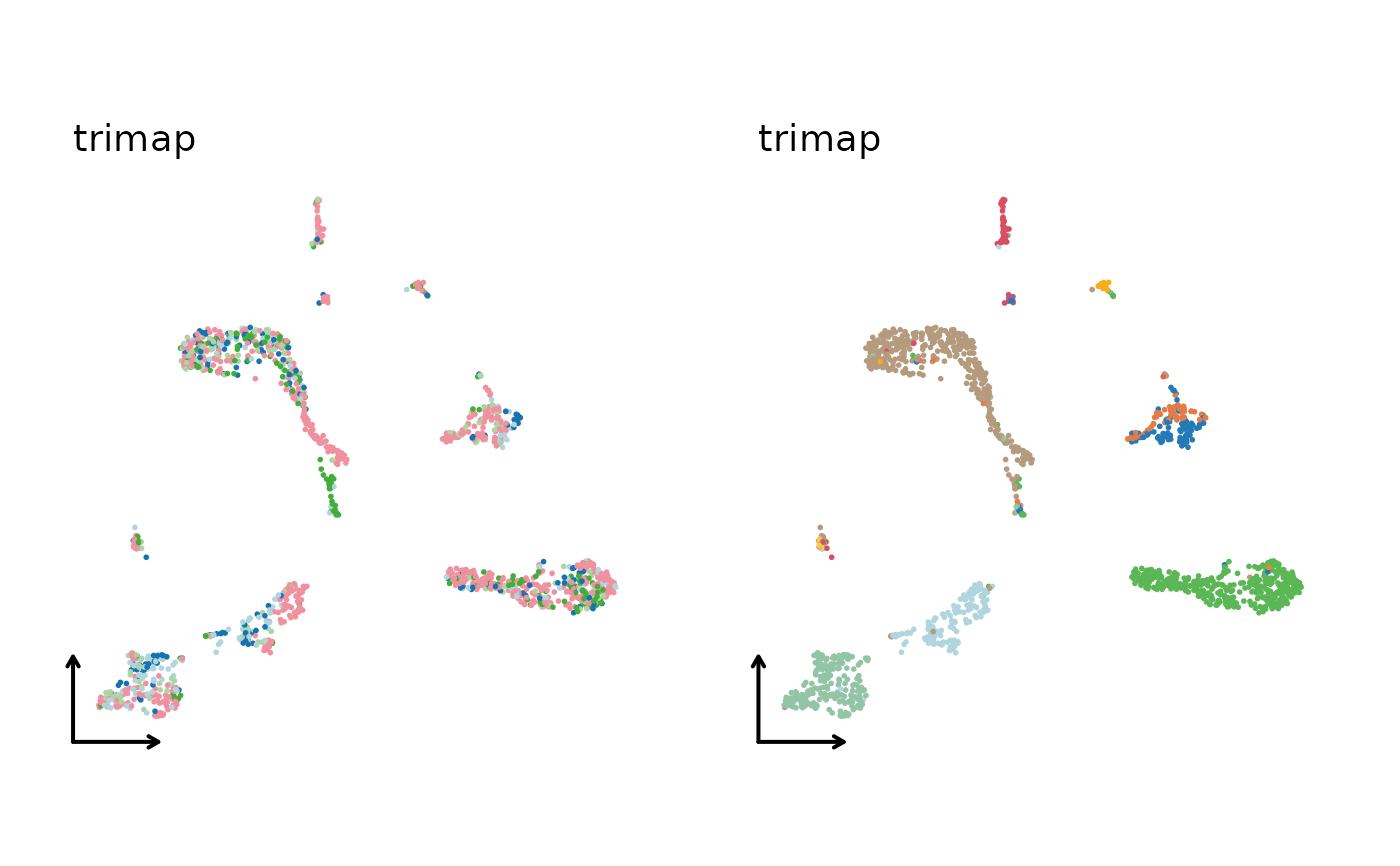
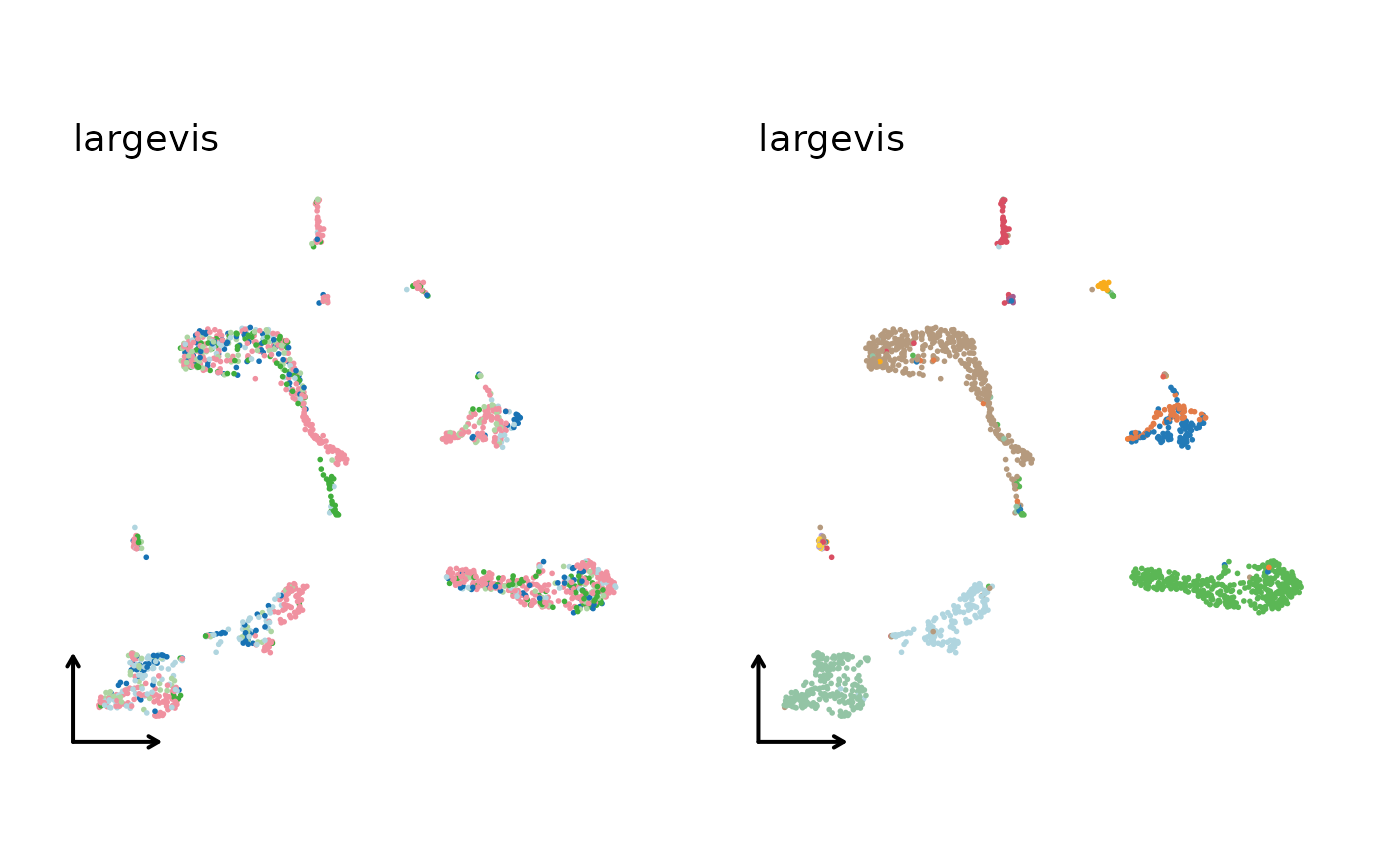
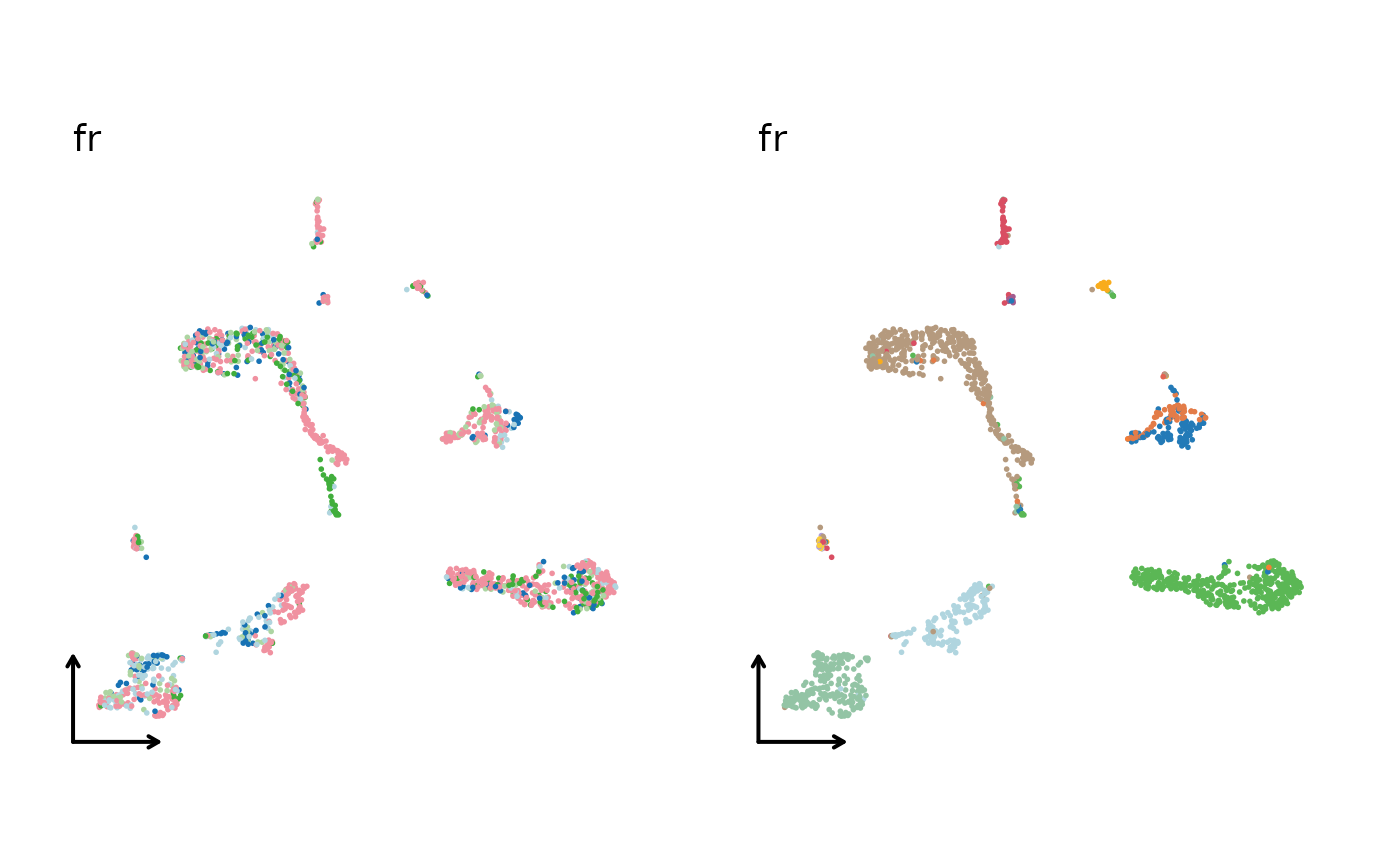
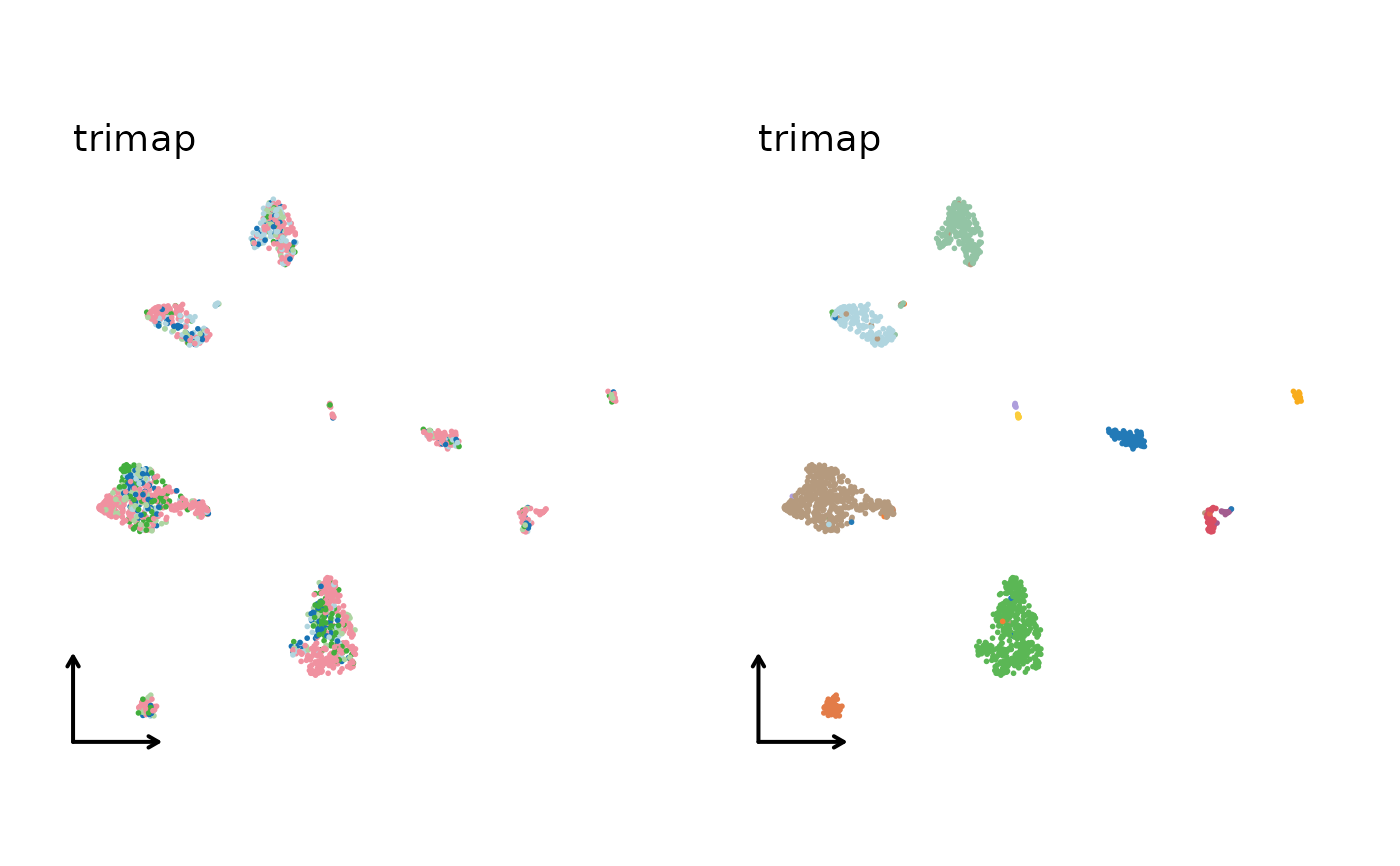
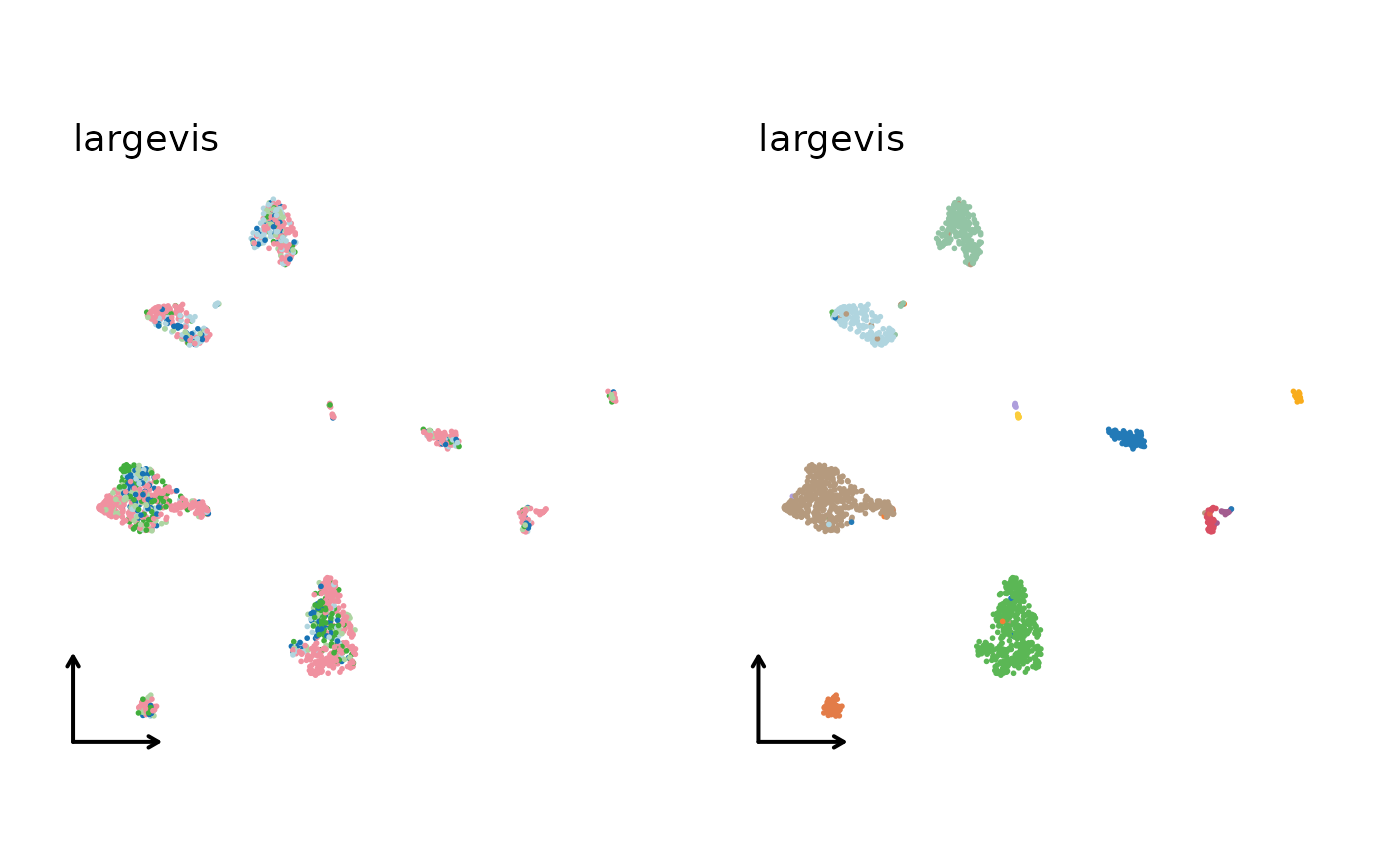
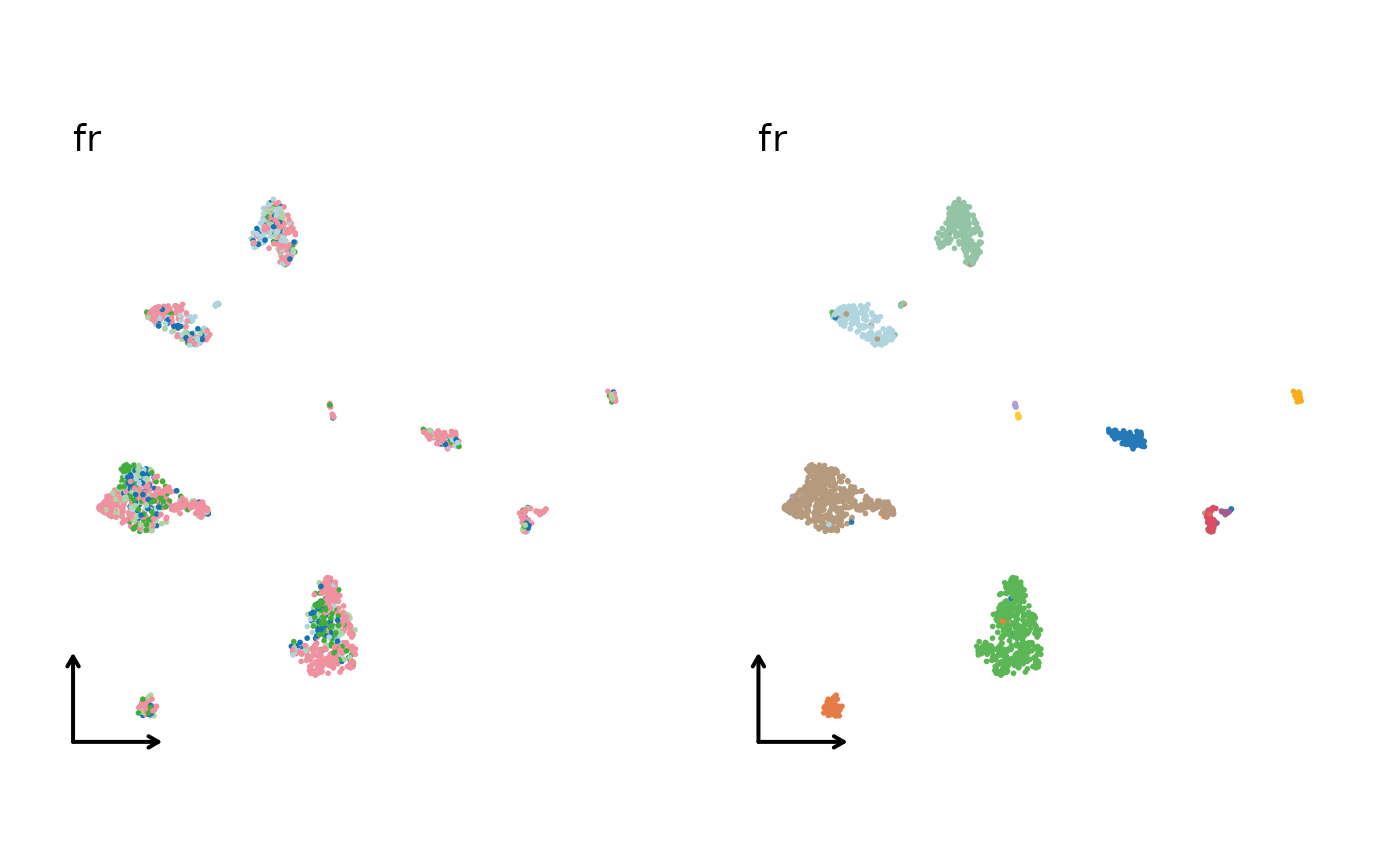
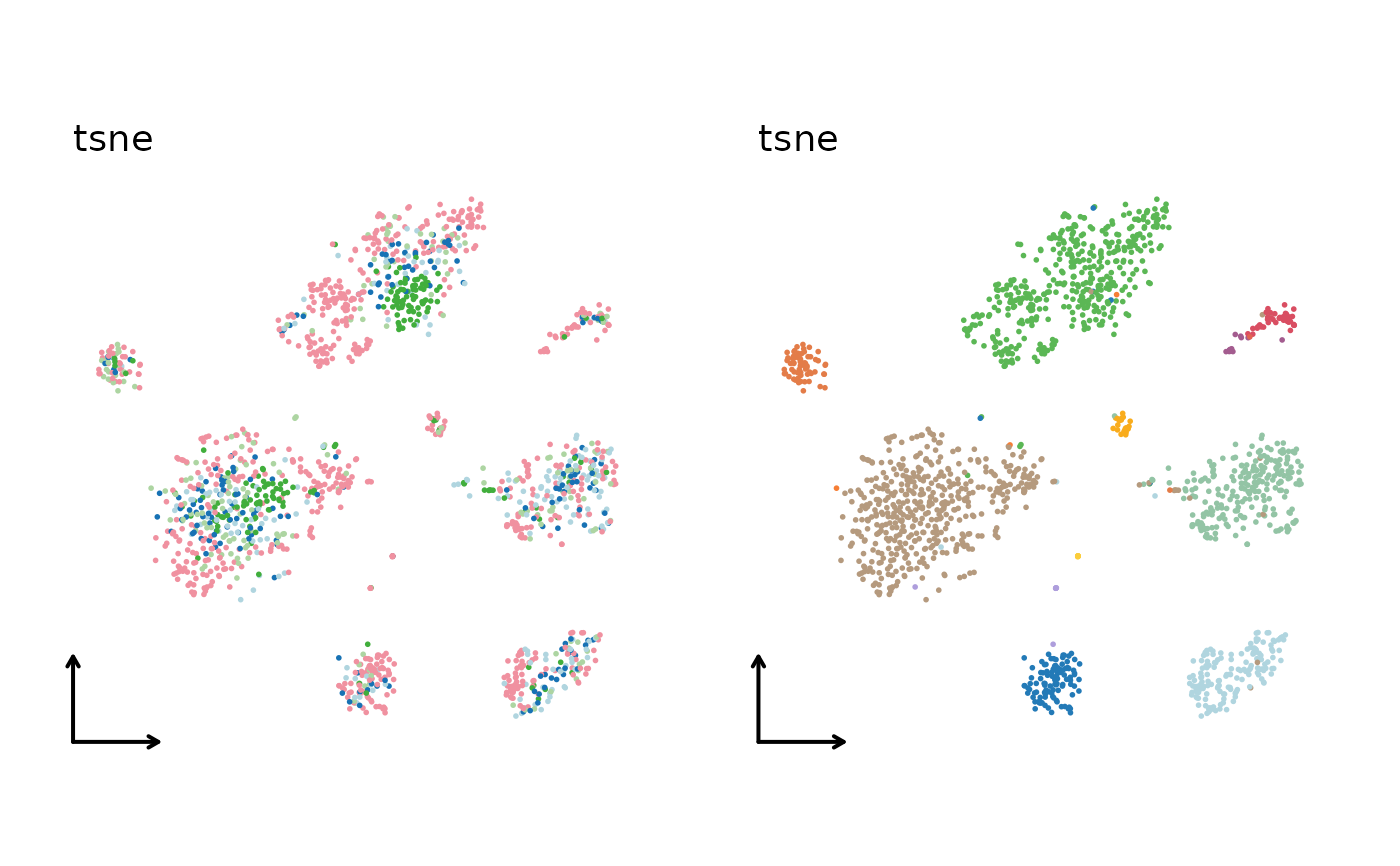
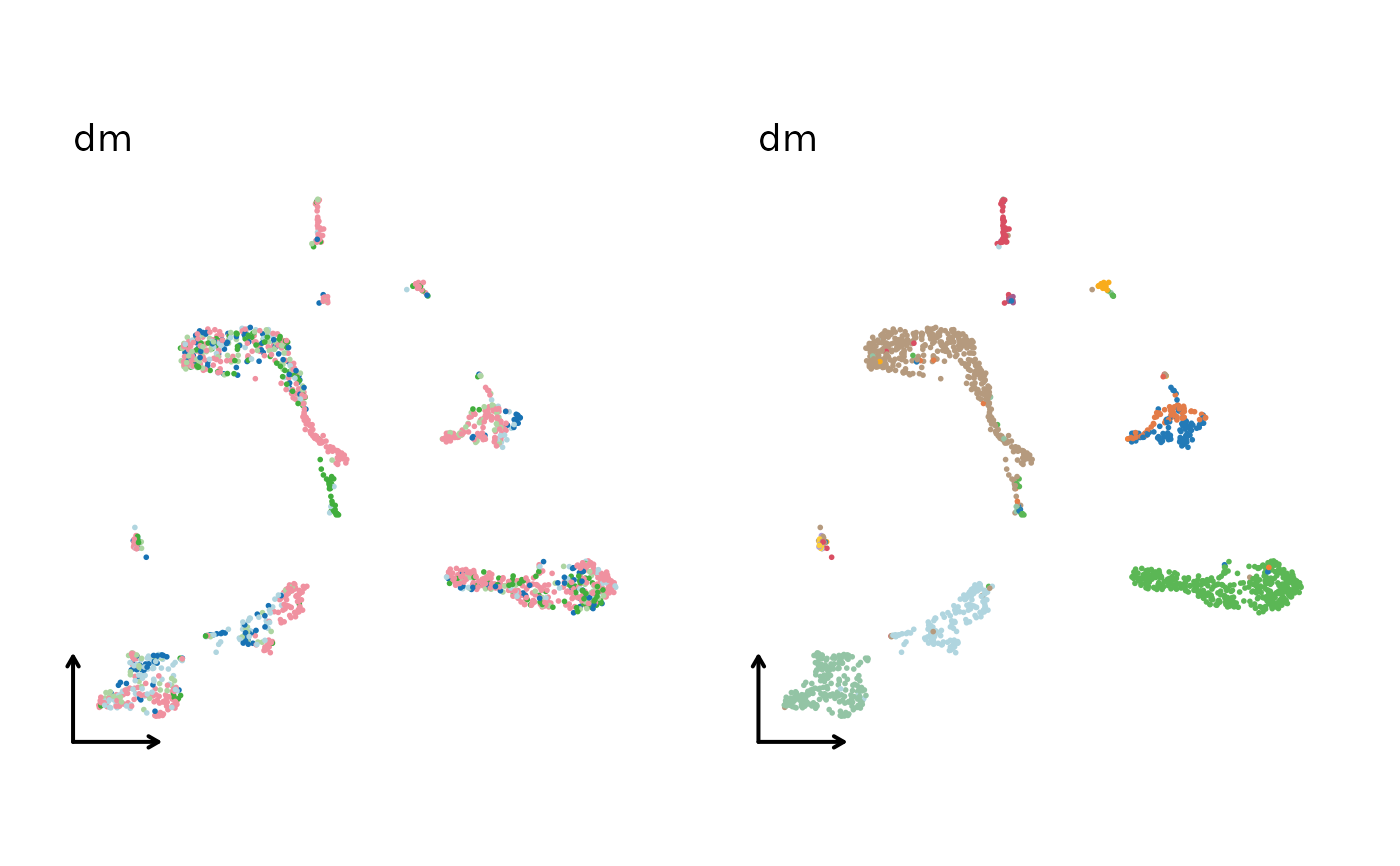
nonlinear_reductions <- c(
"umap", "tsne", "dm", "phate",
"pacmap", "trimap", "largevis", "fr"
)
panc8_sub <- RunIntegration(
panc8_sub,
batch = "tech",
integration_methods = "Seurat",
linear_reduction_dims_use = 1:50,
nonlinear_reduction = nonlinear_reductions,
nonlinear_reduction_params = list(largevis = list(n_epochs = 1000L))
)
#> ◌ [2026-11-12 05:50:07] Run integration workflow...
#> ℹ [2026-11-12 05:50:10] Split `srt_merge` into `srt_list` by "tech"
#> ℹ [2026-11-12 05:50:11] Checking a list of <Seurat>...
#> ℹ [2026-11-12 05:50:11] Data 1/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:50:11] Perform `FindVariableFeatures()` on 1/5 of `srt_list`...
#> ℹ [2026-11-12 05:50:11] Data 2/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:50:11] Perform `FindVariableFeatures()` on 2/5 of `srt_list`...
#> ℹ [2026-11-12 05:50:11] Data 3/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:50:11] Perform `FindVariableFeatures()` on 3/5 of `srt_list`...
#> ℹ [2026-11-12 05:50:11] Data 4/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:50:12] Perform `FindVariableFeatures()` on 4/5 of `srt_list`...
#> ℹ [2026-11-12 05:50:12] Data 5/5 of the `srt_list` has been log-normalized
#> ℹ [2026-11-12 05:50:12] Perform `FindVariableFeatures()` on 5/5 of `srt_list`...
#> ℹ [2026-11-12 05:50:12] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 05:50:12] Number of available HVF: 2000
#> ℹ [2026-11-12 05:50:12] Finished check
#> ℹ [2026-11-12 05:50:12] Perform FindIntegrationAnchors
#> ℹ [2026-11-12 05:50:50] Perform Seurat integration
#> ℹ [2026-11-12 05:51:44] Perform ScaleData on `srt_integrated`
#> ℹ [2026-11-12 05:51:44] Perform "pca" linear dimension reduction
#> ℹ [2026-11-12 05:51:45] Perform `Seurat::FindClusters()` with "louvain"
#> ℹ [2026-11-12 05:51:46] Reorder clusters...
#> ℹ [2026-11-12 05:51:46] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 05:51:46] Perform umap nonlinear dimension reduction using Seuratpca (1:50)
#> ℹ [2026-11-12 05:51:53] Perform umap nonlinear dimension reduction using Seuratpca (1:50)
#> ℹ [2026-11-12 05:52:00] Perform tsne nonlinear dimension reduction using Seuratpca (1:50)
#> ℹ [2026-11-12 05:52:04] Perform tsne nonlinear dimension reduction using Seuratpca (1:50)
#> ℹ [2026-11-12 05:52:10] Perform dm nonlinear dimension reduction using Seuratpca (1:50)
#> ℹ [2026-11-12 05:53:45] Perform dm nonlinear dimension reduction using Seuratpca (1:50)
#> ℹ [2026-11-12 05:53:47] Perform phate nonlinear dimension reduction using Seuratpca (1:50)
#> ◌ [2026-11-12 05:53:50] Preparing python environment...
#> ℹ [2026-11-12 05:53:50] Environment name: 'scprep_env' and python version: 3.10-1
#> ℹ [2026-11-12 05:53:50] Auto-detecting conda-compatible environment manager...
#> ℹ [2026-11-12 05:53:50] Using micromamba executable: '/home/runner/.cache/R/scop/micromamba/linux-64/bin/micromamba'
#> ℹ [2026-11-12 05:53:50] Creating Python environment with python "3.10-1" using micromamba...
#> ℹ [2026-11-12 05:53:50] Skipping conda Terms of Service acceptance for micromamba.
#> + /home/runner/.cache/R/scop/micromamba/linux-64/bin/micromamba 'create' '--yes' '--name' 'scprep_env' 'python=3.10-1' 'pip' 'setuptools<81' 'wheel' '--quiet' '-c' 'conda-forge'
#> ✔ [2026-11-12 05:53:53] Environment created successfully: '/home/runner/work/_temp/pkgdown-python/envs/scprep_env'
#> ℹ [2026-11-12 05:53:53] 13 requirements to check, 3 conda requirements and 10 pip requirements
#> ℹ [2026-11-12 05:53:53] Checking 3 conda requirements
#> ℹ [2026-11-12 05:53:53] Installing 3 packages into environment: 'scprep_env' using micromamba
#> ℹ [2026-11-12 05:53:54] Installing packages via micromamba...
#> ℹ [2026-11-12 05:53:54] Using channel: "conda-forge"
#> ℹ [2026-11-12 05:53:54] Installing 3 packages...
#> + /home/runner/.cache/R/scop/micromamba/linux-64/bin/micromamba 'install' '--yes' '--name' 'scprep_env' '-c' 'conda-forge' 'leidenalg=0.10.2' 'tbb=2022.2.0' 'python-igraph=0.11.9'
#> Using Cached Shard Index for conda-forge/linux-64 ✔ Done
#> Using Cached Shard Index for conda-forge/noarch ✔ Done
#> Fetching and Parsing Packages' Shards ⧖ Starting
#> Fetching and Parsing Packages' Shards ✔ Done (0.2 sec)
#>
#> Pinned packages:
#>
#> - python=3.10
#>
#> Resolving Environment ⧖ Starting
#> Resolving Environment ✔ Done (0.4 sec)
#>
#> Transaction
#>
#> Prefix: /home/runner/work/_temp/pkgdown-python/envs/scprep_env
#>
#> Updating specs:
#>
#> - leidenalg=0.10.2
#> - tbb=2022.2.0
#> - python-igraph=0.11.9
#>
#>
#> Package Version Build Channel Size
#> ────────────────────────────────────────────────────────────────────────────
#> Install:
#> ────────────────────────────────────────────────────────────────────────────
#>
#> + arpack 3.9.1 nompi_hf03ea27_102 conda-forge Cached
#> + glpk 5.0 h445213a_0 conda-forge Cached
#> + gmp 6.3.0 hfd2156b_3 conda-forge Cached
#> + igraph 0.10.16 hfe3e89f_1 conda-forge Cached
#> + leidenalg 0.10.2 py310hea6c23e_1 conda-forge Cached
#> + libblas 3.11.0 12_h4a7cf45_openblas conda-forge Cached
#> + libgfortran 16.2.0 h69a702a_7 conda-forge Cached
#> + libgfortran5 16.2.0 h6b99dfc_7 conda-forge Cached
#> + libhwloc 2.12.1 default_hafda6a7_1003 conda-forge Cached
#> + libiconv 1.18 h0cb94f2_3 conda-forge Cached
#> + liblapack 3.11.0 12_h47877c9_openblas conda-forge Cached
#> + libleidenalg 0.11.1 h00ab1b0_0 conda-forge Cached
#> + libopenblas 0.3.34 pthreads_hf13c14d_2 conda-forge Cached
#> + libstdcxx 16.2.0 h934c35e_7 conda-forge Cached
#> + libstdcxx-ng 16.2.0 hdf11a46_7 conda-forge Cached
#> + libxml2 2.15.4 ha7a5771_1 conda-forge Cached
#> + libxml2-16 2.15.4 hbdfff7e_1 conda-forge Cached
#> + libxml2-devel 2.15.4 ha7a5771_1 conda-forge Cached
#> + python-igraph 0.11.9 py310hea6c23e_3 conda-forge Cached
#> + python_abi 3.10 9_cp310 conda-forge Cached
#> + tbb 2022.2.0 hb60516a_1 conda-forge Cached
#> + texttable 1.7.0 pyhd8ed1ab_1 conda-forge Cached
#>
#> Summary:
#>
#> Install: 22 packages
#>
#> Total download: 0 B
#>
#> ─────────────────────────────────────────────────warning libmamba Security Warning: This transaction includes executing package scripts (pre/post-link/unlink) if present. These scripts can contain arbitrary code. Please ensure you trust the package sources.
#> ───────────────────────────
#>
#>
#>
#> Transaction starting
#> Linking libstdcxx-16.2.0-h934c35e_7
#> Linking libiconv-1.18-h0cb94f2_3
#> Linking libgfortran5-16.2.0-h6b99dfc_7
#> Linking gmp-6.3.0-hfd2156b_3
#> Linking libstdcxx-ng-16.2.0-hdf11a46_7
#> Linking libxml2-16-2.15.4-hbdfff7e_1
#> Linking libgfortran-16.2.0-h69a702a_7
#> Linking glpk-5.0-h445213a_0
#> Linking libxml2-2.15.4-ha7a5771_1
#> Linking libopenblas-0.3.34-pthreads_hf13c14d_2
#> Linking libhwloc-2.12.1-default_hafda6a7_1003
#> Linking libxml2-devel-2.15.4-ha7a5771_1
#> Linking libblas-3.11.0-12_h4a7cf45_openblas
#> Linking tbb-2022.2.0-hb60516a_1
#> Linking liblapack-3.11.0-12_h47877c9_openblas
#> Linking arpack-3.9.1-nompi_hf03ea27_102
#> Linking igraph-0.10.16-hfe3e89f_1
#> Linking libleidenalg-0.11.1-h00ab1b0_0
#> Linking python_abi-3.10-9_cp310
#> Linking texttable-1.7.0-pyhd8ed1ab_1
#> Linking python-igraph-0.11.9-py310hea6c23e_3
#> Linking leidenalg-0.10.2-py310hea6c23e_1
#>
#> Transaction finished
#>
#> ✔ [2026-11-12 05:53:55] micromamba installation completed successfully
#> ℹ [2026-11-12 05:53:56] Checking 12 requirements using uv
#> ℹ [2026-11-12 05:53:56] Installing 12 packages into environment: 'scprep_env' using micromamba
#> ℹ [2026-11-12 05:53:56] Installing packages via uv...
#> + /home/runner/work/_temp/pkgdown-python/envs/scop_env/bin/uv 'pip' 'install' '--python' '/home/runner/work/_temp/pkgdown-python/envs/scprep_env/bin/python3.10' '--force-reinstall' 'setuptools<81' 'matplotlib==3.10.8' 'numba==0.66.0' 'llvmlite==0.48.0' 'numpy==1.26.4' 'packaging>=24.0' 'pandas==2.0.3' 'scikit-learn==1.7.0' 'scipy==1.15.3' 'phate==1.0.11' 'leidenalg==0.10.2' 'igraph==0.11.9'
#> Using Python 3.10.1 environment at: /home/runner/work/_temp/pkgdown-python/envs/scprep_env
#> Resolved 35 packages in 364ms
#> Downloading pandas (11.7MiB)
#> Downloading pygsp (1.8MiB)
#> Downloaded pygsp
#> Downloaded pandas
#> Prepared 35 packages in 293ms
#> Uninstalled 5 packages in 18ms
#> Installed 35 packages in 59ms
#> + cloudpickle==3.1.2
#> + contourpy==1.3.2
#> + cycler==0.12.1
#> + decorator==5.3.1
#> + deprecated==1.3.1
#> + fonttools==4.65.0
#> + future==1.0.0
#> + graphtools==2.1.0
#> - igraph==0.11.9 (from file:///home/conda/feedstock_root/build_artifacts/python-igraph_1761728289959/work)
#> + igraph==0.11.9
#> + joblib==1.6.0
#> + kiwisolver==1.5.1
#> - leidenalg==0.10.2 (from file:///home/conda/feedstock_root/build_artifacts/leidenalg_1756310397572/work)
#> + leidenalg==0.10.2
#> + llvmlite==0.48.0
#> + matplotlib==3.10.8
#> + numba==0.66.0
#> + numpy==1.26.4
#> - packaging==26.3 (from file:///home/conda/feedstock_root/build_artifacts/bld/rattler-build_packaging_1785888127/work)
#> + packaging==26.3
#> + pandas==2.0.3
#> + phate==1.0.11
#> + pillow==12.3.0
#> + pygsp==0.6.1
#> + pyparsing==3.3.3
#> + python-dateutil==3.0.0
#> + pytz==2026.6
#> + s-gd2==1.8.1
#> + scikit-learn==1.7.0
#> + scipy==1.15.3
#> + scprep==1.2.3
#> ~ setuptools==80.10.2
#> + six==1.17.0
#> + tasklogger==1.2.0
#> - texttable==1.7.0 (from file:///home/conda/feedstock_root/build_artifacts/texttable_1734145585512/work)
#> + texttable==1.7.2
#> + threadpoolctl==3.8.0
#> + tzdata==2026.6
#> + wrapt==2.5.2
#> ✔ [2026-11-12 05:53:57] uv installation completed
#> + /home/runner/work/_temp/pkgdown-python/envs/scprep_env/bin/python3.10 -m pip check
#> No broken requirements found.
#> ✔ [2026-11-12 05:53:59] Python environment ready
#> ✔ Until next loading, the environment will be cached
#> Environment manager config:
#> Manager: micromamba
#> Executable: /home/runner/.cache/R/scop/micromamba/linux-64/bin/micromamba
#> Environment: /home/runner/work/_temp/pkgdown-python/envs/scprep_env
#> Python config:
#> python: /home/runner/work/_temp/pkgdown-python/envs/scprep_env/bin/python3.10
#> version: Python 3.10.1
#>
#> ℹ [2026-11-12 05:54:13] Perform phate nonlinear dimension reduction using Seuratpca (1:50)
#> ◌ [2026-11-12 05:54:16] Preparing python environment...
#> ℹ [2026-11-12 05:54:16] Environment name: 'scprep_env' and python version: 3.10-1
#> ℹ [2026-11-12 05:54:16] Auto-detecting conda-compatible environment manager...
#> ℹ [2026-11-12 05:54:16] Using micromamba executable: '/home/runner/.cache/R/scop/micromamba/linux-64/bin/micromamba'
#> ℹ [2026-11-12 05:54:16] Using existing environment: '/home/runner/work/_temp/pkgdown-python/envs/scprep_env'
#> ℹ [2026-11-12 05:54:16] 13 requirements to check, 3 conda requirements and 10 pip requirements
#> ℹ [2026-11-12 05:54:16] Checking 3 conda requirements
#> ℹ [2026-11-12 05:54:17] Checking 12 requirements using uv
#> + /home/runner/work/_temp/pkgdown-python/envs/scprep_env/bin/python3.10 -m pip check
#> No broken requirements found.
#> ✔ [2026-11-12 05:54:19] Python environment ready
#> ✔ Until next loading, the environment will be cached
#> Environment manager config:
#> Manager: micromamba
#> Executable: /home/runner/.cache/R/scop/micromamba/linux-64/bin/micromamba
#> Environment: /home/runner/work/_temp/pkgdown-python/envs/scprep_env
#> Python config:
#> python: /home/runner/work/_temp/pkgdown-python/envs/scprep_env/bin/python3.10
#> version: Python 3.10.1
#>
#> ℹ [2026-11-12 05:54:32] Perform pacmap nonlinear dimension reduction using Seuratpca (1:50)
#> ℹ [2026-11-12 05:54:32] Perform pacmap nonlinear dimension reduction using Seuratpca (1:50)
#> ℹ [2026-11-12 05:54:33] Perform trimap nonlinear dimension reduction using Seuratpca (1:50)
#> ℹ [2026-11-12 05:54:33] Perform trimap nonlinear dimension reduction using Seuratpca (1:50)
#> ℹ [2026-11-12 05:54:34] Perform largevis nonlinear dimension reduction using Seuratpca (1:50)
#> ℹ [2026-11-12 05:54:44] Perform largevis nonlinear dimension reduction using Seuratpca (1:50)
#> ℹ [2026-11-12 05:54:53] Perform fr nonlinear dimension reduction using Seurat_SNN
#> ℹ [2026-11-12 05:54:54] Perform fr nonlinear dimension reduction using Seurat_SNN
#> ℹ [2026-11-12 05:54:57] Perform umap nonlinear dimension reduction using Seuratpca (1:50)
#> ✔ [2026-11-12 05:55:18] Seurat integration completed
for (nr in nonlinear_reductions) {
print(
CellDimPlot(
panc8_sub,
group.by = c("tech", "celltype"),
reduction = paste0("Seurat", nr, "2D"),
xlab = "", ylab = "", title = nr,
legend.position = "none", theme_use = "theme_blank"
)
)
}