Run doublet-calling with Scrublet
Usage
RunScrublet(
  object,
  assay = "RNA",
  db_rate = ncol(srt)/1000 * 0.01,
  data_type = NULL,
  verbose = TRUE,
  srt = NULL,
  ...
)
Arguments
- object
A
Seuratobject.- assay
Assay used for doublet calling.
- db_rate
Expected doublet rate.
- data_type
Optional CheckDataType result, used internally to avoid rescanning the count matrix.
- verbose
Whether to print messages.
- srt
Deprecated alias for
object; supply exactly one of the two. It will be removed in scop 1.0.0.- ...
Arguments passed to other functions.
Examples
PrepareEnv(modules = "scrublet")
#> ◌ [2026-11-12 06:03:18] Preparing python environment...
#> ℹ [2026-11-12 06:03:18] Environment name: scop_env and python version: 3.10-1
#> ℹ [2026-11-12 06:03:18] Auto-detecting conda-compatible environment manager...
#> ℹ [2026-11-12 06:03:18] Using micromamba executable: /home/runner/.cache/R/scop/micromamba/linux-64/bin/micromamba
#> ℹ [2026-11-12 06:03:18] Using existing environment: /home/runner/work/_temp/pkgdown-python/envs/scop_env
#> ℹ [2026-11-12 06:03:18] 13 requirements to check, 3 conda requirements and 10 pip requirements
#> ℹ [2026-11-12 06:03:18] Checking 3 conda requirements
#> ℹ [2026-11-12 06:03:19] Checking 12 requirements using uv
#> + /home/runner/work/_temp/pkgdown-python/envs/scop_env/bin/python3.10 -m pip check
#> ✔ [2026-11-12 06:03:22] Python environment ready
#> ✔ Until next loading, the environment will be cached
#> Environment manager config:
#> Manager: micromamba
#> Executable: /home/runner/.cache/R/scop/micromamba/linux-64/bin/micromamba
#> Environment: /home/runner/work/_temp/pkgdown-python/envs/scop_env
#> Python config:
#> python: /home/runner/work/_temp/pkgdown-python/envs/scop_env/bin/python3.10
#> version: Python 3.10.1
data(pancreas_sub)
pancreas_sub <- RunStandardWorkflow(pancreas_sub)
#> ℹ [2026-11-12 06:03:22] Start standard processing workflow...
#> ℹ [2026-11-12 06:03:22] Checking a list of <Seurat>...
#> ! [2026-11-12 06:03:22] Data 1/1 of the `srt_list` is "unknown"
#> ℹ [2026-11-12 06:03:22] Perform `NormalizeData()` with `normalization.method = 'LogNormalize'` on 1/1 of `srt_list`...
#> ℹ [2026-11-12 06:03:22] Perform `FindVariableFeatures()` on 1/1 of `srt_list`...
#> ℹ [2026-11-12 06:03:22] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 06:03:22] Number of available HVF: 2000
#> ℹ [2026-11-12 06:03:22] Finished check
#> ℹ [2026-11-12 06:03:22] Perform `ScaleData()`
#> ℹ [2026-11-12 06:03:22] Perform pca linear dimension reduction
#> ℹ [2026-11-12 06:03:23] Use stored estimated dimensions 1:23 for Standardpca
#> ℹ [2026-11-12 06:03:23] Perform `Seurat::FindClusters()` with `cluster_algorithm = 'louvain'` and `cluster_resolution = 0.6`
#> ℹ [2026-11-12 06:03:23] Reorder clusters...
#> ℹ [2026-11-12 06:03:23] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 06:03:23] Perform umap nonlinear dimension reduction
#> ✔ [2026-11-12 06:03:33] Standard processing workflow completed
pancreas_sub <- RunScrublet(pancreas_sub)
#> ℹ [2026-11-12 06:03:33] Running Scrublet
#> ✔ [2026-11-12 06:03:33] Python environment completed
#> ✔ Until next loading, the environment will be cached
#> ℹ [2026-11-12 06:03:33] Data type is raw counts
#> ✔ [2026-11-12 06:03:35] Scrublet doublet calling completed
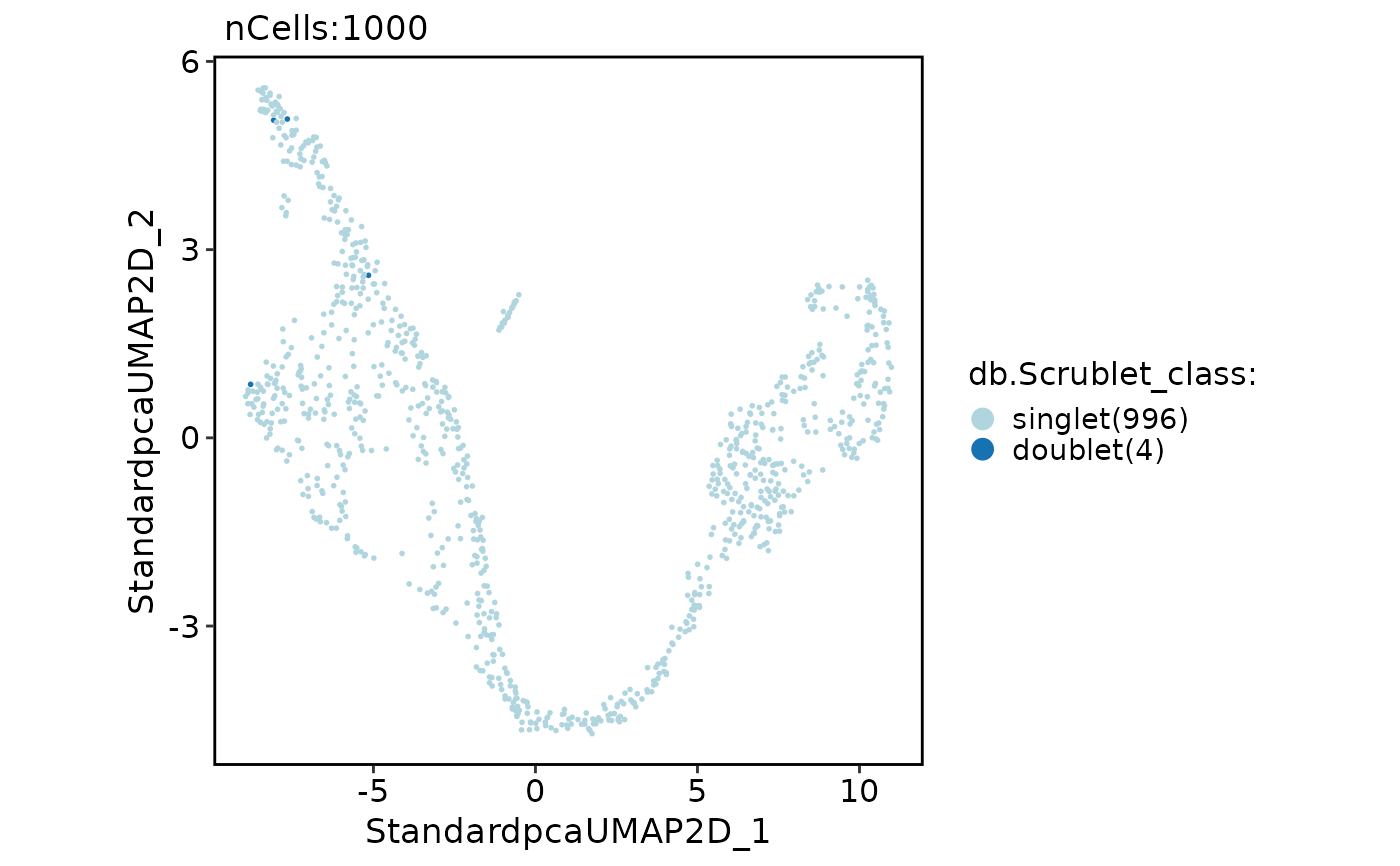
CellDimPlot(
pancreas_sub,
reduction = "umap",
group.by = "db.Scrublet_class"
)
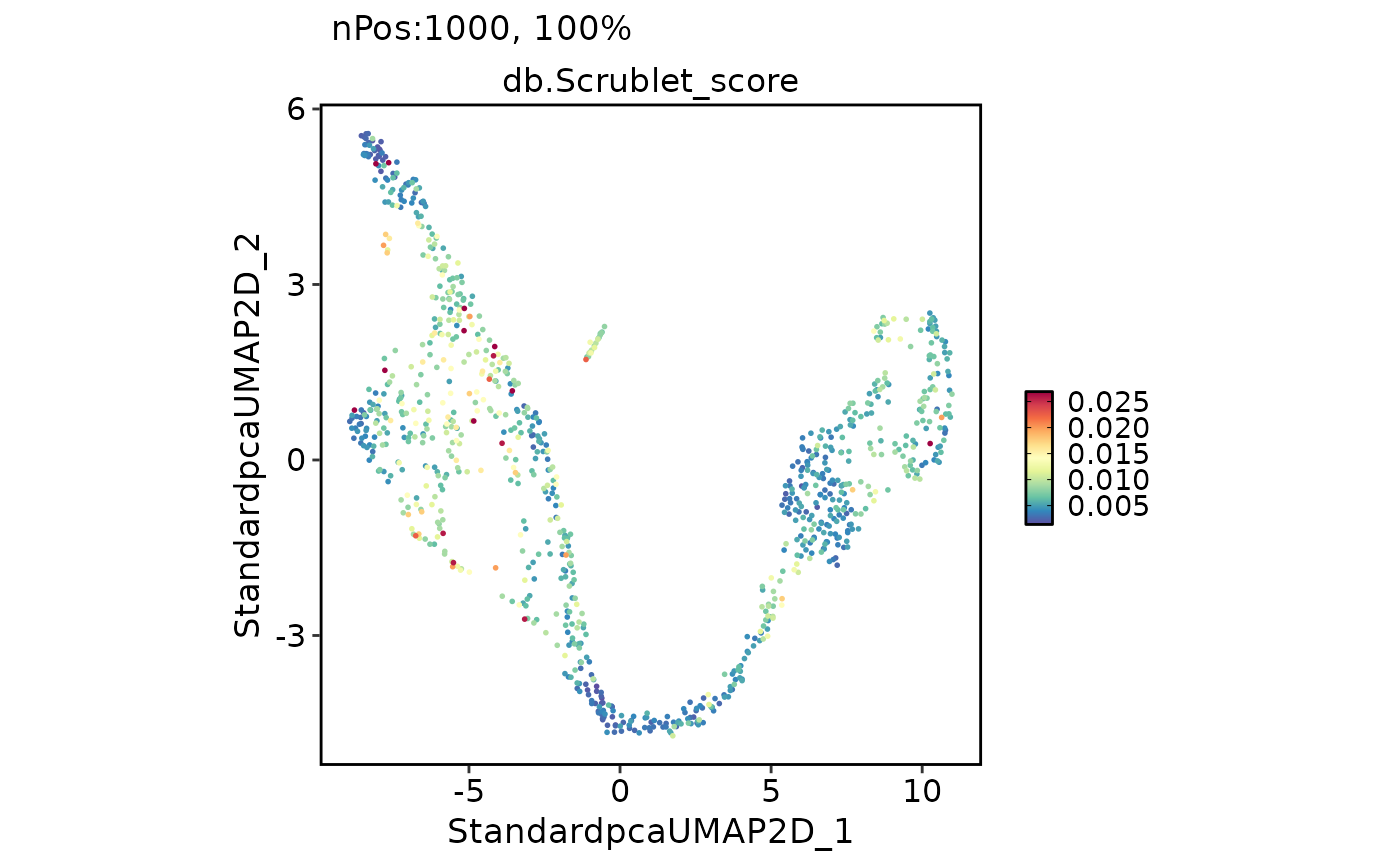
 FeatureDimPlot(
pancreas_sub,
reduction = "umap",
features = "db.Scrublet_score"
)