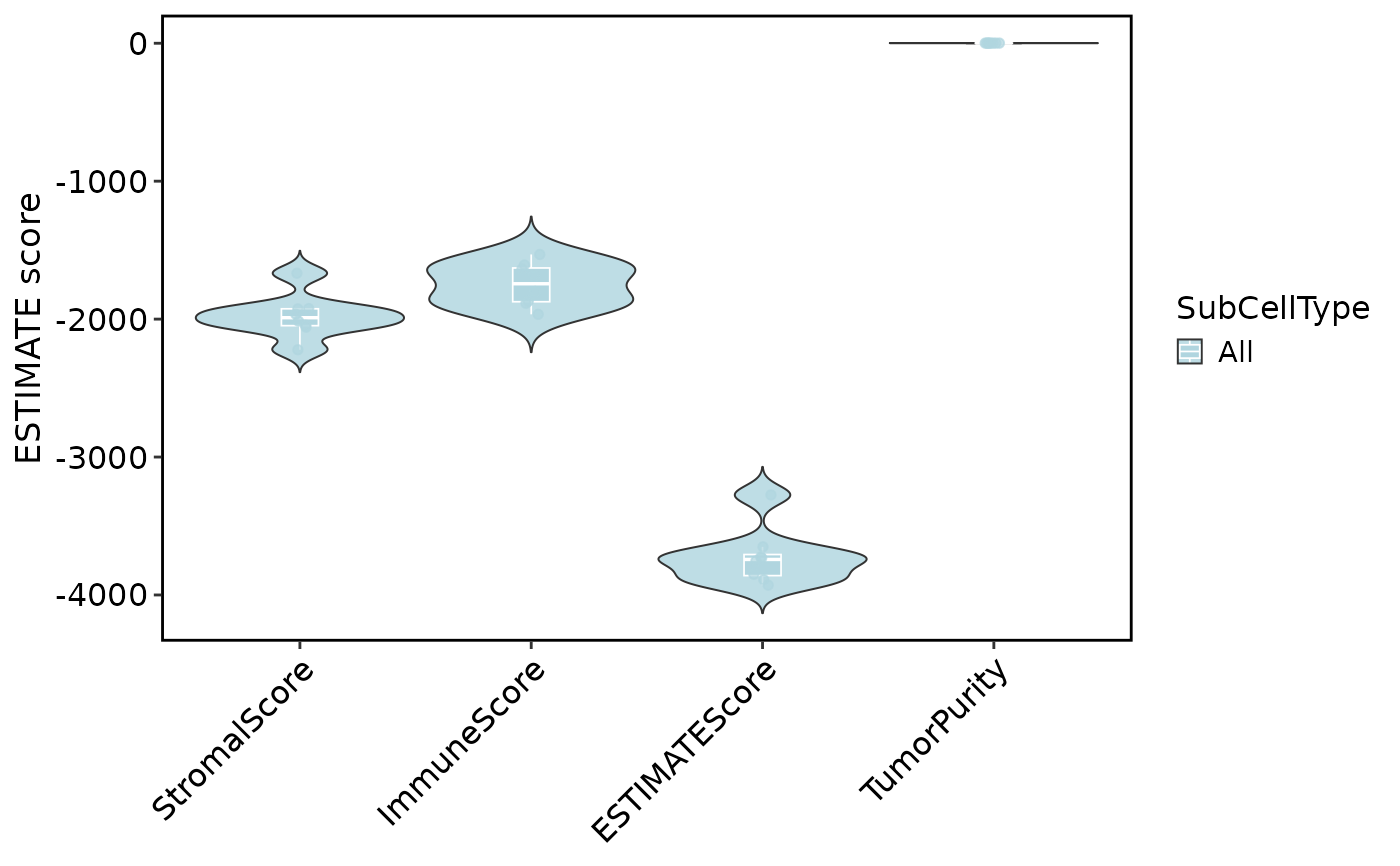
Visualize ESTIMATE stromal, immune, combined ESTIMATE, and tumor-purity
scores from a RunESTIMATE() result.
Arguments
- object
Optional
RunESTIMATE()bundle,SummarizedExperiment, orSeuratobject containing ESTIMATE results.- score.data
Optional score matrix or data frame with samples in rows.
- group.by
Optional grouping column for grouped violin and box plots.
- group.data
Optional named vector or data frame containing sample groups.
- plot_type
Plot type.
- scores
ESTIMATE score columns to plot.
- add_stat
Whether to add group comparison labels to violin or box plots. Requires
ggpubr.- ...
Additional plotting arguments.
Examples
data(pancreas_sub)
pancreas_sub <- RunStandardWorkflow(pancreas_sub)
#> ℹ [2026-10-11 22:50:08] Start standard processing workflow...
#> ℹ [2026-10-11 22:50:08] Checking a list of <Seurat>...
#> ! [2026-10-11 22:50:08] Data 1/1 of the `srt_list` is "unknown"
#> ℹ [2026-10-11 22:50:08] Perform `NormalizeData()` with `normalization.method = 'LogNormalize'` on 1/1 of `srt_list`...
#> ℹ [2026-10-11 22:50:08] Perform `FindVariableFeatures()` on 1/1 of `srt_list`...
#> ℹ [2026-10-11 22:50:08] Use the separate HVF from `srt_list`
#> ℹ [2026-10-11 22:50:08] Number of available HVF: 2000
#> ℹ [2026-10-11 22:50:08] Finished check
#> ℹ [2026-10-11 22:50:08] Perform `ScaleData()`
#> ℹ [2026-10-11 22:50:08] Perform pca linear dimension reduction
#> ℹ [2026-10-11 22:50:09] Use stored estimated dimensions 1:23 for Standardpca
#> ℹ [2026-10-11 22:50:09] Perform `Seurat::FindClusters()` with `cluster_algorithm = 'louvain'` and `cluster_resolution = 0.6`
#> ℹ [2026-10-11 22:50:09] Reorder clusters...
#> ℹ [2026-10-11 22:50:09] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-10-11 22:50:09] Perform umap nonlinear dimension reduction
#> ✔ [2026-10-11 22:50:15] Standard processing workflow completed
pancreas_sub <- RunESTIMATE(pancreas_sub, group.by = "SubCellType")
#> ℹ [2026-10-11 22:50:15] ESTIMATE input: 15997 genes x 8 samples
#> ℹ [2026-10-11 22:50:15] Use 8011 ESTIMATE common genes for scoring
#> ℹ [2026-10-11 22:50:15] ESTIMATE signature overlap: stromal 79, immune 77
EstimateScorePlot(pancreas_sub, group.by = "SubCellType")