Plots for metabolism pathway scoring
Usage
MetabolismPlot(
  object = NULL,
  res = NULL,
  group.by = NULL,
  assay_name = "METABOLISM",
  verbose = TRUE,
  srt = NULL,
  ...
)
Arguments
- object
A Seurat object containing the results of RunMetabolism.
- res
GSVA results generated by RunGSVA function. If provided, 'srt' and 'group.by' are ignored.
- group.by
Grouping variable used in RunMetabolism.
- assay_name
Assay or tools slot containing metabolism results.
- verbose
Whether to print messages.
- srt
Deprecated alias for
object; supply exactly one of the two. It will be removed in scop 1.0.0.- ...
Arguments passed to other functions.
Examples
data(pancreas_sub)
pancreas_sub <- RunStandardWorkflow(pancreas_sub)
#> ℹ [2026-11-12 05:22:10] Start standard processing workflow...
#> ℹ [2026-11-12 05:22:10] Checking a list of <Seurat>...
#> ! [2026-11-12 05:22:10] Data 1/1 of the `srt_list` is "unknown"
#> ℹ [2026-11-12 05:22:11] Perform `NormalizeData()` with `normalization.method = 'LogNormalize'` on 1/1 of `srt_list`...
#> ℹ [2026-11-12 05:22:11] Perform `FindVariableFeatures()` on 1/1 of `srt_list`...
#> ℹ [2026-11-12 05:22:11] Use the separate HVF from `srt_list`
#> ℹ [2026-11-12 05:22:11] Number of available HVF: 2000
#> ℹ [2026-11-12 05:22:11] Finished check
#> ℹ [2026-11-12 05:22:11] Perform `ScaleData()`
#> ℹ [2026-11-12 05:22:11] Perform pca linear dimension reduction
#> ℹ [2026-11-12 05:22:11] Use stored estimated dimensions 1:23 for Standardpca
#> ℹ [2026-11-12 05:22:12] Perform `Seurat::FindClusters()` with `cluster_algorithm = 'louvain'` and `cluster_resolution = 0.6`
#> ℹ [2026-11-12 05:22:12] Reorder clusters...
#> ℹ [2026-11-12 05:22:12] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-11-12 05:22:12] Perform umap nonlinear dimension reduction
#> ✔ [2026-11-12 05:22:20] Standard processing workflow completed
pancreas_sub <- RunMetabolism(
pancreas_sub,
db = c("KEGG", "REACTOME"),
group.by = "CellType",
species = "Mus_musculus",
Ensembl_version = 115,
method = "AUCell",
use_preparedb = FALSE
)
#> ℹ [2026-11-12 05:22:20] Start metabolism pathway scoring
#> ℹ [2026-11-12 05:22:20] Data type is raw counts
#> ℹ [2026-11-12 05:22:20] Averaging expression by "CellType" ...
#> ℹ [2026-11-12 05:22:20] Aggregated expression: 15998 genes x 5 groups
#> ℹ [2026-11-12 05:22:20] Using raw scMetabolism gene sets with species conversion to "Mus_musculus"
#> ℹ [2026-11-12 05:22:21] Converting 3297 human gene symbols to "Mus_musculus" via biomaRt ...
#> ℹ [2026-11-12 05:22:21] Connect to the Ensembl archives...
#> ℹ [2026-11-12 05:22:21] Using the 115 version of ensembl database...
#> ℹ [2026-11-12 05:22:21] Downloading the ensembl database from https://sep2025.archive.ensembl.org...
#> ℹ [2026-11-12 05:22:21] Searching the dataset hsapiens ...
#> ℹ [2026-11-12 05:22:22] Connecting to the dataset hsapiens_gene_ensembl ...
#> ℹ [2026-11-12 05:22:23] Converting the geneIDs...
#> ℹ [2026-11-12 05:22:26] 3256 genes mapped with "ensembl_symbol"
#> ℹ [2026-11-12 05:22:27] 13 genes mapped with "entrez_symbol"
#> ℹ [2026-11-12 05:22:29] 6 genes mapped with "uniprot_symbol"
#> ℹ [2026-11-12 05:22:29] ==============================
#> ℹ 3275 genes mapped
#> ℹ 22 genes unmapped
#> ℹ ==============================
#> ✔ [2026-11-12 05:22:31] Species conversion added 207 gene matches across pathways
#> ℹ [2026-11-12 05:22:31] Total metabolism gene sets to score: 127
#> ✔ [2026-11-12 05:22:31] Metabolism scores stored in tools slot "Metabolism_CellType_AUCell"
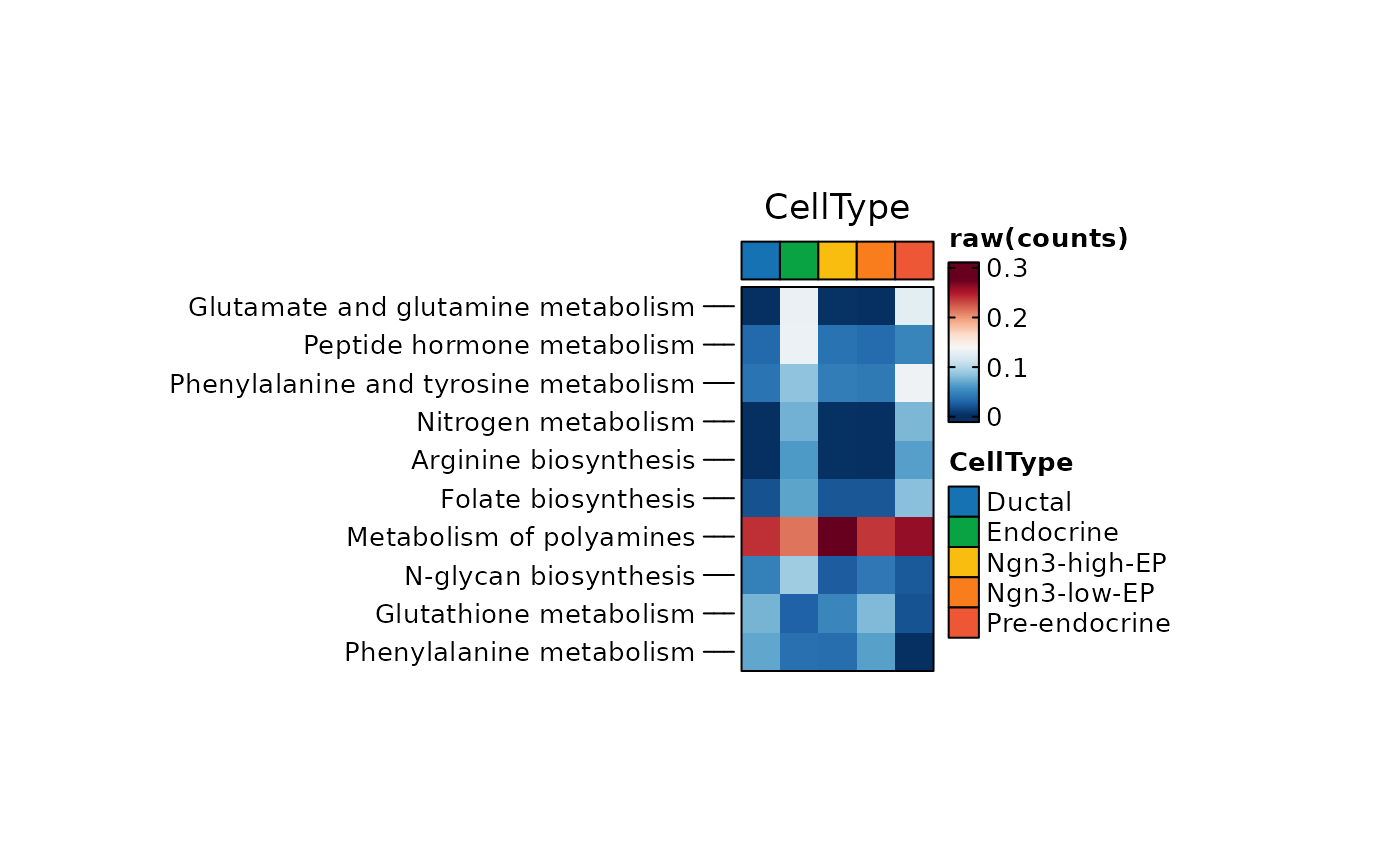
ht1 <- MetabolismPlot(
pancreas_sub,
group.by = "CellType",
plot_type = "heatmap",
topTerm = 10,
show_row_names = TRUE,
width = 1,
height = 2
)
ht1$plot
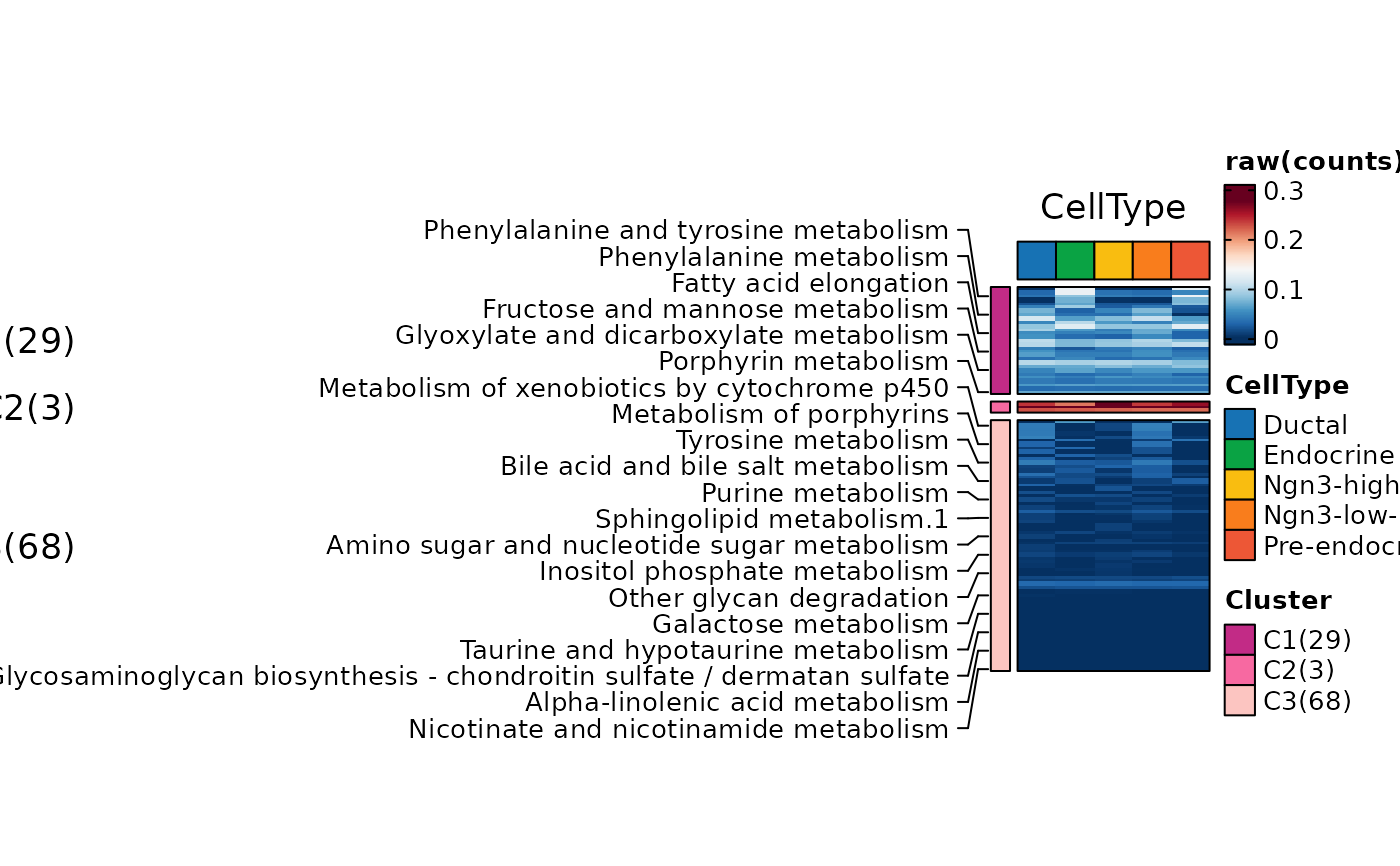
 ht2 <- MetabolismPlot(
pancreas_sub,
group.by = "CellType",
plot_type = "heatmap",
n_split = 3,
topTerm = 100,
use_raster = TRUE,
width = 1,
height = 2
)
ht2$plot
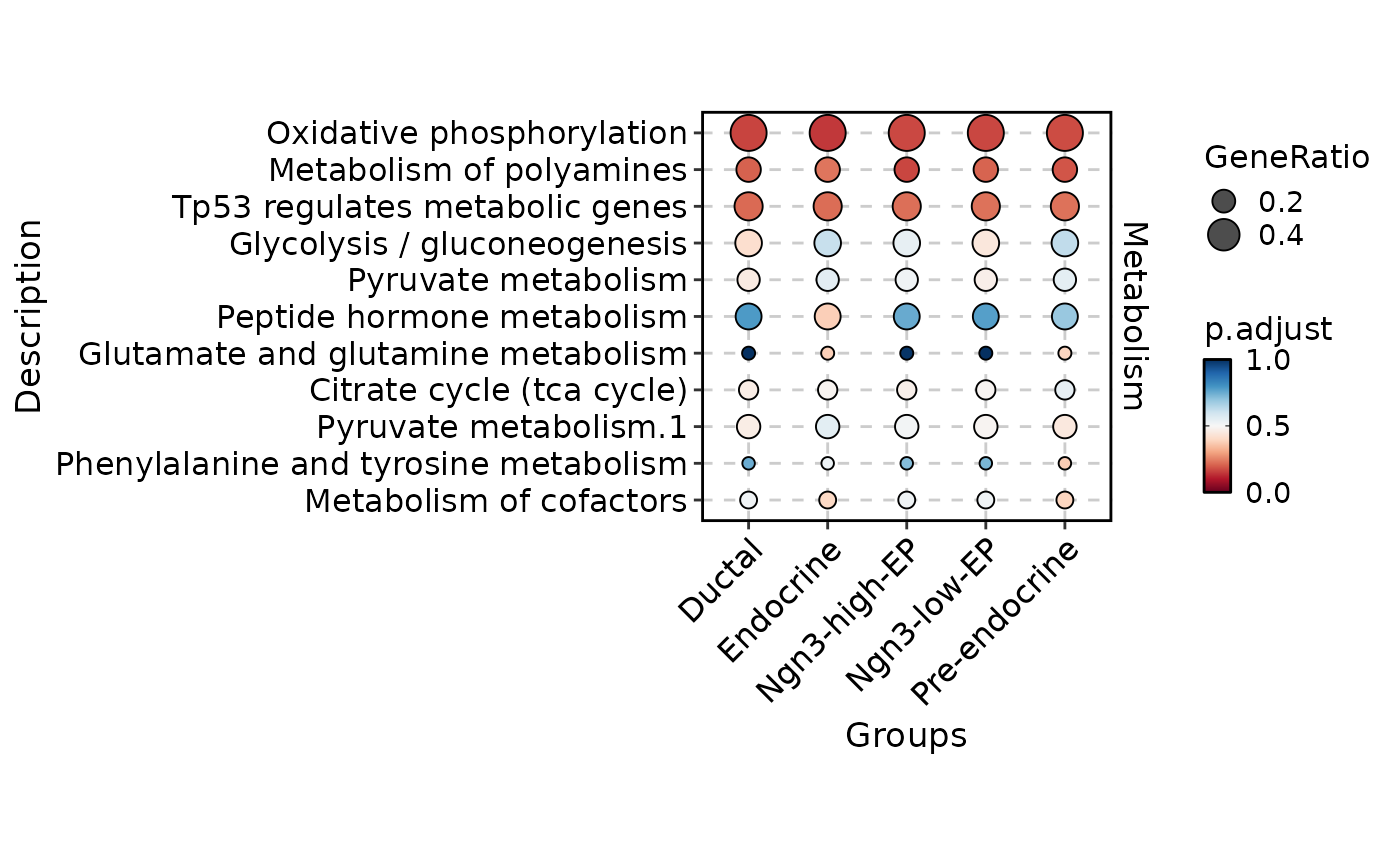
 MetabolismPlot(
pancreas_sub,
group.by = "CellType",
db = "GO_BP",
plot_type = "comparison",
topTerm = 5
)
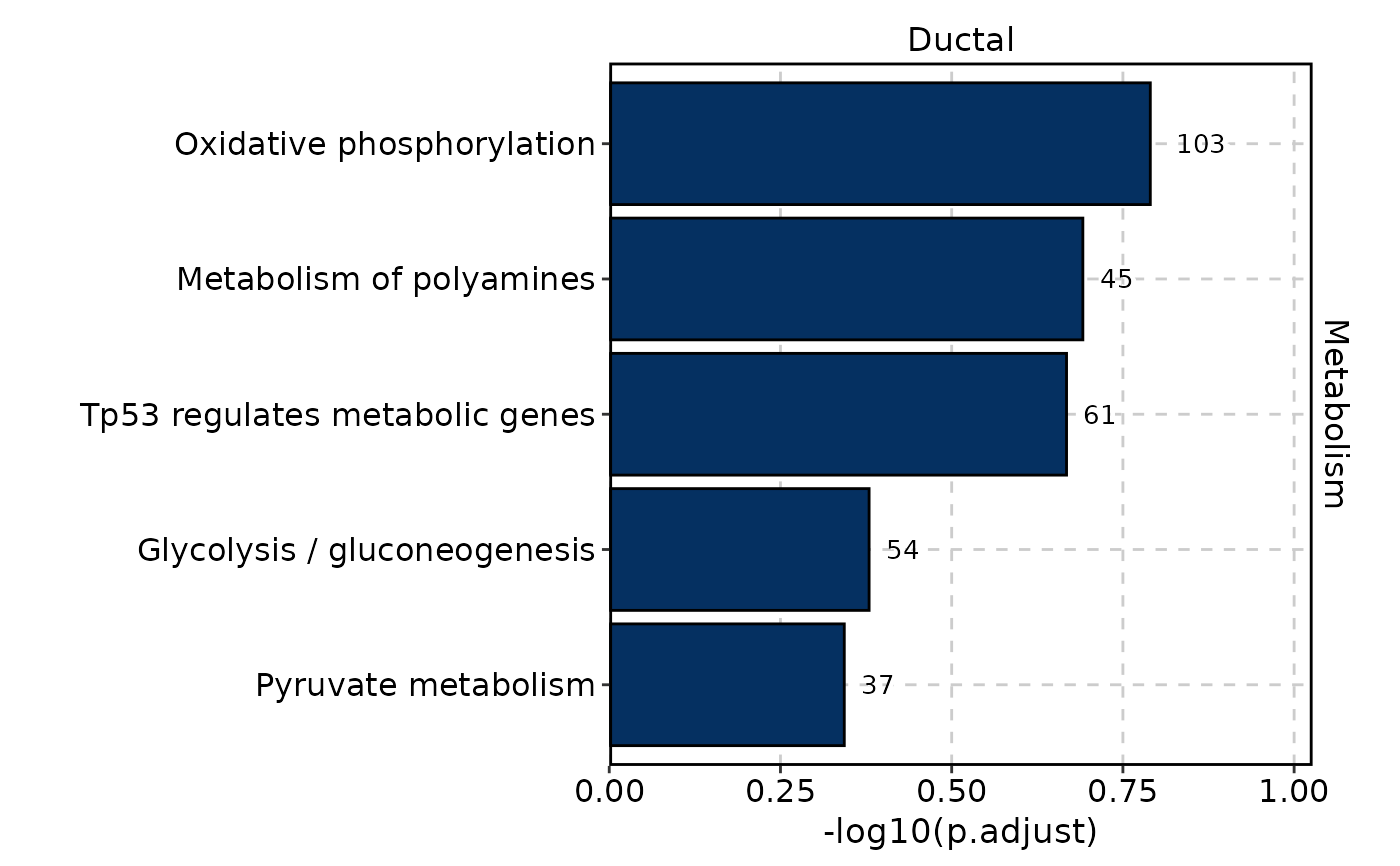
 MetabolismPlot(
pancreas_sub,
group.by = "CellType",
db = "GO_BP",
group_use = "Ductal",
plot_type = "bar",
topTerm = 5
)
 MetabolismPlot(
pancreas_sub,
group.by = "CellType",
group_use = "Ductal",
db = "GO_BP",
plot_type = "network",
topTerm = 3
)
#> ✔ [2026-11-12 05:22:34] shadowtext installed successfully
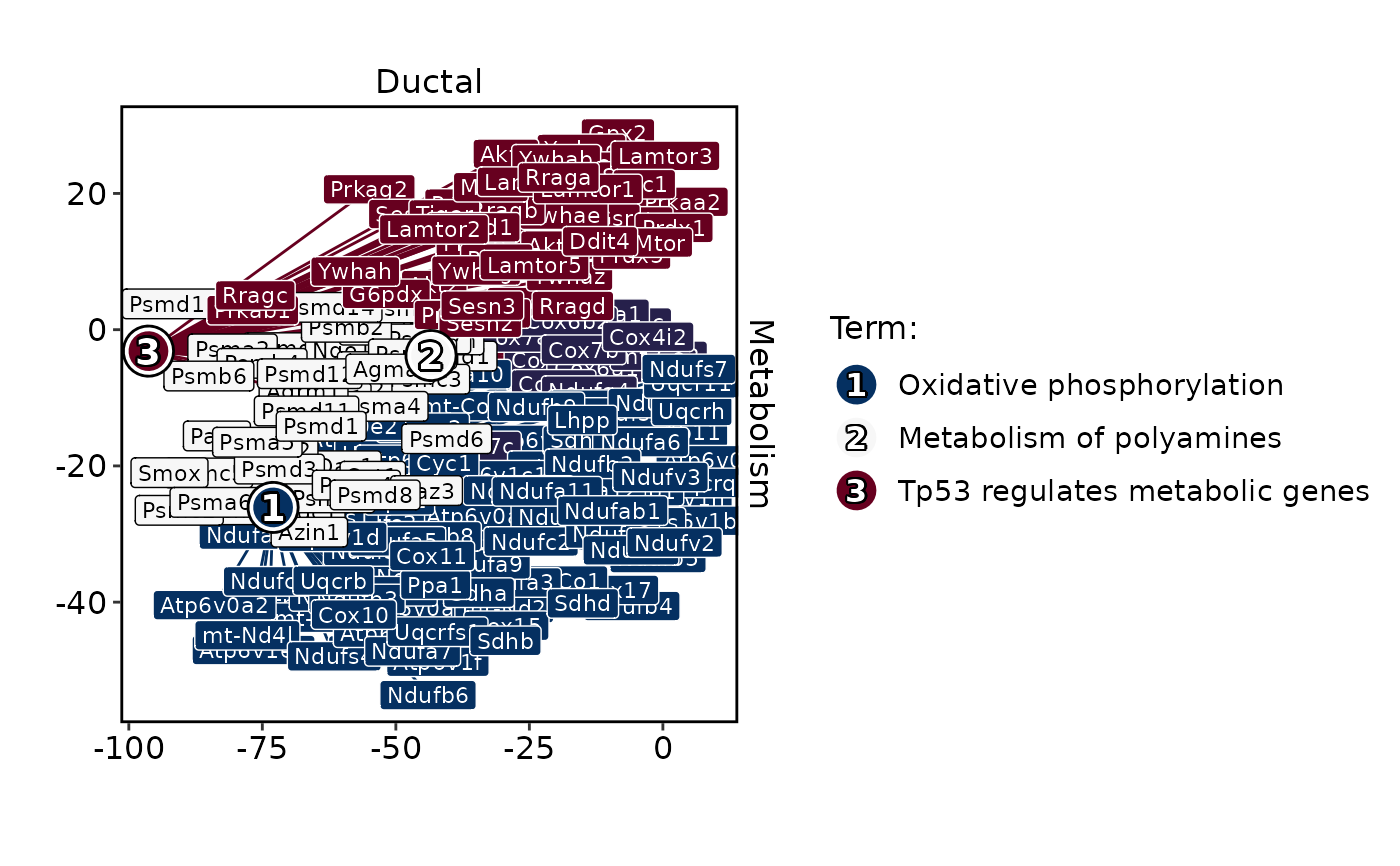 MetabolismPlot(
pancreas_sub,
group.by = "CellType",
group_use = "Ductal",
db = "GO_BP",
plot_type = "enrichmap"
)
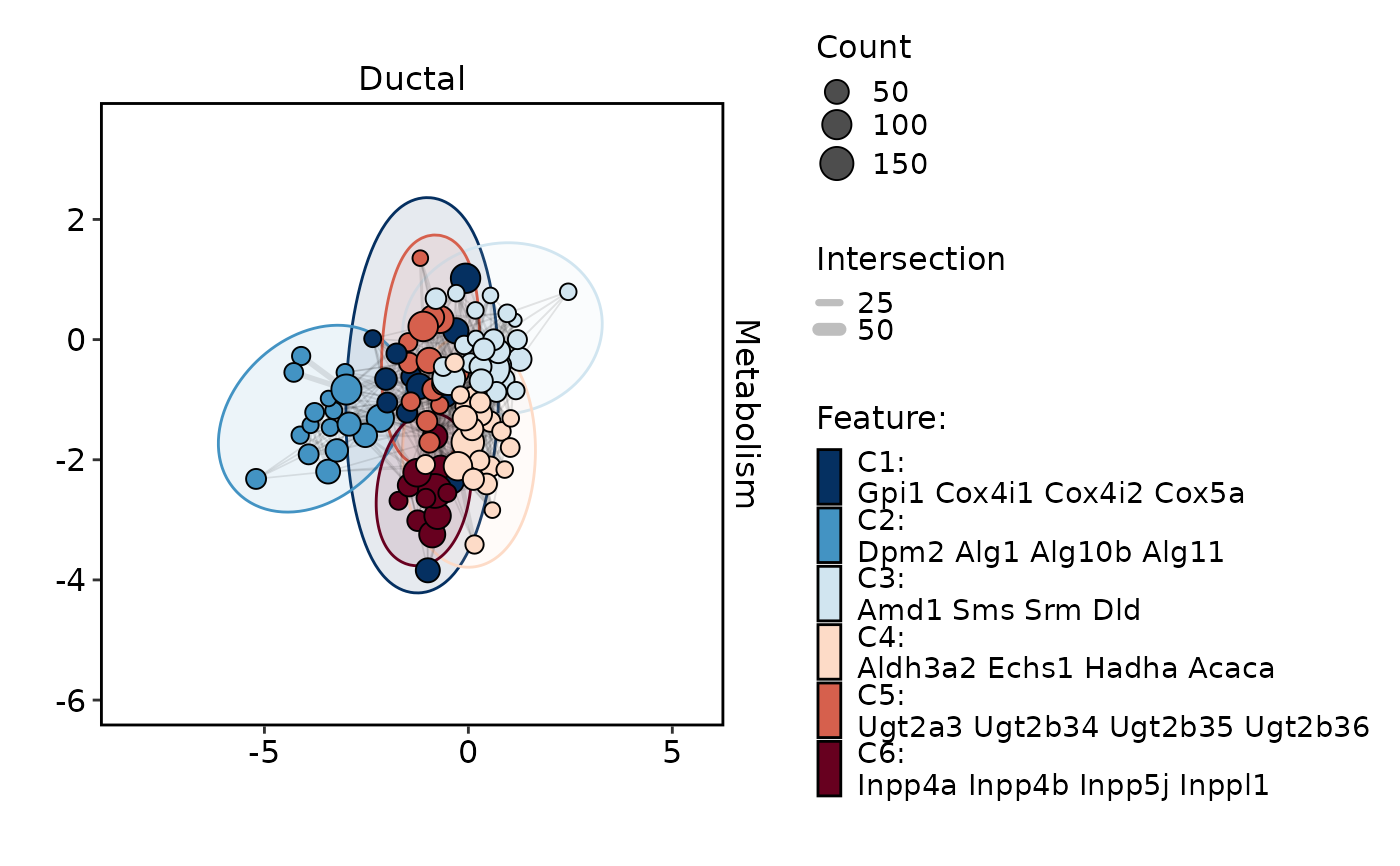 MetabolismPlot(
pancreas_sub,
group.by = "CellType",
group_use = "Ductal",
plot_type = "wordcloud",
word_type = "feature"
)
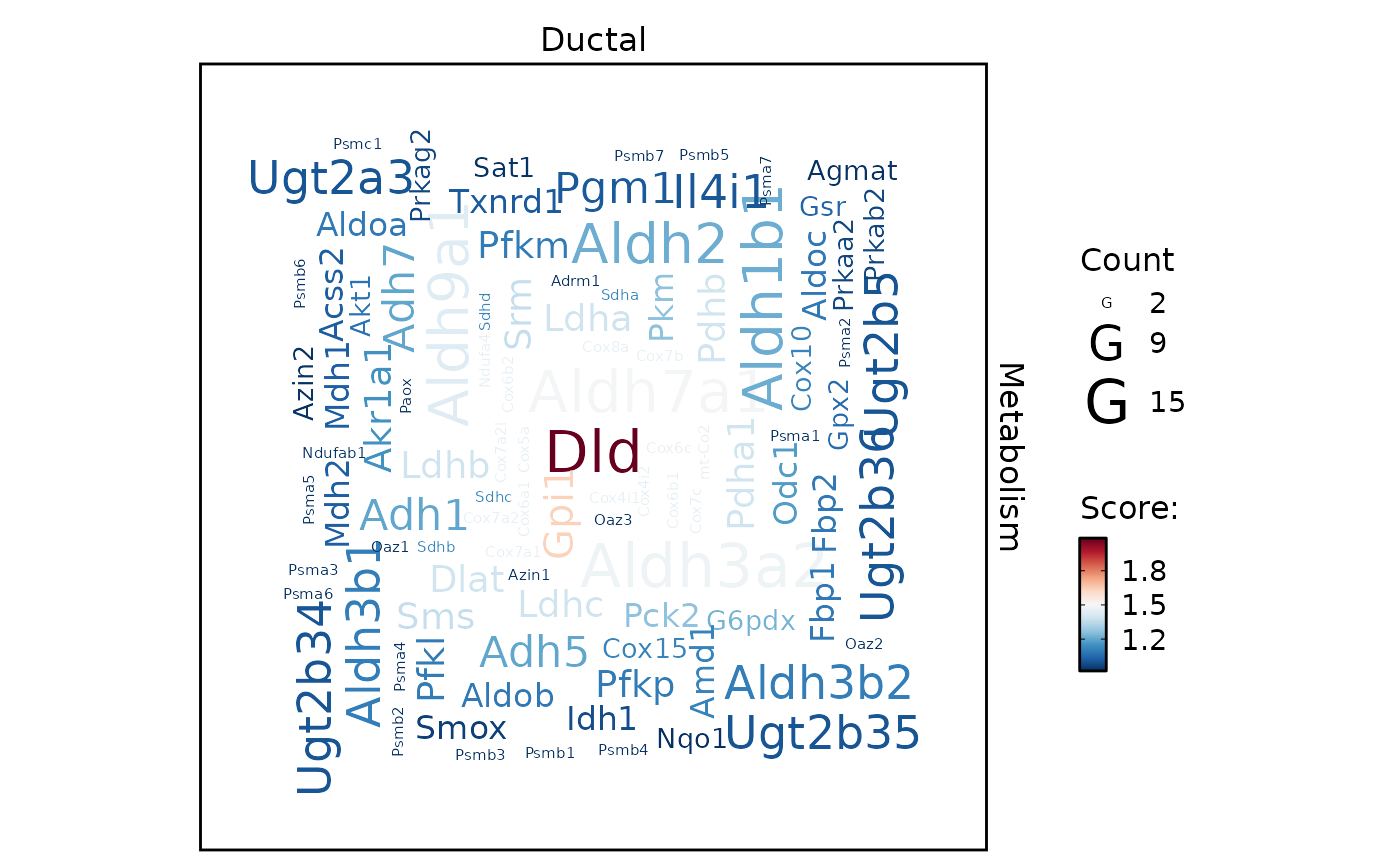 pancreas_sub <- RunMetabolism(
pancreas_sub,
assay_name = "METABOLISM",
db = c("KEGG", "REACTOME"),
species = "Mus_musculus",
Ensembl_version = 115,
use_preparedb = FALSE
)
#> ℹ [2026-11-12 05:22:39] Start metabolism pathway scoring
#> ℹ [2026-11-12 05:22:40] Data type is raw counts
#> ℹ [2026-11-12 05:22:40] Using raw scMetabolism gene sets with species conversion to "Mus_musculus"
#> ℹ [2026-11-12 05:22:40] Converting 3297 human gene symbols to "Mus_musculus" via biomaRt ...
#> ℹ [2026-11-12 05:22:40] Connect to the Ensembl archives...
#> ℹ [2026-11-12 05:22:40] Using the 115 version of ensembl database...
#> ℹ [2026-11-12 05:22:40] Downloading the ensembl database from https://sep2025.archive.ensembl.org...
#> ℹ [2026-11-12 05:22:40] Searching the dataset hsapiens ...
#> ℹ [2026-11-12 05:22:40] Connecting to the dataset hsapiens_gene_ensembl ...
#> ℹ [2026-11-12 05:22:41] Converting the geneIDs...
#> ℹ [2026-11-12 05:22:41] 3256 genes mapped with "ensembl_symbol"
#> ℹ [2026-11-12 05:22:42] 13 genes mapped with "entrez_symbol"
#> ℹ [2026-11-12 05:22:43] 6 genes mapped with "uniprot_symbol"
#> ℹ [2026-11-12 05:22:43] ==============================
#> ℹ 3275 genes mapped
#> ℹ 22 genes unmapped
#> ℹ ==============================
#> ✔ [2026-11-12 05:22:44] Species conversion added 207 gene matches across pathways
#> ℹ [2026-11-12 05:22:44] Total metabolism gene sets to score: 127
#> ✔ [2026-11-12 05:22:45] Metabolism scores stored in tools slot "Metabolism_AUCell"
#> ℹ [2026-11-12 05:22:45] Metabolism scores also stored in assay "METABOLISM"
FeatureDimPlot(
pancreas_sub,
assay = "METABOLISM",
features = rownames(pancreas_sub[["METABOLISM"]])[1:2],
reduction = "umap"
)
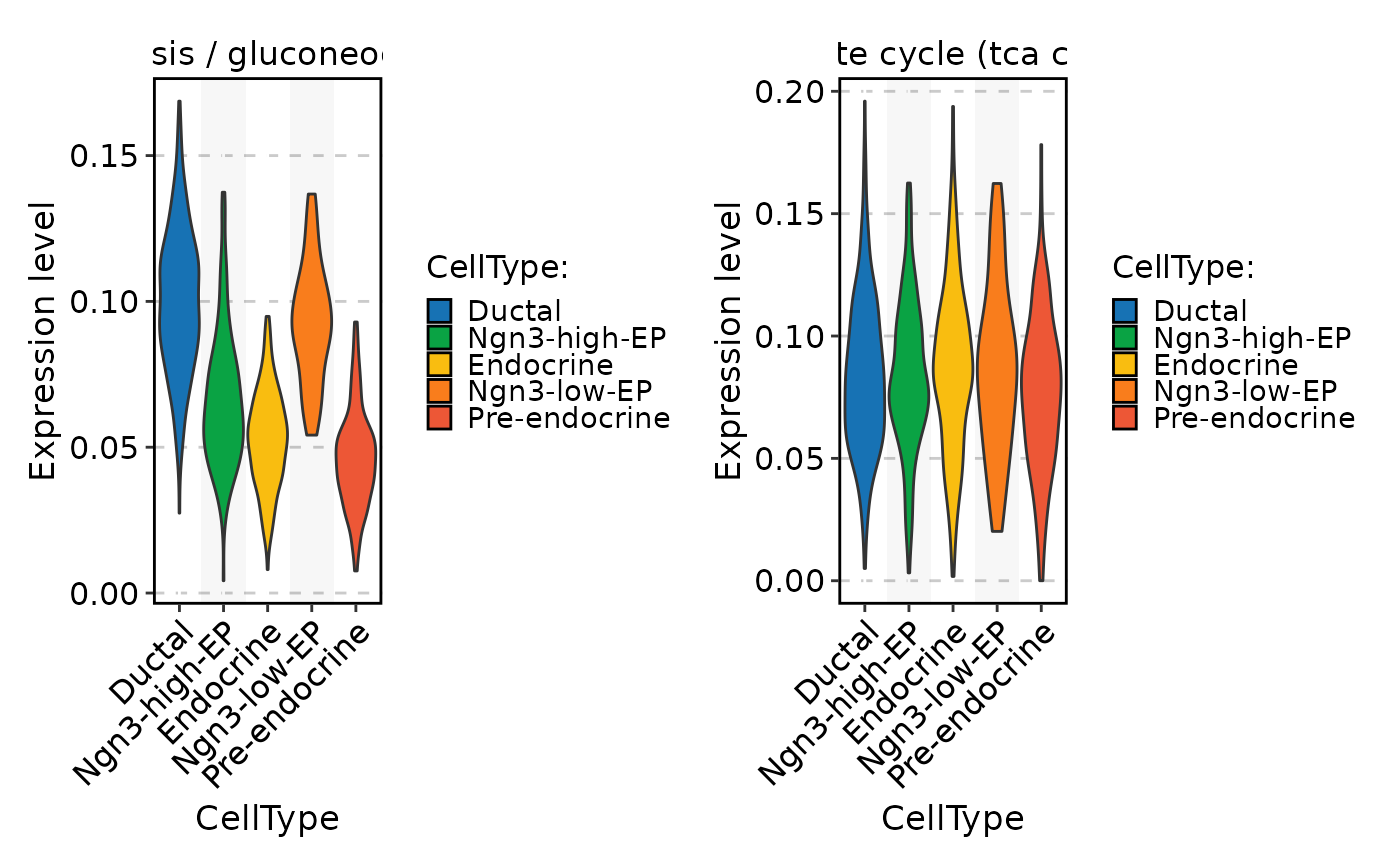
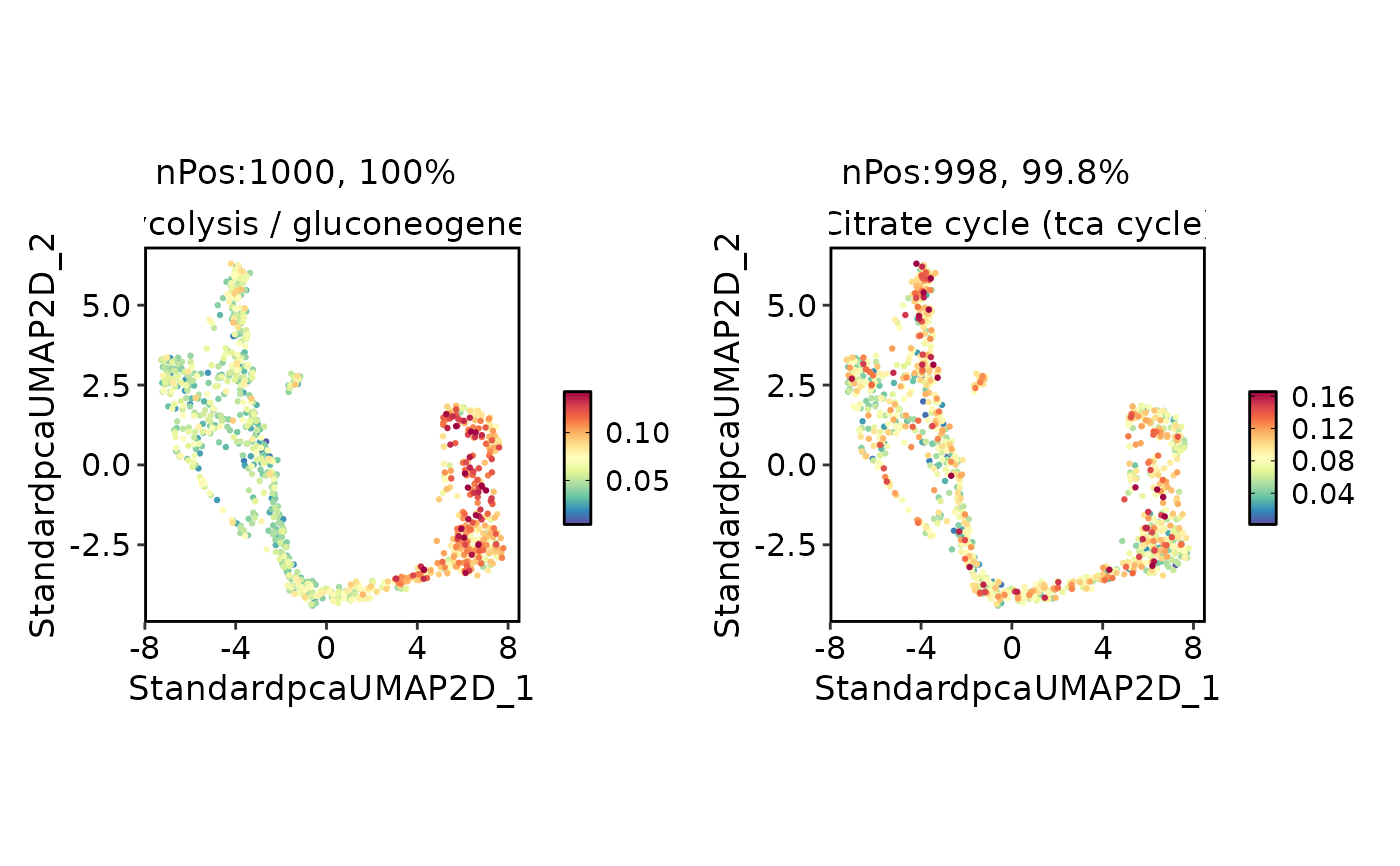 FeatureStatPlot(
pancreas_sub,
stat.by = rownames(pancreas_sub[["METABOLISM"]])[1:2],
group.by = "CellType",
assay = "METABOLISM"
)
 ht <- GroupHeatmap(
pancreas_sub,
exp_legend_title = "Z-score",
features = rownames(pancreas_sub[["METABOLISM"]])[1:10],
group.by = "CellType",
assay = "METABOLISM",
width = 1,
height = 2
)
#> ! [2026-11-12 05:22:46] The values in the "counts" layer are non-integer. Set the library size to "1"