Run generalized principal components analysis (GLMPCA)
Usage
RunGLMPCA(object, ...)

# S3 method for class 'Seurat'
RunGLMPCA(
  object,
  assay = NULL,
  layer = "counts",
  features = NULL,
  L = 5,
  fam = c("poi", "nb", "nb2", "binom", "mult", "bern"),
  rev.gmlpca = FALSE,
  ndims.print = 1:5,
  nfeatures.print = 30,
  reduction.name = "glmpca",
  reduction.key = "GLMPC_",
  verbose = TRUE,
  seed.use = 11,
  ...
)

# S3 method for class 'Assay'
RunGLMPCA(
  object,
  assay = NULL,
  layer = "counts",
  features = NULL,
  L = 5,
  fam = c("poi", "nb", "nb2", "binom", "mult", "bern"),
  rev.gmlpca = FALSE,
  ndims.print = 1:5,
  nfeatures.print = 30,
  reduction.key = "GLMPC_",
  verbose = TRUE,
  seed.use = 11,
  ...
)

# S3 method for class 'Assay5'
RunGLMPCA(
  object,
  assay = NULL,
  layer = "counts",
  features = NULL,
  L = 5,
  fam = c("poi", "nb", "nb2", "binom", "mult", "bern"),
  rev.gmlpca = FALSE,
  ndims.print = 1:5,
  nfeatures.print = 30,
  reduction.key = "GLMPC_",
  verbose = TRUE,
  seed.use = 11,
  ...
)

# Default S3 method
RunGLMPCA(
  object,
  assay = NULL,
  layer = "counts",
  features = NULL,
  L = 5,
  fam = c("poi", "nb", "nb2", "binom", "mult", "bern"),
  rev.gmlpca = FALSE,
  ndims.print = 1:5,
  nfeatures.print = 30,
  reduction.key = "GLMPC_",
  verbose = TRUE,
  seed.use = 11,
  ...
)
Arguments
- object
An object. Can be a Seurat object, an assay object, or a matrix-like object.
- ...
Passed to the glmpca::glmpca function.
- assay
Assay to use.
NULLuses the default assay.- layer
Assay layer to use.
- features
Features used instead of a reduction.
- L
The number of components to be computed.
- fam
The family of the generalized linear model to be used. Currently supported values are
"poi","nb","nb2","binom","mult", and"bern".- rev.gmlpca
Whether to perform reverse GLMPCA (i.e., transpose the input matrix) before running the analysis.
- ndims.print
The dimensions (number of components) to print in the output.
- nfeatures.print
The number of features to print in the output.
- reduction.name
Reduction to be stored in the Seurat object.
- reduction.key
The prefix for the column names of the basis vectors.
- verbose
Whether to print the message. Default is
TRUE.- seed.use
Random seed.
Examples
data(pancreas_sub)
pancreas_sub <- RunStandardWorkflow(pancreas_sub)
#> ℹ [2026-10-11 23:19:00] Start standard processing workflow...
#> ℹ [2026-10-11 23:19:00] Checking a list of <Seurat>...
#> ! [2026-10-11 23:19:00] Data 1/1 of the `srt_list` is "unknown"
#> ℹ [2026-10-11 23:19:00] Perform `NormalizeData()` with `normalization.method = 'LogNormalize'` on 1/1 of `srt_list`...
#> ℹ [2026-10-11 23:19:00] Perform `FindVariableFeatures()` on 1/1 of `srt_list`...
#> ℹ [2026-10-11 23:19:00] Use the separate HVF from `srt_list`
#> ℹ [2026-10-11 23:19:00] Number of available HVF: 2000
#> ℹ [2026-10-11 23:19:00] Finished check
#> ℹ [2026-10-11 23:19:00] Perform `ScaleData()`
#> ℹ [2026-10-11 23:19:00] Perform pca linear dimension reduction
#> ℹ [2026-10-11 23:19:00] Use stored estimated dimensions 1:23 for Standardpca
#> ℹ [2026-10-11 23:19:01] Perform `Seurat::FindClusters()` with `cluster_algorithm = 'louvain'` and `cluster_resolution = 0.6`
#> ℹ [2026-10-11 23:19:01] Reorder clusters...
#> ℹ [2026-10-11 23:19:01] Skip `log1p()` because `layer = data` is not "counts"
#> ℹ [2026-10-11 23:19:01] Perform umap nonlinear dimension reduction
#> ✔ [2026-10-11 23:19:08] Standard processing workflow completed
pancreas_sub <- RunGLMPCA(pancreas_sub)
#> ℹ GLMPC_ 1
#> ℹ Positive:  Anxa1, Sparcl1, Col6a1, Gm26633, Col23a1, Ctgf, Sp140, Galnt16, Isg15, Islr
#> ℹ 	   Col1a1, Ctsk, Tnni3, Zfp385b, Hoxb4, Col1a2, P2ry2, Plscr2, Cxcl10, Kcnj8
#> ℹ 	   Platr22, Pmp22, Smpx, Col3a1, Gm15640, Prickle2, Edn1, 1110002O04Rik, Pgr, Apcs
#> ℹ Negative:  Barx2, Gm3448, Fam71b, Ky, Gm933, Ptger3, Mesp1, Gm6086, Cartpt, Bcas1os1
#> ℹ 	   Platr26, Cypt3, 3930402G23Rik, Ngf, Srrm3, Dusp26, Nlgn1, Gm4319, Prl, Doc2a
#> ℹ 	   Klk11, 2410021H03Rik, 1700001C02Rik, Gad1, Lrrc6, Ucn3, Cdkn2b, Foxd3, Acoxl, Bhlhe23
#> ℹ GLMPC_ 2
#> ℹ Positive:  Islr, Kcnj8, Sparcl1, Col1a1, Tmem119, Galnt16, Col3a1, Col1a2, Col6a1, Fam71b
#> ℹ 	   L1td1, Sapcd1, Col5a1, Col23a1, Pdcd1, Klk11, Calb1, Jakmip3, Gcg, Adra2c
#> ℹ 	   Pkd2l1, Acoxl, Tmem114, Bcas1os1, Tfap2c, Oasl2, Wnt3, 1700128E19Rik, Rspo1, Guca2a
#> ℹ Negative:  Sst, Kcne2, Rac2, Col25a1, RP23-428N8.3, Dkk2, Ceacam10, Gtf2ird2, Gm26633, RP23-58K20.3
#> ℹ 	   Ctsk, Srgn, Afap1l2, Gm6410, Tnni3, D7Ertd443e, Elovl4, Tstd1, Klhl14, Fcgr3
#> ℹ 	   Itgb7, Lst1, Platr27, Spock1, Ppy, Ctgf, Gpr6, Nlgn1, Nov, 1700015F17Rik
#> ℹ GLMPC_ 3
#> ℹ Positive:  Ncf2, P2ry14, Rac2, Cd37, Fcgr3, Ifitm1, Tyrobp, Slfn2, Tex36, Srgn
#> ℹ 	   Fn3krp, Prom2, Snai2, Bhlhe23, Gm16140, Laptm5, Gm11636, Tgm7, Cmklr1, Fgf8
#> ℹ 	   Gm8773, Siglece, Fam212b, Itgb7, Gm15567, Sema3g, Tox2, Neurog3, Pthlh, Bhlhe22
#> ℹ Negative:  Dkk2, Sparcl1, Fgb, Gm26633, Gcg, 4930539E08Rik, Lgr5, Galnt16, RP23-428N8.3, Tnni3
#> ℹ 	   Col6a1, Col1a2, Otc, Ctgf, Calb1, 4930426D05Rik, Gad2, Klhl14, Kng2, Crygn
#> ℹ 	   Ryr3, Col23a1, Doc2a, Gdf15, Barx2, Pid1, Zfp385b, 1700001C02Rik, Tac1, Hoxb4
#> ℹ GLMPC_ 4
#> ℹ Positive:  Kng2, Spns2, Pid1, Pif1, Cldn18, 4930539E08Rik, Noxred1, Il1r2, Slc4a10, Depdc1a
#> ℹ 	   Sapcd2, Ccnb1, Iqgap3, Espl1, Ryr3, Nusap1, Troap, Aurkb, Ckap2l, Npy
#> ℹ 	   Mxd3, Lmx1a, Neil3, Aurka, Esco2, Cdc25c, Casc5, Prc1, Kif11, Cbln1
#> ℹ Negative:  Islr, Cbln4, Ghrl, Sp140, Kcnj8, Irs4, Anxa1, Col1a1, Tex36, Foxd3
#> ℹ 	   Col6a1, Lrrtm3, Col1a2, Col23a1, Rac2, Arhgap22, Sst, Guca2a, Ngf, Sparcl1
#> ℹ 	   Col3a1, Kcne2, Gm17455, Avp, L1td1, Bhlhe23, Galnt16, Gpr6, St8sia2, Prickle2
#> ℹ GLMPC_ 5
#> ℹ Positive:  Anxa1, Cxcl10, Gast, Nepn, Fgf8, Gm29440, Cxcl16, Krt17, Ifit1bl1, Col3a1
#> ℹ 	   Ltb, Tagln, Ccl20, Col1a2, A930017K11Rik, Cypt3, Esyt3, Gm15640, Cttnbp2, Rerg
#> ℹ 	   RP23-4H17.3, Sytl2, Nrn1, Pole, Arhgap22, Zfp97, Colec12, Gm38112, Ngf, Plaur
#> ℹ Negative:  Cbln4, Dlgap1, Sparcl1, Ins1, Sst, Gsg1l, Sds, Npy, Gm6878, Oasl2
#> ℹ 	   Adam32, Olfml2a, Ins2, Gm11789, Fam71b, Gm28875, Pkd2l1, Guca2a, Sftpd, Rac2
#> ℹ 	   BC043934, Sp5, Tmem255b, Smpx, Syndig1l, Snai2, Aspm, P2ry2, Aif1, Atoh8
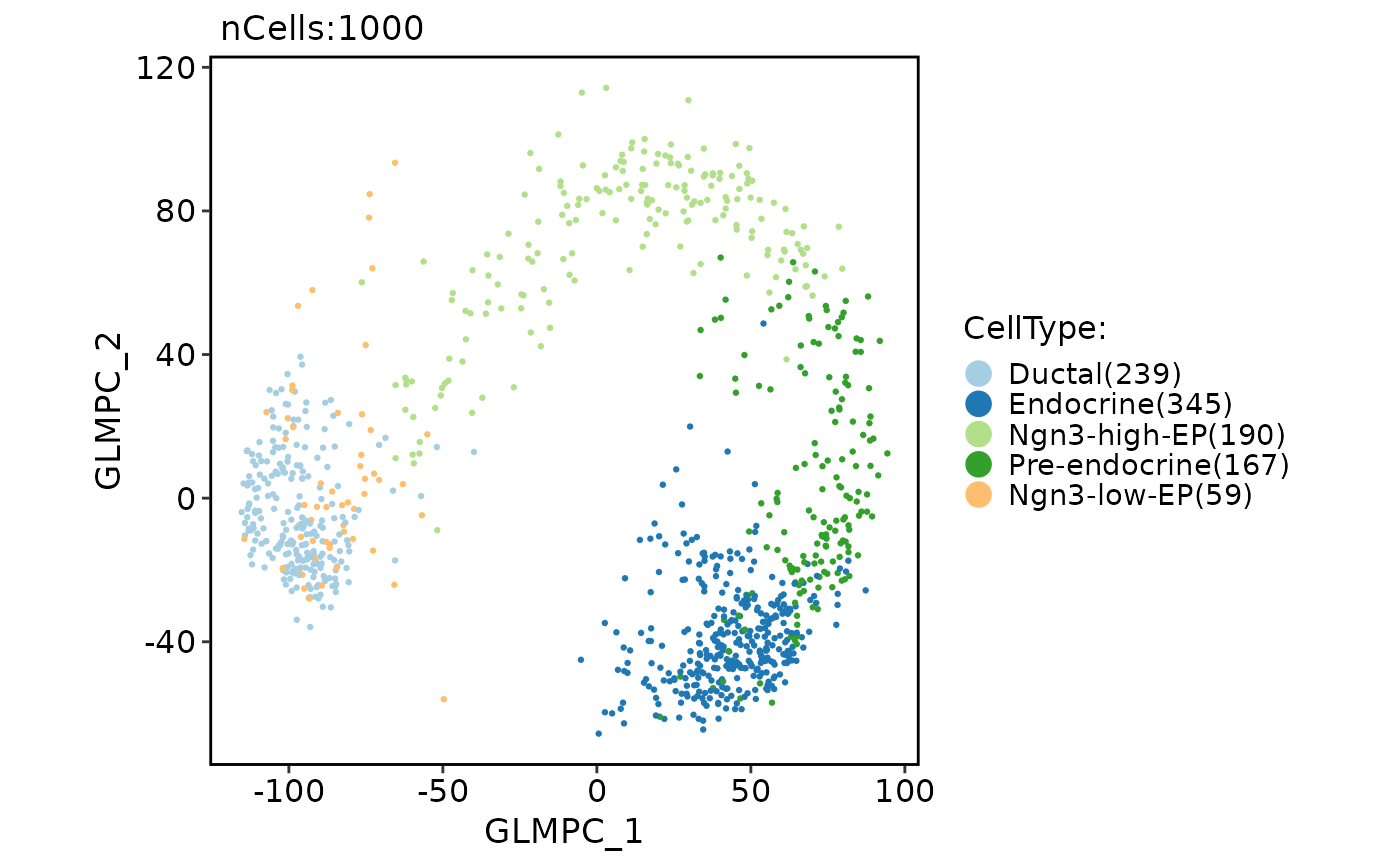
CellDimPlot(
  pancreas_sub,
  group.by = "CellType",
  reduction = "glmpca"
)